One Contract, Many Models
Where does each kind of provider win, on the same decisions?
This chapter runs no new experiment. It compiles the winner table from rows in
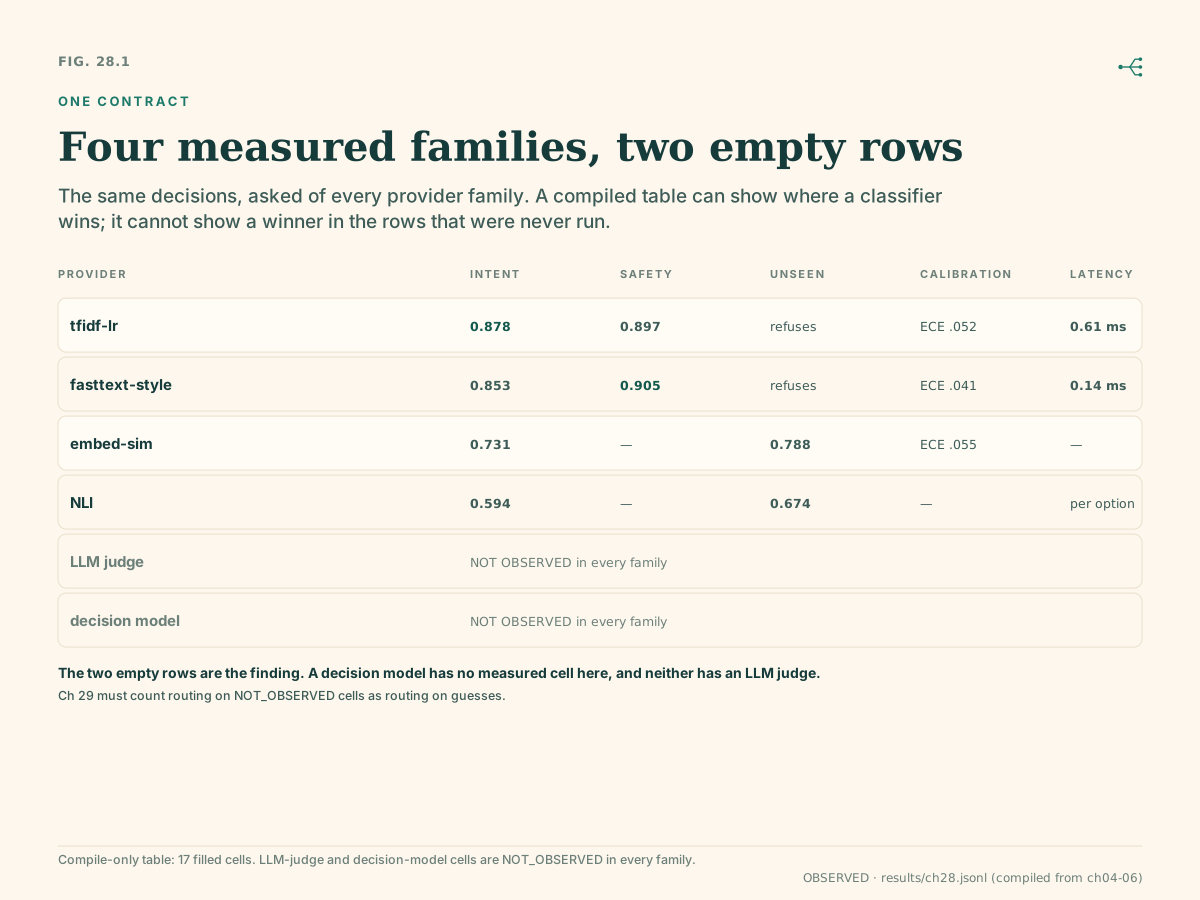
results/ch04.jsonl,ch05.jsonlandch06.jsonland marks every cell without a measuredsplit=testrow asNOT_OBSERVED. The number of filled cells (17) is smaller than the number of empty ones, and that is a result.
The question
Chapter 8 defined the contract every provider satisfies. This chapter asks the question the contract exists for: where does each kind of provider win, on the same decisions?
The honest scale of the answer is set by what is measured in this book: rule, majority, TF-IDF+LR, fastText-style, embedding zero-shot (bge), NLI (DeBERTa, BART) and a cross-encoder. An LLM judge and a decision model were never run here. The winner table therefore cannot be complete, and this chapter says so.
What the literature gives you
Three papers say how a comparison like this should be built. HELM’s metric and model counts were checked in the primary paper’s introduction. The setup-sensitivity discussion uses Biderman et al., §3.1, Table 1 and §4.2. BIG-bench is used at abstract level.
| Source | Principle | What it asks of this chapter | Where we fall short |
|---|---|---|---|
| HELM, Liang et al. (2022), §1, §3-§4, §6 | Measure several desiderata together. Seven metric categories (accuracy, calibration, robustness, fairness, bias, toxicity, efficiency), measured on the same scenarios, so trade-offs are visible. It evaluates 30 models under standardised conditions; it reports that calibration and accuracy relate differently on different scenarios (§1.2) | A winner table should not be accuracy alone | We have accuracy, calibration, shift behaviour and latency for some providers (see the coverage table), and nothing on fairness, bias or toxicity. HELM also makes its own gaps explicit; so should we |
| BIG-bench, Srivastava et al. (2022) | Breadth of tasks; aggregate scores hide structure | One “best provider” across all decisions is exactly an aggregate | Abstract-only. We use it for the framing, not for any number |
| Lessons from the Trenches, Biderman et al. (2024), §2-§4 | Small setup choices (prompt wording, whitespace, few-shot examples, averaging) change scores and even rankings; share prompts and code; report variance, not single runs; do not copy numbers across implementations | Every cell carries its prompt, seed and n |
Several cells are single runs, and the wording-sensitivity finding of Chapter 5 is the same phenomenon in our own data |
The two papers used at length agree on one point that matters for the rest of this chapter: a single number per provider hides the choices that produced it. HELM answers by multiplying metrics; Biderman et al. answer by exposing the setup. Our table does neither well, and the sections below say where.
The hypothesis and prior work
Our starting hypothesis follows H4 (HYPOTHESIS, preregistered): the decision-model region is real but narrow: many changing label sets, tight latency, few labels, probabilities needed. This chapter cannot test it, because no decision model was run. What it can do is show how much of the table exists, which determines how much of any later claim is more than a guess.
The filling rule
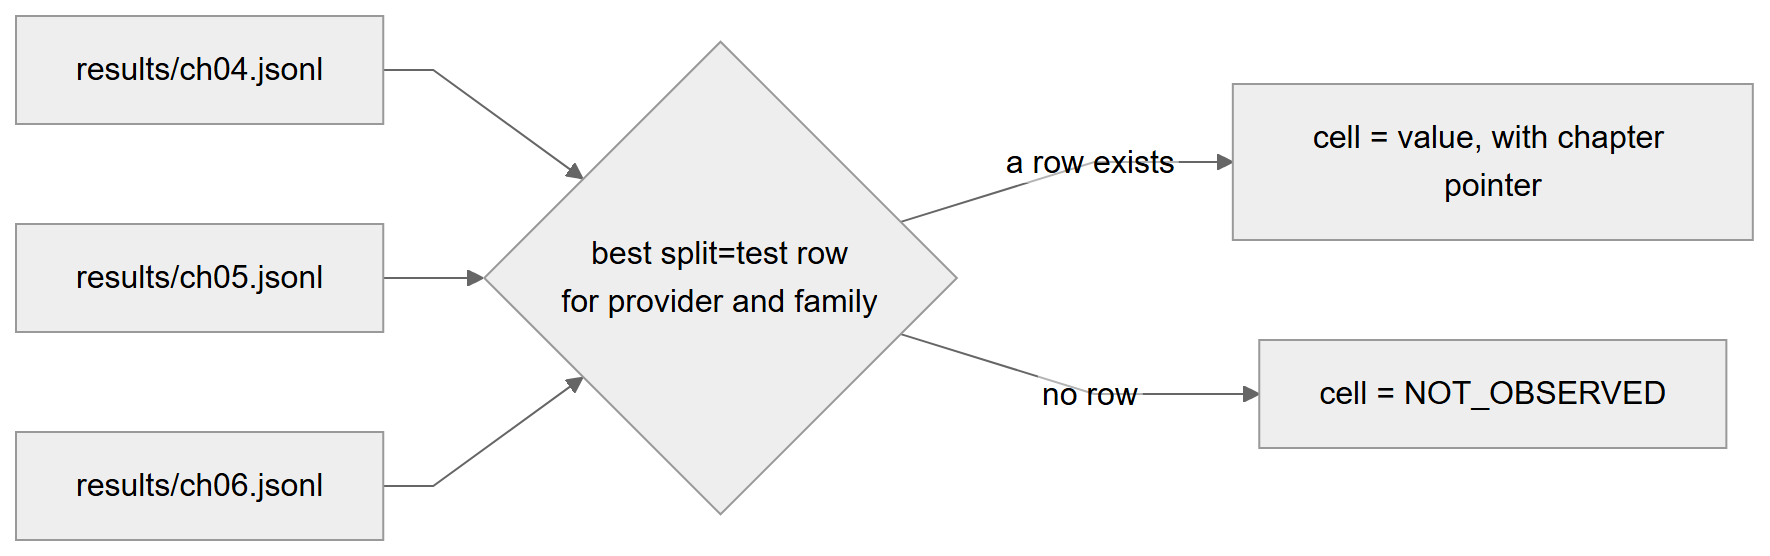
The runner benchmarks/great-decision-benchmark/winner_table.py reads the results files and, for each provider and decision family, takes the best measured split=test row; if none exists, the cell is NOT_OBSERVED. The walkthrough shows the rule on a tiny hand-made table.
# 1. The filling rule: split=test rows only, best value, NOT_OBSERVED else.
print("1. the filling rule")
v = best_test(ROWS, "tfidf-lr")
print(f"   tfidf-lr intent (tiny source): best test row = {v}")
# 2. Cells with no measured row stay NOT_OBSERVED.
print("2. empty cells")
for provider in ("cross-encoder", "llm-judge", "decision-model"):
    v = best_test(ROWS, provider)
    print(f"   {provider:<16} -> NOT_OBSERVED" if v == 0.0
          else f"   {provider:<16} -> {v}")
1. the filling rule
   tfidf-lr intent (tiny source): best test row = 0.8779
2. empty cells
   cross-encoder    -> NOT_OBSERVED
   llm-judge        -> NOT_OBSERVED
   decision-model   -> NOT_OBSERVED
The winner table
Best split=test accuracy per provider and family, compiled from results/ch04.jsonl, ch05.jsonl, ch06.jsonl (runner output; LLM-judge and decision-model cells are always NOT_OBSERVED):
| provider | intent ch04 | intent ch05 | intent ch06 | safety ch04 | safety ch06 |
|---|---|---|---|---|---|
| majority | 0.0130 | — | — | 0.4828 | — |
| rule | — | — | — | 0.4914 | — |
| lookup | 0.0130 | — | — | 0.4828 | — |
| tfidf-lr | 0.8779 | 0.9000 | 0.9000 | 0.8966 | 0.8966 |
| fasttext-style | 0.8526 | — | — | 0.9052 | — |
| embed-sim | — | 0.8029 | — | — | — |
| nli-deberta | — | — | 0.6735 | — | 0.5690 |
| nli-bart | — | — | 0.6706 | — | 0.5000 |
| cross-encoder | — | — | — | — | — |
| llm-judge | NOT_OBSERVED | ||||
| decision model | NOT_OBSERVED |
The table’s own caveats are visible in the rows: the Ch5 embed-sim cell is the unseen-label best (0.8029); the seen-label best is 0.7312 (Ch5). The Ch6 NLI intent cell (0.6735) is the intent-seen best; Chapter 6’s headline is that NLI loses to the embedding provider on unseen labels by 11.5 points. A max-on-test cell masks both distinctions, which is why the chapter reports the table and the chapters it cites.
Two ways the table flatters, which the rows do not show. First, each cell is the maximum over every split=test row for that provider, which includes every wording, template and seed the earlier chapters ran. A provider with many configurations (embedding similarity with four wordings, NLI with three templates) gets the best of several draws on the test split, and a provider with one configuration (tuned LR) gets one. That is selection on test, the practice this book otherwise forbids, and it favours the providers with more knobs. Second, the 17 filled cells are 15 distinct measurements: the tuned LR’s 0.9000 and 0.8966 each appear twice, because the Chapter 6 columns repeat the frozen Chapter 4 and 5 baselines that Chapter 6 refit to confirm. The columns also mix tasks (77-way intent, seen-60, unseen-17), so a value in one column is not a rival of a value in another. Read each column on its own, and treat the table as an inventory of what exists, not a leaderboard.
What is measured, by provider and by desideratum
HELM’s lesson is to put the metrics side by side. The table below uses its categories, and records where in this book each provider has a measurement, from the rows in results/ch04.jsonl to ch10.jsonl. A dash means no row exists. The cells name where to look; they are not values.
| provider | accuracy | calibration (ECE etc.) | robustness (shift split) | efficiency (latency) | fairness, bias, toxicity |
|---|---|---|---|---|---|
| majority, lookup, rule | Ch4 | Ch4 | — | Ch4 | — |
| tfidf-lr | Ch4, Ch5, Ch6 | Ch4, Ch9, Ch10 | Ch9 (shift minus test ECE) | Ch4, Ch5 | — |
| fasttext-style | Ch4 | Ch4, Ch9, Ch10 | Ch9 | Ch4 | — |
| embed-sim (bge) | Ch5 | Ch5, Ch9, Ch10 | Ch9 | Ch5 (CPU and CUDA) | — |
| nli-deberta, nli-bart | Ch6 | Ch6 | — | Ch6 (CPU and CUDA) | — |
| cross-encoder | Part VI only (relevance, not intent) | — | — | Part VI | — |
| LLM judge | — | — | — | — | — |
| decision model | — | — | — | — | — |
Two things stand out. First, even for the providers we did run, robustness exists for three of them and fairness for none, so the HELM-style comparison is incomplete before it reaches the missing providers. Second, the two rows that would carry the book’s central question are empty in every column. Counting by hand, 20 of the 40 cells in the table name a measurement (including the cross-encoder’s Part VI cells, which are a different task), and the two empty rows account for 10 of the 20 empty ones. That count is for orientation only, since the table is a map of where to look and not a set of equally weighted measurements.
What the providers can do, apart from how well
A winner table ranks providers on a number. Whether a provider can be substituted for another behind the contract of Chapter 8 depends on other things first: can it take labels supplied at run time, does it have a way to decline, what does its score mean, and what does it cost to serve. These are capabilities, and a provider that cannot do one has a gap that no accuracy figure shows. The table is a map of what this book established, with pointers; it contains no numbers of its own.
| provider | labels given at run time | way to decline | what its score is | serving profile measured |
|---|---|---|---|---|
| rule, majority, lookup | no (fixed) | the rule can fall through to a default | not a probability | Ch4 (latency) |
| tfidf-lr, fasttext-style | no: labels fixed at training (Ch4) | thresholding the top probability (Ch11 design) | a probability; calibration measured and shifted in Ch9, mapped in Ch10 | Ch4 |
| embed-sim (bge) | yes: label descriptions embedded at run time (Ch5) | thresholding the top similarity | a cosine similarity, not a probability until mapped; its scale changes ECE without changing accuracy (Ch9) | Ch5 (CPU and CUDA) |
| NLI (DeBERTa, BART) | yes: labels become hypotheses (Ch6) | thresholding entailment probability | an entailment probability; ECE is reported in the Chapter 6 rows, with no calibration map or shift test | Ch6 (CPU and CUDA; cost grows with the number of labels) |
| cross-encoder | yes (a query-passage pair) | thresholding the score (Ch22) | an unbounded relevance score; mapped to a probability by a fitted sigmoid in Ch22 | Part VI (24.70 ms per pair, CPU) |
| LLM judge | not run | not run | not run | not run |
| decision model (Jev) | vendor-described only (Chapter 2); not observed here | vendor-described only | vendor-described only | not run |
Two lessons come from reading this alongside the accuracy table. First, the two run-time-label providers measured on intent (embedding similarity and NLI) both lose to the tuned linear model on seen labels (Chapters 5 and 6), and win only where a trained model has no label at all; the cross-encoder was measured on a different task. The decision-model claim is about the run-time-label capability, and that is the capability this book could test only with weak providers. Second, wire compatibility is not substitutability. Chapter 8’s contract lets any provider answer the same call. It does not make a similarity and a calibrated probability the same quantity, and Chapter 9 showed that confusing the two moves a calibration number without moving accuracy.
Leads, not measurements. Two open-source projects, described here from their own READMEs (not run), sit in different cells of this table and would be worth adding as providers if the paused work resumes. Jeffy is described as frozen text encoders with logistic-regression heads and explicitly uncalibrated probabilities, so a fixed-label provider in the tuned-linear family whose encoder cost has to be counted. gutsy is described as a fine-tuned causal model with soft-label training, rejection and state caching, which discloses weaker calibration on unfamiliar items and self-run public-set results. Neither result is imported into this book.
Three sections, each only as far as the evidence
Where the tiny classifier wins. Measured, so it goes first. TF-IDF+LR holds the intent-77 row (0.8779 tuned, Ch4) and the safety-test row is held by fastText-style (0.9052, Ch4). On Ch5’s frozen split the tuned LR reaches 0.900 on seen labels and beats the embedding provider on seen labels by 17-30 points; on Ch6 it tops both NLI models. This is the book’s strongest provider result and it is a classifier.
Where an LLM judge wins. NOT_OBSERVED. No LLM judge has been run in this book, so there is no row to put in the cell. The adjacent evidence is on the judge’s slowest sibling: both NLI models trail the embedding provider (Ch6), which is not a statement about judges. This section exists to say what it cannot say.
Where a decision model wins. NOT_OBSERVED, and there is no region to describe. Every decision-model cell in the table is empty. H4 predicted a narrow region — changing label sets, tight latency, few labels, probabilities needed — but nothing in this book measures a decision model, so the region is a prediction, not a row. Chapter 35 must classify H4 as INSUFFICIENT_EVIDENCE, not as found.
Wrong / Correct. Wrong: “The benchmark shows where each provider wins.” Correct: “The benchmark shows where a classifier wins, and that the other regions are unmeasured. A table with seventeen filled cells and the rest
NOT_OBSERVEDis the honest result.”
What to carry forward
Chapter 29 routes between providers. The router needs cost and quality profiles per provider; this chapter’s honest message is that the quality side of those profiles exists for exactly the providers above, and NOT_OBSERVED for the rest. Routing on empty cells is routing on guesses, and the router chapter must count that.
Limitations
- Compilation only: no new provider run. Cells are best-
split=testrows and mask seen/unseen and wording distinctions carried in the cited chapters. - LLM-judge and decision-model rows are
NOT_OBSERVEDbecause those providers were never run; the fraction of filled cells is a statement about this book, not about the providers. - HELM is used for its opening sections, not its limitations sections (§10–§11); BIG-bench only for its abstract. HELM’s metric/model counts and Biderman et al.’s setup-sensitivity example and recommendations were checked in the primary texts linked above. This is a source check, not a reproduction of either evaluation.
- The same SciFact dev claims served as the “test” split in Chapters 21-23 and 25; Chapter 35’s audit states what that does to the Part VI pipeline claims.
- Per-unit-cost Pareto fronts are not drawn: cost and latency per provider exist in the cited chapters, and compiling them into one table was deferred to avoid mixing CPU, GPU and cache-economy figures.
What this chapter establishes
Is there any region where the decision model is the best choice? On the measured evidence, no region can be claimed: the cell is empty. The question is passed to Chapters 33 and 35 with INSUFFICIENT_EVIDENCE attached.