What Context Means
Separate context from prompts, context windows, session state, memory, retrieval, and the larger universe of information a system could access.
Consider a concrete evening. A developer asks a coding agent to fix a failing test. The typed message is eleven words long: “the checkout test fails after my last commit, please fix it.”
Behind those eleven words sits an organisation of information enormously larger than the request. The repository holds hundreds of thousands of lines of code. The version control history holds the last commit and every commit before it. The continuous integration log holds the actual failure output. The open editor holds the file the developer was viewing. The agent’s working directory holds shell history, environment variables, and configuration. Earlier in the session, the developer pasted an error trace, the agent ran two searches, and a linter produced three warnings nobody has read yet.
The model that must now act does not inspect the repository, logs, or editor by itself. It receives a rendered invocation assembled by the surrounding software: instructions, selected history, file excerpts, tool definitions, and other admitted material. The runtime may also expose tools that allow the model to request more information later, but those future observations are not yet part of this invocation. Perhaps the current request contains 40,000 input tokens; perhaps 4,000. (These figures are illustrative.) That difference reflects assembly choices, subject to the model and provider limits, and can change what the model does next.
This is the situation the book investigates. The word “context” is routinely used to mean six different things: the user’s prompt, the chat transcript, the model’s window size, the retrieved documents, the system’s memory, and sometimes the entire application state. These are not the same object. Until they are separated, no serious engineering is possible, because every measurement and every intervention will be aimed at the wrong layer.
Four things that are not the same thing
Start with the full universe of information. Call it available information: everything the surrounding system could potentially access. Source files, databases, web pages, prior sessions, teammates’ notes, sensor feeds, secrets in a vault. Available information can be vastly larger than a single invocation and may include material the system is technically capable of reaching but is not authorised to use. Availability does not imply permission, relevance, or admission. No practical invocation contains the entire information world, and most accessible material is unnecessary for the task.
Narrow to what the system keeps across interactions. Call it session state: information the surrounding software persists from one step to the next, whether or not the model currently sees it. Conversation history on disk, cached tool results, the plan file the agent wrote last turn, the authentication token, the compressed summary of yesterday’s work. Session state survives between invocations, and much of it may never be shown to the model again. It is the system’s record of the task so far. It is not the same thing as memory in the sense of the Memory book: history, cached results, plans and summaries can all be session state without being retained knowledge that is meant to change future behaviour.
Then there is what the model actually receives right now. This is context, and the book uses the word in exactly this sense throughout: the information made available to a model for a particular computation. The four things are not strictly nested, and the window is a different kind of thing from the other three: a capacity constraint on context, not a further body of information. Some context is copied or selected directly from session state or other available information. Other context is produced during assembly by transforming them, as when an instruction is rendered from a template and runtime state. If a file sits on disk but is not included in this invocation, it is available information and possibly session state, but it is not context. If a prior conversation turn is summarised and the summary is included, the summary is context and the original turn is not. Information outside the invocation cannot be used by the model in this computation, however relevant it is. It can affect a later computation only if the system carries it there, for example as a stored note or a tool result.
Finally, separate the capacity from the contents. The context window is capacity: the bounded budget, measured in tokens, that limits one model invocation. Providers account for it differently. OpenAI’s documentation, for example, says the limit covers input, output and reasoning tokens, and describes its text generation requests as independent and stateless unless the caller re-supplies state or uses its conversation-state features. Other runtimes store or rebuild state in other ways. The general concept is only that each invocation has a bounded budget. The window tells us how much the model can receive. It says nothing about which bits deserve to be inside.
In compact form, the runtime moves information from outside an invocation to inside it, and the window bounds what fits there:
    flowchart TB
    subgraph avail["Available information"]
        direction LR
        S["Session state<br/>persisted between steps"]
        O["Other available information<br/>files, stores, prior sessions"]
    end
    R("Runtime assembly<br/>selects, orders, represents")
    C["Context<br/>what this computation receives"]
    W(["Context window<br/>capacity that bounds the invocation"])
    S --> R
    O --> R
    R --> C
    W -.-> C
    C --> M["Model"]
The model does not automatically see the material in the outer box. It receives the context assembled for this invocation. If tools are available, it may request further observations; their results can enter a subsequent model invocation only through the runtime. The window constrains the total invocation budget, including any reserved output or reasoning allowance under the provider’s accounting rules. Assembly may transform source material rather than copy it verbatim, so the rendered context needs provenance back to the source.
Confusing any two of these produces characteristic errors, catalogued below. The most stubborn conflation is with the prompt. The user’s message is the most salient item in the bundle and the one the team laboured over, so it gets the attention while the rest of the invocation, which is usually most of it, goes unexamined. Skilful prompt engineering cannot compensate for a bundle whose other contents were assembled carelessly.
A definition to build on
The book’s primitive, stated once and used everywhere:
Context is the information made available to a model for a particular computation.
Three phrases in that sentence carry weight. “Made available” marks context as the product of an assembly process in which information is selected, ordered, and represented. “To a model” marks the boundary of influence: context is the input side of one inference step, not the system’s beliefs or the user’s intentions. “For a particular computation” marks its scope: context is per-invocation. The next invocation may carry a different bundle, and anything that must persist across invocations must be deliberately carried there. Put together, context is the boundary between information that exists and information that can participate in this inference. Most of the book studies the machinery above that boundary and its behavioural consequences below it.
The definition is this book’s operational convention, grounded in the per-request inputs exposed by major model interfaces. Provider documentation supports the existence of rendered inputs containing instructions, tool definitions, history, and sometimes media; it does not by itself establish that every provider uses the word context with precisely this scope. OpenAI’s prompt-caching documentation, for instance, describes the cacheable unit as the model’s “full rendered context” including provider instructions, developer messages, tool definitions, and conversation history. Anthropic’s engineering team defines context as the set of tokens included when sampling from a language model, and the engineering problem as optimising the utility of those tokens against the constraints of the model. The book adopts this shared interface reality as its foundation and builds the engineering discipline on top of it.
Capacity, content, representation, and time
Fixing the definition lets us decompose the problem. Three questions describe any one context bundle. A fourth dimension, time, describes how the bundle and its information change across computations:
                 CONTEXT
                    │
        ┌───────────┼───────────┐
        ↓           ↓           ↓
    CAPACITY      CONTENT      REPRESENTATION
    how much?     which bits?  represented how?
Capacity asks how much the invocation may carry: token budgets, output headroom, reasoning allowances. It is set by the model and the runtime, not by the task. Content asks which bits of the available information were admitted: which files, which history, which instructions, which tool results. Representation asks how the admitted bits were represented: raw prose or structured records, full logs or excerpts, exact tool schemas or paraphrases, chronological or grouped ordering.
The point of the decomposition is that a bundle can be adequate on one axis and inadequate on another. This is a diagnostic claim, not a claim that the axes are statistically independent: a richer representation, for instance, costs capacity. A bundle can fit comfortably in capacity yet contain the wrong bits: the file with the bug excluded, the misleading log included. It can contain the right bits in a representation the model mishandles, such as a wall of undifferentiated log text where a small table of failing assertions would do. And it can be excellent on all three axes for this turn and wrong for the next, because the session moved on while the bundle stood still. Capacity failures may appear as truncation or refusal. Content failures may produce answers that omit the decisive evidence, sometimes with no visible sign. Representation failures may leave the right information technically present but hard to use. These are characteristic possibilities, not reliable signatures, and none is a measured rate. Learning to tell the three apart is still half the book.
The decomposition also organises what follows. The rest of Part I (Chapters 2 to 7) stays close to observation: measuring what the model actually receives, exposing its hidden layers, treating capacity as a budget, and examining the evidence that more content and careless ordering can degrade behaviour. Later parts take up reduction, externalisation and recall, sources and representation, governance, and finally assembling one bundle, delivering it and asking whether it helped. The Introduction gives the full map.
The four dimensions do not rest on equal evidence. Capacity is documented by providers. Long-context effects of position and length come from the literature. The book’s own tests are small and synthetic, and concern content and representation as assembled and delivered (Chapters 23 to 26). What it says about time rests on engineering reasoning and the literature. This chapter defines the dimensions and does not establish them experimentally.
Time is what happens to the bundle between computations. Across a session, context accumulates as tools return observations; it becomes stale as the world changes underneath it; it is replaced when files are re-read; it is compressed when history is summarised; it leaves the window when truncated and sometimes returns through re-retrieval; it is reordered by harness logic; and the agent itself generates plans, notes and intermediate artefacts that become inputs to later steps. A definition of context that ignores time describes a single photograph of a moving object. This book treats context as the moving object, one computation at a time.
Context as an intervention on behaviour
Why insist on per-computation precision? Because the book’s central claim about method follows from it:
Book hypothesis. For a fixed model and task, changing the context bundle while holding everything else constant changes the distribution of behaviours, and that change is measurable.
This is a general hypothesis, not established background. It matters because it converts context from a vague background condition into an experimental intervention: something we vary deliberately and measure the consequences of.
The book has one narrow result that bears on it. On six synthetic tasks, with one reader model at temperature zero and one budget, changing only the bundle changed the reader’s parsed action on every task (Chapter 26). That is a result about that setting. It does not show a distribution of behaviour under sampling, other models, other budgets or real tasks, and it does not show that the change helped: the score improved on some tasks, worsened on one and was unchanged on others.
The hypothesis needs its counterfactual stated carefully. When a model samples, its behaviour varies from run to run even with identical inputs, so a single success under one bundle after a failure under another proves nothing, and the general claim is about distributions across repeated trials. The book’s own comparison took the other route. It fixed the reader, the prompt and the decoding configuration and graded deterministically, which suppresses sampling as an experimental variable and confines the result to that configuration, rather than estimating a distribution through repeated sampling. Either way the discipline is the same: without it, every observed improvement is suspect and every kept token is superstition.
The hypothesis also has a sharp edge. If two bundles produce indistinguishable observed behaviour under a specified test, that test has not detected an effect of the difference. This is not proof of equivalence: the evaluation may be insensitive, the sample too small, or the relevant failure absent. The proper conclusion is bounded by the model, task, decoding configuration, measurement, and number of trials. Conversely, if removing a single instruction collapses performance, that instruction earned its tokens. A null result narrows what is needed. It does not show that a mechanism is useless, only that it did not help here; the book’s later rule is that a mechanism earns a place in the architecture when it repairs a demonstrated failure at acceptable quality, cost, latency and complexity. In this book a usefulness claim has to be supported by comparison under stated conditions, and it holds only under those conditions.
That standard rules out several tempting non-experiments. A smaller prompt is not evidence of lower cost unless cost is measured. A fluent summary is not evidence of preserved information unless information survival is tested. Retrieved text sitting in the bundle is not evidence of improved behaviour unless behaviour is compared against the bundle without it. Each of these confusions recurs in later chapters attached to a specific mechanism; the discipline for resisting them is established here.
The same separation, away from code
The coding agent is this book’s running example, but the separation must hold everywhere. Take a research assistant asked: “does retrieval-augmented generation reduce hallucination rates?” The available information includes the entire literature, the open web, and the user’s private document store. The session state includes the three papers already discussed and the user’s stated preference for recent work. The context for the next invocation is narrower still: the system instructions, the current question, a short excerpt of the prior exchange, and the five passages a retriever returned, two of which contradict each other. The context window is the token budget all of that must fit within, minus room for the answer.
The same errors are available here. A team that believes retrieved documents are “what the model knows” will be surprised when the answer misses a passage that was retrieved but cut before the invocation, or one that sat in session state from an earlier turn and was not re-supplied. A team that believes session state is context will be surprised when the answer does not reflect the user’s stated preference, which the harness stored but the current bundle omitted. Each surprise is a category error with a precise address: something was available, or persisted, but not made available for this computation.
Five confusions and their symptoms
Each conflation has a recognisable symptom in practice, and diagnosing a context failure begins with locating which object is at fault.
- Available information mistaken for context. The model is expected to use information it was never shown: the unopened file, the unpasted log, the database row nobody queried. Symptom: “but it had access to the repo” offered as a rebuttal to a failure no invocation could have avoided.
- Session state mistaken for context. The model is expected to remember what the system merely stored. It sees only what the harness re-supplied, and re-supply involves truncation, reordering and summarisation. Symptom: surprise when a preference, decision or correction from ten turns ago vanishes.
- Context mistaken for the window. A large advertised limit is read as permission to include everything retrievable. Symptom: bundles grown until they fit rather than until they work. Fitting within the window does not guarantee that the model makes effective use of everything included; later chapters review the evidence and its limits.
- The window mistaken for context. Capacity planning substitutes for content selection. Symptom: teams that can quote their model’s token limit but cannot say how many tokens their own instructions consume.
- Context mistaken for the prompt. Effort goes to phrasing the user’s message while the rest of the bundle goes unexamined. Symptom: a carefully worded instruction that is contradicted by a stale note three positions earlier in the same invocation.
Most debugging that calls itself prompt engineering is really an unacknowledged search across these layers.
One bundle, eight turns later
Time deserves a concrete illustration, because static diagrams understate it. Return to the checkout-test session. The numbers below are invented for illustration and are not measurements. Turn one carries the user message, project file, tool definitions, and one source file: perhaps 9,000 tokens. By turn four, two tool results and a re-read file have joined; the bundle is 22,000 tokens and contains the same project file for the fourth time. At turn six the harness summarises the earliest turns, replacing 8,000 tokens of history with a 900-token condensation nobody verified. At turn eight the agent writes a plan note to its working state, which the harness now includes in every subsequent invocation. The user’s words across all eight turns total a few hundred tokens. The bundle grew several-fold, changed composition repeatedly, and acquired a self-generated layer, all without any new request from the user.
Every later mechanism in the book is an operation on this moving object: selecting what enters, preserving what must survive, compressing what can lose fidelity, removing what no longer matters, and recovering what left too early. The operations differ, but they share a precondition. They act on the rendered bundle, not on anyone’s impression of it.
How the book compares bundles
The smallest comparison that honours this standard takes one task with an externally checkable outcome, for example a failing test that must be made to pass without breaking others. Fix the model, the decoding settings and the task. Construct two bundles: one containing the task description plus the failing file, and one containing the same plus a document that is plausibly relevant but not necessary. Compare the outcome, the total rendered input tokens, and whether the tool calls differ.
This two-bundle design is an illustration of the method, and it has not been run as a standalone experiment. The comparison the book does run, in Chapter 26, is related but larger and different: six synthetic tasks and several bundle conditions per task.
A comparison supplies evidence that context mattered when its outcomes or traces differ under a controlled regime. A failure to detect a difference is a null observation under that regime, not proof that the bundles are behaviourally interchangeable. Under stochastic decoding, that means separating the effect from run-to-run variation. Under fixed decoding, it means showing a reproducible difference under that configuration. If neither differs in the recorded trial, the extra document consumed input tokens without a detected behavioural benefit in that trial; repeated trials or a stronger test may change the conclusion. That negative finding is as valuable as a positive one, and it is the first instance of the book’s method of keeping, revising or deleting a mechanism only on measured grounds.
Two design rules recur in every later comparison. First, the model and task are held constant while only the bundle varies. A comparison that changes the model version, the decoding settings and the context at once cannot attribute its outcome to context, and the book rejects such confounded comparisons wherever they appear. Second, behaviour is read from externally checkable outcomes and recorded traces, not from the model’s own account of what helped. Asking the model whether the extra document was useful produces fluent testimony. Running the task with and without it produces evidence.
Note what this design does not require: no retrieval system, no summariser, no cache analysis, no agent architecture. It requires the ability to render two exact bundles and count what happened. That ability is the subject of the next chapter, and it is harder to obtain than it sounds.
Inspect this in the Context Viewer
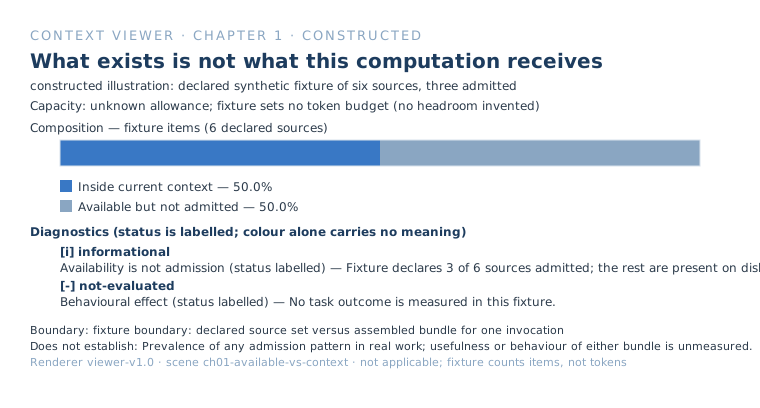
The viewer scene for this chapter shows the opening distinction as a declared fixture: six available sources, three admitted to the bundle for one computation. Open the scene and check which items sit inside the current context and which remain available but outside it. What to examine: the line between session state carried across steps and context assembled for this step. This is a constructed illustration of the vocabulary, not a measurement; nothing here says which admission pattern is typical or whether it helps.
Open the working-set scene in the Context Viewer
Boundaries
This chapter establishes vocabulary, not mechanisms. Neighbouring subjects are taken only as far as context needs them.
Prompt engineering concerns how instructions and content are expressed. Context engineering additionally concerns what is admitted, how it is represented, ordered, governed and delivered. The two overlap, and nothing here diminishes careful phrasing. The point is that phrasing acts on a bundle whose other contents matter too.
Memory concerns durable retained information capable of affecting future behaviour. A memory record is not context merely because it exists; it becomes context when it is admitted to a computation. Session state is likewise not automatically memory. The storage, consolidation and forgetting of durable records belong to the Memory book, and memory appears here as a source of context.
Retrieval supplies candidate information. This book takes retrieval results as candidates and concentrates on the admission, representation, assembly, delivery and evaluation that follow. Retrieval and assembly may interact in practice, and the boundary is conceptual and not a fixed sequence. Ranking, indexing and embeddings belong to the Embeddings book and to retrieval books.
Agents and tools matter here for two reasons. Agents repeatedly consume context and generate potential future context, and tool definitions consume the window. A tool result is potential context until a later computation receives it. Agent architecture is outside the book’s scope, and evaluation and inference appear only as the means of judging context interventions and the substrate that runs them.
If the chapter is reduced to one idea, it is the four-way separation. Available information is what exists. Session state is what the system keeps. Context is what this computation receives. The window is how much it may receive. Every later chapter is an investigation of how to choose the third item wisely given the fourth, while the first two press in from outside. Information exists, some of it is persisted, some is selected and represented, and one computation receives it. What it receives is context, the window bounds it, it changes over time, and changing it may change behaviour.
None of that is usable until the received context can be seen. Every operation the book goes on to study acts on the rendered bundle, not on anyone’s impression of it. So the next question is a practical one:
How do we know what the model actually received?
Not the user’s visible prompt. The whole rendered invocation.
References
- Anthropic Applied AI team. “Effective context engineering for AI agents.” Published 29 September 2025. First-party engineering writing. Defines context as tokens included when sampling; smallest high-signal set as guiding principle. https://www.anthropic.com/engineering/effective-context-engineering-for-ai-agents
- OpenAI. “Conversation state.” Official documentation, verified September 2026. Stateless per-request model; context window covers input, output, and reasoning tokens. https://developers.openai.com/api/docs/guides/conversation-state
- OpenAI. “Prompt caching.” Official documentation, verified September 2026. Cacheable unit is the full rendered context. https://developers.openai.com/api/docs/guides/prompt-caching
Research
Not yet researched
This chapter has not yet been researched.