Reuse Before Recompute
Treat cross-request prefix reuse as an economic and structural property of a context's layout: when repeated context need not mean repeated computation, how that reuse is measured, and why cacheability says nothing about whether content belongs.
Here is an illustrative scenario, not a measured case. A team running a long debugging session acts on what the Chapter 2 instrument showed. Their traces show 20,000 tokens of duplicate file reads and obsolete tool output, so they add a cleanup pass that strips them before every request. The visible token count falls by a sixth. Suppose the next invoice rises and latency does not improve. The visible count fell, but provider accounting can price newly processed, cache-written and cache-read tokens differently, and a cleanup that edits early history can change which of them a request contains. A smaller rendered request is not necessarily the cheaper request:
token-minimal ≠ cost-minimal
Chapter 8 ended on a counterfactual: without cross-request reuse, repeated stable prefixes would require repeated processing. This chapter asks what serving systems actually reuse, how that reuse is measured, and how a change to the context alters its value. It is a chapter about economics and layout, not capacity.
Two caches, held apart
Chapter 8 separated model inference state from cross-request prefix reuse. Model inference state is what the model and serving architecture use across the decode steps of one generation. Cross-request reuse is a serving-layer mechanism: when a new request is compatible with prior processing under a provider’s rules, some of that work is not repeated.
Providers name and implement it differently. OpenAI documents cached state living on individual machines, so requests have to reach the right one. SGLang’s RadixAttention, an open serving system, organises prompts in a radix tree so that requests sharing prefixes reuse KV-cache computation. It shows the principle is not proprietary and licenses no inference about any commercial provider’s internals. This chapter says “cross-request reuse” for the general idea and uses each provider’s own term for its feature.
Repeated context need not mean repeated computation
An agent session is a study in repetition. A hundred turns may all begin with the same instructions, tool definitions, project rules and early history, diverging only at the latest observations:
request 1    process A B C D
request 2    process A B C D E
request 3    process A B C D E F
With reuse, the shared work happens once:
request 1    compute A B C D
request 2    reuse A B C D, compute E
request 3    reuse A B C D E, compute F
repeated context ≠ repeated computation
But that holds only under conditions, and there are three levels to keep apart:
structurally reusable   two rendered requests share a leading region
        ↓
provider-eligible       the provider's rules make some of it eligible
        ↓
realised reuse          telemetry shows it was actually reused
A shared prefix is not a cache-eligible prefix, and neither is a cache hit:
shared prefix ≠ cache-eligible prefix ≠ cache hit
Between eligibility and a hit sit availability and routing: a compatible entry must have been created, must still be available, and must be reachable by the request under the serving system’s rules. Provider usage telemetry can report realised cache reads or hits, but it need not reveal why an eligible prefix missed or which particular span was reused. The observer therefore records provider-reported reuse separately from the structural prefix measured at its own boundary, and uses “reusable” only for that structural level.
Prefix geometry
Take R1 = A B C D E and R2 = A B C D F. Their common leading region is A B C D. At the first divergence, E against F, structural reuse stops, because nothing about the matched region certifies what follows. That is the book’s abstraction, prefix geometry:
common leading region  → candidate reuse
first divergence       → new processing required
It is not a provider’s algorithm. Implementations differ in block granularity, minimum cacheable lengths, breakpoints, lookback windows, routing, lifetimes and whether reuse is automatic or explicit. Geometry describes what could be reused, and provider rules and telemetry describe what was.
Stability is not position
The geometry makes a second axis visible. Chapter 6 concluded that rendered order can be behaviourally relevant and that layout has to be explicit. Chapter 9 adds a different axis: stability across invocations, whether an item is unchanged between one request and the next. Position and stability are independent:
position ≠ stability
An item can be early and volatile, early and stable, late and volatile, or late and stable. Where an item sits and how often it changes are separate facts.
A cache-oriented candidate layout follows. If semantic and policy constraints permit several equivalent layouts, placing stable material before volatile material can enlarge the structurally reusable prefix:
STABLE       instructions, tool definitions, shared reference
SEMI-STABLE  history, earlier tool results
DYNAMIC      current state, latest observation, current request
The documented guidance of three providers shares a preference for stable prefixes, but its controls differ. OpenAI advises placing stable developer instructions and shared reference material early and appending messages rather than repeatedly rewriting them. Anthropic documents cache breakpoints and an invalidation hierarchy covering tools, system and messages; a breakpoint must cover a prefix that remains identical across requests intended to share it. Kimi likewise advises stable prompts, tool definitions and reference material before per-turn content. The DeepSeek caching page cited here gives no comparable layout prescription. These are provider-specific instructions, not evidence that the same breakpoint strategy or lifetime applies everywhere, and none establishes behavioural equivalence after reordering.
Cache optimisation is constrained optimisation. It chooses among layouts already permitted by semantic, authority, scope, freshness and behavioural requirements, and it is invalid where it violates one of them:
layouts valid under the system's requirements
  ∩ authority and scope requirements
  ∩ freshness requirements
  ∩ behavioural constraints
        ↓
remaining layout freedom
        ↓
cache optimisation
That is a design principle, not an experimentally established law, and it does not rank the requirements against each other. A layout that gains hits by violating the governing context policy is semantically invalid, however cheap it is. Cache-optimal order and behaviour-optimal order need not coincide, as Chapter 6 said, and a layout has to state which it optimises.
Append and rewrite
History can grow by addition or by revision, and reuse prices the two differently. Append-only growth can preserve structural compatibility with earlier prefix computation:
turn 1    A B
turn 2    A B C
turn 3    A B C D
Each turn extends the last, so the structurally reusable region can grow. Whether earlier computation is still available depends on lifetime, routing, block boundaries and configuration, and structural compatibility is not realised reuse. Rewrite does the opposite:
turn 3    A SUMMARY(B C)
turn 4    A SUMMARY2(B C D) E
The rewritten request can be shorter, but a rewrite does not necessarily move the first divergence earlier on every subsequent turn. In the example, changing SUMMARY(B C) into SUMMARY2(B C D) makes the requests diverge at the summary, so material after that point is no longer part of their common leading region. A summary that remains byte-identical on later requests can itself become part of a reusable prefix. The trade inherited by pruning, compression and fading is therefore conditional: less admitted context can come at the cost of losing reuse already available under the previous layout. Token totals alone cannot establish either the cache effect or its price.
Inspect this in the Context Viewer
The viewer scene for this chapter draws the chapter’s own prefix geometry: same-sized edits at declared positions 4, 50 and 94 on the 0–100 axis, each with its structurally reusable prefix and recomputed tail. Open the scene and compare footprints by position. What to examine: where the first divergence falls, and how much stays structurally reusable. Geometry describes candidacy only — availability, routing, expiry and pricing decide whether structural loss becomes realised cost, and none of that is observed here.
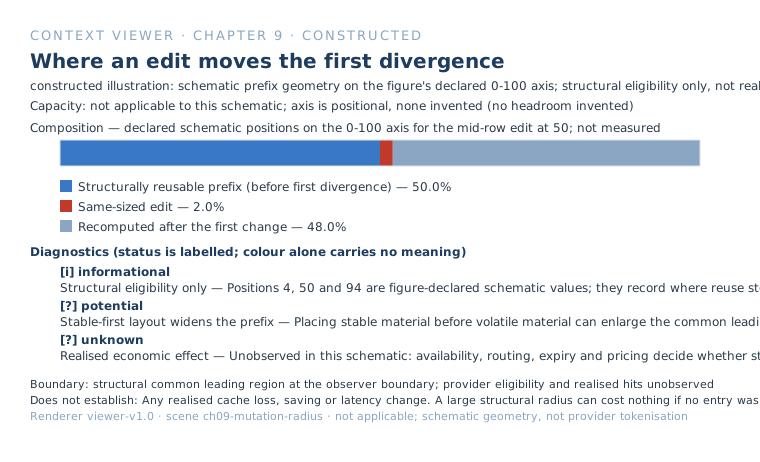
Open the prefix scene in the Context Viewer
Mutation radius
A small edit early can change a large part of the reusable region, and the concept deserves a name because a count of changed tokens misses it. Structural mutation radius is the portion of a specified reference request’s previously common leading region that falls after the first divergence introduced by a mutation. It must be defined relative to that reference request: record the reference prefix length, the mutated prefix length, the first-divergence offset and the difference under a stated local rendering and counting method. The Chapter 2 observer measures the host-boundary representation, not the provider’s final tokenisation or cache-block boundaries. Thus structural radius is an accounting diagnostic, not a direct measurement of provider-eligible or realised cache loss; no universal scalar is assumed.
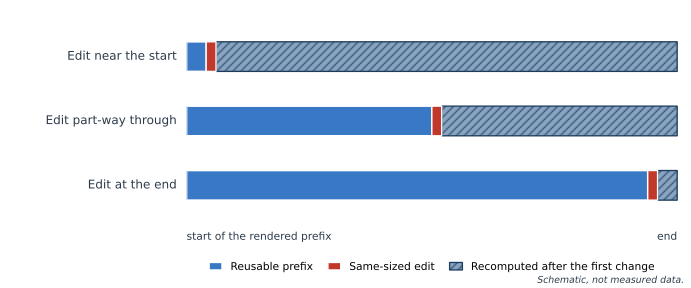
The asymmetry is that a small edit is not necessarily a small footprint:
small edit size ≠ small structural footprint
Documentation shows variants of the effect. OpenAI lists compaction and extending a message among the ways a prefix can change, Anthropic gives a timestamp trap in which a breakpoint on a per-request block writes an entry every request and never reads one, and Kimi states that when any part of a prefix changes, the content after that position cannot be reused.
Structural radius is not realised loss:
mutation radius ≠ realised cache loss
A large structural radius can carry no realised cost, for instance when no matching cache entry was available even before the edit. Conversely, provider-reported cache reads can change for reasons other than the mutation, including routing, expiry and request timing. The experiment below therefore compares structural measurements with usage telemetry, derived charges and latency rather than attributing every miss to layout. Later pruning and rewriting studies should record first divergence alongside token savings when their capture permits it, but promote mutation radius as an operational optimisation metric only if controlled evidence shows that it predicts a useful realised outcome.
Accounting, billing and latency
A reusable prefix is not necessarily free to create. For an economic comparison, distinguish the first request that establishes eligible or cached state, subsequent requests that report cache reads, and processing of the uncached remainder. These are accounting categories, not a claim that the provider literally performs three separate operations or bills them in a uniform way. The cost of producing a cache entry, the chance that it remains available, and the number of later eligible requests determine whether reuse is worthwhile.
request accounting
  first use:  input processed, and possibly cache state written
  later use: cached-prefix tokens reported as reused
             + uncached input tokens processed

reported reuse is not newly recomputed input
That is not a provider’s billing model. Providers differ in whether a write is a separate charge, and different token categories may be priced differently, so computation accounting ≠ provider billing, and billing is not latency.
Under one common structure the arithmetic is simple. Let w be the write multiplier and r the read multiplier, relative to ordinary input, and N the number of uses. Caching costs w + (N−1)r against N uncached, so it is cheaper when N > (w − r)/(1 − r). With OpenAI’s current models (write 1.25×, read 0.1×, from the September 2026 documentation) that is about 1.28, so the second use already crosses the simple input-price break-even. The same holds for Anthropic’s five-minute writes (1.25×) and its default read multiplier (0.1×); its one-hour writes (2×) need a third use. This ignores suffix cost, partial hits, expiry, minimum lengths, routing misses and latency, and it says nothing about behaviour.
Provider implementations differ, and are dated examples and not laws:
| Provider | Reuse mode | Eligibility and matching | Lifetime | Telemetry | Pricing (checked September 2026) |
|---|---|---|---|---|---|
| OpenAI, GPT-5.6 and later | Implicit or explicit breakpoints, up to four writes per request | 1,024 visible input tokens minimum | 30 minutes, refreshed on reuse | cached_tokens, cache_write_tokens |
Write 1.25×, read 0.1× |
| OpenAI, earlier models | Implicit | Varies by request settings | About 5–10 minutes of inactivity, up to an hour | Cached tokens | No extra write charge; read rate model-dependent |
| Anthropic | Automatic or explicit breakpoints, up to four | Minimum 512 to 4,096 tokens by model; 20-position lookback; writes only at breakpoints | 5 minutes or 1 hour, measured from request start, refreshed free on use | Creation, read and post-breakpoint tokens | Write 1.25× (5 min) or 2× (1 hour); read 0.1×, with lower rates on some models |
| DeepSeek | Automatic, on-disk | Full match of a cache prefix unit | Cleared after a few hours to a few days; best effort | Hit and miss tokens | Separate hit and miss input prices; no separate write charge on the pages checked |
| Kimi | Automatic | Block granularity; a partial block counts as a miss | 5 minutes or 1 hour, locked at first write | Cached and write tokens | For one model, cached input one tenth of uncached |
These rows are not directly comparable, and no composite score across providers is proposed. Lifetime matters because a miss proves nothing about layout on its own: identical prefixes can miss across expiry, routing changes and configuration changes.
The minimum-length floor
Some providers decline to cache short prefixes, so below the floor a perfectly stable prefix earns no reuse. The earlier draft’s claim that a prefix needs “a hundred-plus tokens” to justify expansion does not follow from the floor alone, so here is the derivation. Suppose an uncached stable prompt of L₀ tokens sits below a floor F, and adding material lifts it to F, so that it becomes cache-eligible. Ignoring the suffix, caching wins over N requests if F(w + (N−1)r) < N·L₀, that is, if L₀ > F(w + (N−1)r)/N. With F = 1,024, w = 1.25 and r = 0.1, L₀ must exceed about 220 tokens at N = 10, about 114 at N = 100, and about 102 as N grows without limit. So the figure of roughly a hundred tokens is a many-reuse limit. It counts only billing, treats the added tokens as costing only the read rate, and ignores their capacity and interference cost.
This is not a recommendation to pad. Adding content to qualify for caching is not justified by that:
cache eligibility ≠ admission justification
If useful stable material already belongs in the bundle, caching changes its economics. It does not make otherwise unnecessary material admissible, and padding brings the bloat and interference risks Chapter 5 requires us to measure.
Breakpoints and reuse decisions
Where providers expose explicit breakpoints, choosing one expresses a runtime expectation that the preceding region will be reused enough to justify caching under that provider’s rules. Breakpoint placement is a policy about which computation to make reusable, not about which content belongs in context:
content admission ≠ reuse admission
Stable material in practice
Stable tool definitions reused across many requests can be strong cache candidates when the provider’s matching, minimum-length and lifetime rules make them eligible, and mutating one schema per request early in the order can shorten the reusable prefix for everything after it. OpenAI advises consistent definitions and order, and its tool search with deferred loading so discovered tools are appended late. That is a provider optimisation and not a general law, and tool design belongs to Chapter 17. Tool definitions have standing occupancy in the window, and caching changes their price and latency, not whether they occupy capacity.
Project instruction files can likewise be stable across many requests, until a current time, session identifier or live branch status is embedded in an early block. Rendering dynamic values later can improve prefix stability, but behavioural equivalence has to be preserved or tested, since moving a value can change position and adjacency.
Retention policy and cacheability are independent axes:
retention obligation ≠ cacheability
A PIN-governed item that changes every turn, such as a live deployment lock, can be poorly reusable, and a stable reference file can be eminently cacheable. Predicted cacheability, expected reuse under layout and provider assumptions, differs from realised cacheability, which is observed. The chapter adds no new label for it. The observer’s provider-reported usage is the provider’s account of processing, joined afterwards. It does not attribute cache reads to individual spans, so per-span read ratios are not directly observed and, where wanted, have to be derived or measured by controlled requests.
Cacheability is not relevance
A span’s hit rate says nothing about whether it should be there. A cached irrelevance is still an irrelevance, and an uncacheable necessity is not waste because it misses.
cacheability ≠ context value
Caching does not establish relevance, freshness, authority, the absence of interference or the absence of bloat. It reduces recomputation, latency and input-processing cost where reuse is realised. On Anthropic’s documentation, cached prefixes still occupy the context window: caching changes what is paid, not whether tokens count. OpenAI’s page does not say. Hence the chapter’s cleanest sentence:
Caching can make bad context cheaper.
That is why caching and selection are complements. Selection decides what deserves to be present, and reuse decides what repeated presence costs. Content policy asks what deserves to be present, retention policy what representation must survive, layout policy where it may appear, and reuse policy which prior computation is worth preserving. They interact and are not interchangeable.
Proposed experiment
Nothing here has been run. The companion design is optional and would run only if the ecological corpus establishes a plausible opportunity for cross-request reuse, or a separately documented pilot establishes one. Captured byte-identical prefixes alone cannot demonstrate that a provider made them eligible, that entries remained available, or that a measurable economic effect existed to test.
What is tested. Whether the location of an equivalent mutation changes realised reuse, cost or latency under one provider’s caching. That the structural radius differs is deterministic from the rendered requests and needs no inference calls. The empirical claim is the realised consequence.
Unit of analysis. One frozen request-sequence fixture under one provider, model and cache configuration. Fixtures, conditions, repetitions, providers and timing intervals are reported separately, and repeated requests inside one cache lifecycle are not independent observations.
Two families, not one contrast. In the mutation-position family, an otherwise identical fixed-length inert field is changed at an early or late location. Keep total rendered length, the field’s size, the changed-token count, the substantive task and the surrounding content fixed as far as the provider’s rendering permits; confirm the actual rendered requests rather than trusting the source templates. The length of the suffix after the mutation cannot be matched between early and late conditions, because it is precisely what the position manipulation changes. Record that suffix length and the first-divergence position as outcomes of the manipulation. In the rewrite family, replace an older segment with a mechanically built fixed-length stand-in; analyse it separately because its intervention changes more than mutation position.
Conditions. A warm stable control establishes the realised reuse available at that moment. Then early mutation, late mutation, append-only growth, rewrite, and a cold or churn control that prevents reuse. Each condition has to identify something the others do not.
Timing. Mutation location and expiry are separate factors. Prime the relevant cache state using a documented warm-up sequence; then randomise or counterbalance the order of early and late mutation conditions across independent cache lifecycles, with a stable control nearby in time. Requests issued promptly after warming limit, but do not eliminate, expiry and routing confounds. Repeat the stable control at specified intervals to describe availability decay, and record actual elapsed time rather than treating a nominal provider lifetime as proof that an entry remained reachable.
Measurements, recorded separately. Structural: captured representation size, estimated or provider-reported token counts with their origin labels, first-divergence offset, and common-prefix length before and after the mutation. Provider telemetry: cache creation, reads, misses or uncached tokens only where the selected API actually reports them, plus the raw usage record. Economics: derived charges from a recorded provider, model, pricing mode, currency and effective date, distinguishing estimates from actual invoices and including any separately reported write charges. Timing: time to first token when instrumented, and total latency if measured. An unavailable field is unobserved, not zero; changes in reported cache-read tokens are evidence of reported reuse, not direct observations of internal computation or its cause. Providers are analysed separately, not combined into a composite score.
Outcomes. Early mutation produces less provider-reported reuse than the equivalent late mutation, while nearby stable controls hit: mutation position is supported as an operational lever for the tested configuration, subject to the recorded uncertainty. Structural radius differs but realised reuse does not: the predicted geometric difference has not produced an observed operational difference. Neither mutation changes reuse: no mutation-position benefit is demonstrated under these conditions, not proof that it can never matter. Stable controls frequently miss: cache availability, routing or the experimental setup prevents clean attribution. Reuse changes without a detectable price difference: the economic case is not established here. Derived cost changes but latency does not: no latency improvement is claimed. Telemetry or repetition is insufficient: report an unresolved result rather than a negative finding. Report effect sizes, repeated-lifecycle variability and the comparison rule before claiming a useful difference.
If equivalent early and late mutations produce no measurable difference in realised reuse, provider-reported uncached processing, derived cost or latency, the book cannot use mutation position as an optimisation lever for that tested configuration. Structural geometry survives either way.
What removal must account for
Return to the opening scenario, with its invented figures: 120,000 tokens in context, 80,000 cached, 20,000 of them duplicate reads and obsolete output. Caching reduced their processing cost and did not change their membership. Deletion changes more than occupancy. A decision ledger, not an equation, lists what a removal may affect:
| Dimension | Effect of a removal |
|---|---|
| Capacity | Occupancy falls |
| Processing and economics | Repeated processing falls; realised reuse may be lost |
| Behaviour | Interference may fall; task performance may change |
| Information | Loss risk rises |
| Structure | The first divergence may move earlier |
The terms are not commensurate and must not be summed without a defined utility model. Removing material always changes the captured representation’s membership if the removal succeeds, but it does not guarantee lower realised processing cost: a prefix invalidation can outweigh the saving under some pricing and reuse conditions. The behavioural and informational effects must be assessed separately, and a deletion may have no cache consequence if the affected region was never eligible or its entry had expired. The next chapter can begin deletion with that warning:
Which context can be removed without losing required information, and without destroying reuse whose value exceeds the benefit of removal?
References
- OpenAI. “Prompt caching.” Official documentation, verified September 2026. Behaviour differs by model generation: write and read multipliers, lifetimes, explicit and implicit breakpoints, minimum length, routing, layout guidance, prefix-change gotchas. Provider-specific and version-sensitive. https://developers.openai.com/api/docs/guides/prompt-caching
- Anthropic. “Prompt caching.” Official documentation, verified September 2026. Automatic and explicit breakpoints, write and read multipliers with model exceptions, lifetime from request start with free refresh, 20-position lookback, minimum lengths, invalidation hierarchy, timestamp trap. Provider-specific and version-sensitive. https://platform.claude.com/docs/en/build-with-claude/prompt-caching
- Anthropic. “Context windows.” Official documentation, verified September 2026. Cached prefixes still occupy the context window. https://platform.claude.com/docs/en/build-with-claude/context-windows
- DeepSeek. “Context Caching” and “Models & Pricing.” Official documentation, verified September 2026. Automatic on-disk caching, full-match rule, hit and miss telemetry, best-effort lifetime; separate hit and miss input prices. https://api-docs.deepseek.com/guides/kv_cache
- Moonshot AI. “Use the Context Caching Feature of Kimi API.” Official documentation, verified September 2026. Automatic caching, five-minute or one-hour lifetimes locked at first write, block granularity, stable-first layout advice. https://platform.kimi.ai/docs/guide/use-context-caching-feature-of-kimi-api
- Zheng, L., Yin, L., Xie, Z., et al. “SGLang: Efficient Execution of Structured Language Model Programs.” Preprint, arXiv:2312.07104. RadixAttention for KV-cache reuse in an open serving system. https://arxiv.org/abs/2312.07104
Research
Not yet researched
This chapter has not yet been researched.