The Agent Writes Its Own Context
Govern what an agent produces before it becomes future context: status, evidence lineage, lifecycle and correction, so that persistence cannot pass for confirmation.
A debugging agent hits a failing migration test, guesses duplicated tenant identifiers as the cause, and records the guess in its progress file. The scenario is illustrative. Twenty turns later the window has reset. A fresh invocation reads the file, finds “Root cause: duplicated tenant IDs,” and plans the rest of its work around a fact nobody established. The test output that prompted the guess is gone. The guess survived, and the evidence did not.
Several events need to be distinguished: the agent recorded a hypothesis as a root cause, the supporting observation was no longer available to the next invocation, the persisted wording failed to preserve uncertainty, and a later computation acted on the statement as fact. Persistence and readmission were successful operations in a narrow technical sense; their failure was to carry an inadequately qualified claim forward. The diagnostic categories must therefore name both a successful handoff and a failed epistemic contract:
initial error ≠ persistence failure ≠ status-preservation failure ≠ readmission failure ≠ downstream use failure
Chapters 10 to 14 govern what is removed, transformed, stored and readmitted, but they do not by themselves validate claims an agent creates. Those operations can faithfully carry an unsupported proposition into a new invocation. This chapter asks what status, provenance, lifecycle and correction semantics must accompany information an agent produces, so that a temporary interpretation is not silently promoted to durable evidence.
The candidate universe does not stand still
Chapter 14’s pipeline omitted the arrow that matters most once an agent acts:
    flowchart TD
    C["Context, step t"] --> M["Model"]
    M --> A["Action"]
    A --> O["Observation<br/>what the environment reported"]
    A --> G["Generated state<br/>plans, notes, hypotheses, reports"]
    O --> S["Available state"]
    G --> S
    S --> K["Future candidates"]
    K --> D{"Admission ([Chapter 14](/books/context/14-chapter/))"}
    D --> N["Context, step t+n"]
Actions can produce observations, and agents can produce notes or interpretations about those observations. Either may be persisted, indexed or made eligible for later admission, but those transitions do not happen automatically. Each link is a separate step, and a model-generated note and a tool-produced observation should retain different producer identities:
action produces information ≠ it persists ≠ it becomes a candidate
        ≠ it is admitted ≠ it becomes context
Agent execution therefore changes the information environment of future agent execution. The agent initiates the interaction, whether a query, a file or a test, and the environment or tool produces the observation. Choosing the interaction influences which evidence becomes available without determining what that evidence will report, since environments can be stochastic or changing. The same initial context need not lead to the same future context when actions or outcomes diverge, and exact replay of a production trajectory is often unavailable or expensive. What the tools do to the world belongs to Chapter 17.
Generated state is not yet context
Writing PLAN.md creates agent-generated state if the file is successfully written and remains available to the runtime. It becomes self-generated context only if its contents are admitted and rendered in a later invocation. Persistence does not ensure that an indexer discovers the file, a candidate builder selects it, or an assembler includes it. This preserves Chapter 1’s ontology: a stored artifact can be available without being model-visible, and persisted ≠ readmitted.
The chapter covers observable, persistable state: plans, task lists, progress records, summaries, hypotheses, critiques, reflections, subagent reports, decision records and intermediate files. It does not cover hidden reasoning traces, unavailable activations or provider-private state:
private reasoning ≠ application state
Context engineering governs what the application can observe, and visible reflection text is not a faithful transcript of hidden reasoning. Nothing in the experiments seeds, reads or measures it.
Inspect this in the Context Viewer
The viewer scene for this chapter traces one seeded guess across a context reset: a tool FAIL observation, an unverified root-cause note, and the same claim readmitted later without status or evidence lineage. Open the scene and check what survives each transition. What to examine: the claim persists while its status and originating observation do not — and that distinction is exactly what the later computation can no longer see. A mechanism demonstration, not a prevalence claim.
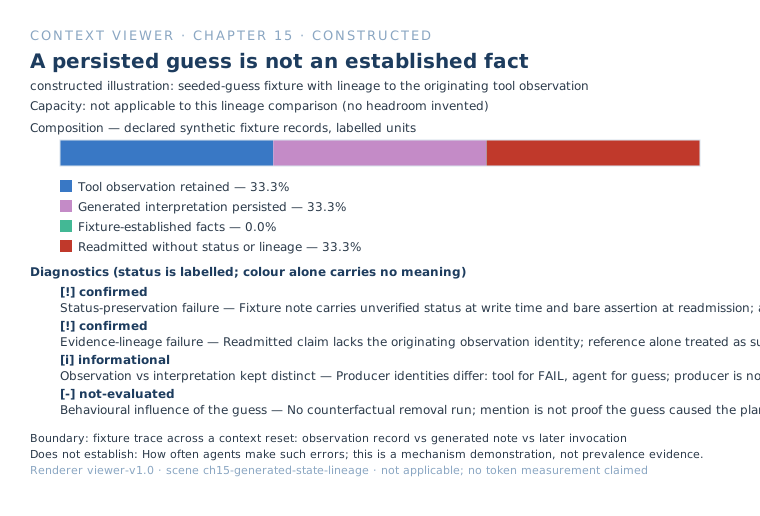
Open the lineage scene in the Context Viewer
Observation, interpretation and established fact
Three things are easy to blur. An observation is a record of what an environment, tool or source reported in a specific interaction, such as FAIL: expected 4, got 5. It is evidence about the world and is not necessarily true. An interpretation or hypothesis is a proposition the agent inferred, such as “cache invalidation may be broken”. In experiments only, a fact can be established for the fixture, meaning backed by a frozen fixture rule or oracle. The chapter defines no universal production truth criterion.
observation ≠ interpretation ≠ established fact
Where an item came from does not settle whether it is true, so producer ≠ truth status: an environment-produced item can be erroneous, stale or malformed, and an agent-written statement can be right. Several related distinctions follow:
observation ≠ truth
persistence ≠ confirmation
confidence ≠ epistemic status
self-declared confirmation ≠ verified confirmation
decision ≠ belief
A hypothesis does not become more established by surviving five turns. A status of unverified hypothesis with confidence 0.9 is still an unverified hypothesis. A decision to run a cache-isolation test does not assert the hypothesis that prompted it, and acting on a hypothesis does not confirm it. Where confirmation matters in an experiment, the criterion must be frozen independently of the state writer. A tool observation may satisfy that criterion only when the fixture specifies what the tool result establishes; the fact that a tool returned text is not confirmation by itself.
Goal, plan and current step have different lifetimes and invalidation conditions. The goal may persist while the plan changes and the step completes, so a completed step should not stay active because its goal does.
Epistemic inheritance
A later computation can receive a statement without seeing why it was written, what supported it, how uncertain it was or what contradicted it. Persisted generated state therefore needs epistemic inheritance: the claim, its status, the identity and availability of its supporting evidence, and relevant contradictions must remain linked when the claim is transformed or readmitted. This does not require every evidence payload to remain resident, but a reference alone cannot be treated as recovered evidence. The preservation requirement is that a later computation cannot justifiably read the persisted claim more strongly than its evidence warrants. Three things can survive separately:
claim survival ≠ status survival ≠ evidence-lineage survival
Chapter 11’s epistemic collapse changes suspected into established under transformation. The route here is different: a hypothesis is persisted, reused without its status and lineage, and read as fact. The observable failure is the same, epistemic strengthening without evidence, and the mechanism is different. An evidence reference present is not evidence recovered (Chapter 13), and evidence recovered is not the claim confirmed, since it may contradict the claim. Status is not a scalar confidence. A minimal state uses only the categorical statuses a fixture needs, and a field called status does not guarantee correct status: state schema ≠ state semantics.
How persistence exposes future computations to error
Persistence makes an earlier error available for possible later exposure; neither readmission nor influence follows automatically. A later computation may ignore, challenge, correct, invalidate or reinforce the item. Exposure can be counted as the number of invocations to which the item was actually admitted, while influence requires a separate behavioural comparison. High exposure creates more opportunities for propagation, but does not establish a proportional increase in impact. Readmission frequency is not importance, and repeated admission does not upgrade a hypothesis into evidence.
Two feedback paths can contribute to a self-reinforcing loop. Selection feedback occurs when the hypothesis changes which actions or queries the agent chooses, changing the evidence it encounters. Interpretation feedback occurs when the same admitted evidence leads to different conclusions because the hypothesis is present. These effects require different comparisons: hold the evidence fixed to study interpretation, and allow action choices to vary while recording the resulting observations to study selection. Neither can be inferred simply because a hypothesis appeared in a later trace. Chapter 14 owns whether an item returns; write-then-permanently-pin is the accidental policy to avoid.
Lifecycle, invalidation and audit
Working state needs an explicit way to prevent superseded claims from guiding continuation once valid contradictory or closing evidence is recorded. The operations are conceptual: create, update, invalidate, supersede and close. They require a defined transition rule and a record of which prior item each transition affects. Appending “H is false” beside “H is probably true” preserves a contradiction without identifying which claim is active; automatically invalidating the older claim solely because the newer sentence appeared would also be unsafe if that sentence were unsupported:
contradiction recorded ≠ prior state invalidated
Invalidation is not deletion. An invalidated item may remain in the audit history while becoming ineligible for ordinary active readmission under the declared lifecycle policy. The audit history records events and their provenance; the active view is a derived account of which items are currently applicable, not a statement of what the runtime has proved true. An invalidation itself can be mistaken and may need correction, so the transition and its evidence must remain inspectable:
mutable active state ≠ append-only audit history
State can be trajectory-obsolete, meaning it describes the past accurately and no longer the current work, as when the next step reads “run migration test” after the test finished. That is obsolete for coordination and not false historically. World-stale means the external fact changed, and Chapter 20 owns it.
Generated state carries no authority for being self-written or persisted, and Chapter 19 adjudicates precedence. A task-specific hypothesis is valid across time only within its scope, which Chapter 21 owns, and this chapter records scope metadata and nothing more. A subagent’s report can compress useful work or introduce error, and a cross-agent handoff is not verified evidence. Generated summaries inherit Chapter 11’s preservation obligations.
Two qualities
A computation can be judged by its immediate output and by the state it leaves for its successor. These evaluations need different reference points: the immediate answer is judged against the current task, while continuation state is checked against frozen obligations, evidence and lifecycle transitions and then tested in a later invocation:
current-output quality ≠ continuation-state quality
A run can give a good answer and leave bad state, or the reverse. Continuation-state quality is measured by the dimensions a fixture supports: required facts preserved, hypotheses still qualified, contradicted items invalidated, the current plan matching the current state, evidence references valid, no unsupported promotion, no completed step left current, and whether the next invocation can continue correctly. No single score is constructed.
What engineering already does
These are precedents for generated state persisting and being reused. Only the ReAct and Reflexion results are academic, and none of these establishes that persisted state is safe.
| Source | Evidence type | Verified pattern | Chapter uses | Does not establish |
|---|---|---|---|---|
| ReAct (Yao et al., ICLR 2023) | Peer-reviewed | Interleaves generated reasoning traces with actions and observations; reported gains include a 34 per cent absolute success gain on ALFWorld and 10 per cent on WebShop | The trajectory shape of prior generated state plus observations shaping later action | That visible traces equal hidden reasoning, or anything about persistence |
| Reflexion (Shinn et al., 2023) | Paper; authors’ benchmark results | Reflective text stored in an episodic memory buffer to improve subsequent trials; 91% pass@1 on HumanEval against 80% for GPT-4 | Generated text becoming future input by design | What happens when a persisted reflection is wrong; this chapter asks that separately |
| Anthropic, “Effective harnesses for long-running agents” (November 2025) | Vendor engineering report | Continuity through a pass/fail feature list, a progress file, an init script and git history, with each session starting from recorded state and ending by updating it | Deliberate durable working state across context windows | Causal effectiveness |
| Anthropic, “Harness design for long-running application development” (March 2026) | Vendor engineering report | A planner, generator and evaluator communicating through files; the author notes errors in a granular upfront spec cascade downstream; evaluator leniency toward its own model’s work needed tuning | Generated plans constrain downstream work; agent-written judgement is not neutral | Measured fidelity of file handoffs |
Multi-turn conversation degrades reliability
Laban et al. (2025) studied 15 models across six generation tasks using more than 200,000 simulated conversations. They found the authors’ average 39% relative degradation in multi-turn settings compared to fully specified single-turn tasks. The degradation decomposes into a minor aptitude loss and a significant increase in unreliability. Models often attempt solutions prematurely, make unsupported assumptions, and become anchored to their own earlier answers. The final information can be sufficient in both conditions; the difference is how the information arrived and which intermediate answers became part of the context.
The study also tested mitigation strategies: repeating and consolidating earlier requirements helped but did not fully recover single-turn performance, and lowering temperature did not eliminate the multi-turn reliability problem. This argues against treating summarisation or conversation resets as automatic solutions. A good context system must distinguish current requirements from the model’s previous attempts to satisfy those requirements. These findings motivate testing whether explicit claim status, evidence lineage and invalidation can reduce the influence of premature hypotheses. The study establishes the multi-turn reliability problem, not the effectiveness of those proposed remedies.
Structured and free-form state
Free-form narrative notes may preserve nuance with little schema overhead but can obscure status, provenance and lifecycle transitions. Structured records make such fields explicit and allow mechanical validation, but a field populated by the same model may still be wrong; structure cannot independently establish truth. Structure, boundedness and update semantics are separate variables: a structured append-only record may grow indefinitely, and a bounded free-form note can still be carefully corrected. An observed improvement cannot be credited to structure alone if the structured condition also changes the update policy.
Proposed experiments
Nothing here has been run. The two seeded experiments below ask separate questions, and the second shows what persistence does to an error and not how often agents make one:
mechanism demonstration ≠ prevalence evidence
Ecological gate. Before elaborate machinery, describe real traces: how much persistent agent-generated text there is, its readmission frequency and lifespan, plans repeated after completion, hypotheses reappearing, the presence of status and provenance, correction and invalidation events, repeated work after resets, cross-agent handoffs, and the share of state in the active tokens. The corpus of real sessions is empty.
Experiment A: continuation value. Does persisted observable generated state improve continuation across a context or session boundary? Fixtures are deterministic multi-stage tasks with a forced reset, mostly correct or neutral trajectories, and no seeded false hypothesis. The unit is the fixture, and stochastic repeats stay separate. Freeze the goal, environment, observable tool results, completion criteria, reset point, model, decoding and tools. Compare no persisted generated state; environment observations only, with task goal and instructions always available; the full observable trajectory (application-visible messages, actions, tool outputs and generated state, excluding hidden reasoning); free-form bounded state; structured bounded state with explicit update and invalidation semantics; and an oracle minimal state. Define precisely which observations remain accessible after reset in every condition so that a persistence effect is not confounded with loss of environment evidence. A targeted ablation compares append-only with replace-and-update within one representation, and a matched-budget arm supplements comparisons at natural sizes. Free-form versus structured alone cannot identify an effect of structure because the structured condition also exposes lifecycle fields. Report task success, repeated actions, rediscovery, steps to resume, admitted tokens, separate write/management/readmission costs, continuation-state quality, obsolete-state rate and unsupported promotion.
Experiment B: error propagation. When a false but plausible observable hypothesis is persisted, how do status, evidence lineage, readmission and invalidation affect its propagation and correction? Freeze the hypothesis text: the experiment studies propagation of an error, not its spontaneous creation. Freeze a timeline of ambiguous evidence, the hypothesis, a potentially influenced action, further ambiguous evidence, a decisive contradiction and continuation. The writer cannot see later evidence, and the evaluator holds the full fixture. Compare: not persisted; persisted unqualified; persisted with explicit unverified status and evidence reference; the same item subsequently invalidated by a rule tied to the decisive contradiction; the contradiction merely appended; and an oracle state. Hold the post-reset candidate pool and admission policy constant where possible, and record exactly when and whether the hypothesis, reference and contradiction enter each invocation. Otherwise an apparent status or invalidation benefit may simply be reduced exposure. Status-only, evidence-only and combined ablations are needed to attribute effects to those components; if they are unaffordable, label the comparison a test of the combined mechanism. Inject one broken evidence reference after reset to test the recovery dependency inherited from Chapter 13.
Metrics are reported separately: whether the hypothesis was written, persisted, offered as a candidate and actually admitted, and the number of subsequent invocations containing it; whether status, evidence identity and contradictory evidence survived, and whether the active record was promoted without newly admitted evidence satisfying the frozen criterion; which subsequent queries or actions changed under matched counterfactual conditions; and whether actions following the contradiction remained consistent with the false claim, using fixture labels because not every exploratory action based on a hypothesis is wrong. Define correction delay from the first invocation in which the decisive contradiction was available to the agent, not merely when it existed in the environment. Report active-state correction and behavioural correction separately. Mentioning the claim is not evidence that it caused an action; causal influence requires controlled removal, restoration or another explicit counterfactual.
Evaluation is deterministic wherever possible: status fields, evidence identifiers, invalidation, versions and completed steps. A model judge is used only for semantic equivalence and continuation quality, with a frozen rubric, blinded conditions and recorded disagreement, and never for what a fixture can decide.
A small lifecycle experiment comparing appended contradiction, replaced active item and invalidation with retained audit could be added if Experiment B cannot isolate it.
Outcomes that count. Persisted generated state fails to outperform no persisted state, observations alone match structured state, or free-form state matches structured state. Structured state improves correctness at higher generation and management cost. Explicit status does not reduce propagation. Evidence references help only when the evidence remains recoverable. Invalidation makes no difference because models already follow newer contradictions, or append-only correction performs as well. A false persisted item is usually corrected immediately, or real traces rarely persist hypotheses across resets. If no-persistent-state or observations-only conditions match generated state on continuation and cost, and a seeded false item is corrected equally fast regardless of status, lineage or invalidation, the experiments do not justify elaborate generated-state machinery for the tested workload. The distinction between agent-generated information and environment observation survives either way.
Persistence is not memory
Agent-generated state can survive the computation that produced it, and duration alone does not make it memory. It arrives as a candidate through the same door as every other source, carrying its producer, status, evidence references, version and what superseded it. Chapter 16 inherits these and asks when persisted past state stops being temporary coordination state and becomes durable memory, and what further obligations follow.
Behind all of this is one question. When a later computation receives a statement written by an earlier one, what prevents persistence itself from being mistaken for evidence? The answer is not a format. It is a preserved producer, status, evidence lineage and lifecycle, evaluated independently of the writer’s own labels.
persistent working state ≠ memory
References
- Yao, S., Zhao, J., Yu, D., et al. “ReAct: Synergizing Reasoning and Acting in Language Models.” ICLR 2023 (arXiv:2210.03629, camera-ready March 2023). https://arxiv.org/abs/2210.03629
- Shinn, N., Cassano, F., Berman, E., Gopinath, A., Narasimhan, K., Yao, S. “Reflexion: Language Agents with Verbal Reinforcement Learning.” arXiv:2303.11366. Authors’ reported results. https://arxiv.org/abs/2303.11366
- Young, J., et al. “Effective harnesses for long-running agents.” Anthropic engineering report, 26 November 2025. https://www.anthropic.com/engineering/effective-harnesses-for-long-running-agents
- Rajasekaran, P. “Harness design for long-running application development.” Anthropic engineering report, 24 March 2026. https://www.anthropic.com/engineering/harness-design-long-running-apps
- Laban, P., Hayashi, H., Zhou, Y., Neville, J. “LLMs Get Lost In Multi-Turn Conversation.” arXiv:2505.06120, May 2025. Preprint. https://arxiv.org/abs/2505.06120
Research
Not yet researched
This chapter has not yet been researched.