The Context Compiler
The smallest deterministic mechanism that enforces the constraints the book has earned: what it consumes, what it guarantees, where the implementation is contingent policy, and where the specification outruns it.
Here is the whole interface.
const output = compileContext(request, candidates, policy);

if (output.result.success) {
  const bundle = output.bundle;      // the ordered ContextBundle
  const trace = output.result.trace; // one entry per candidate: what was decided and why
} else {
  const reason = output.result.failure?.reason; // a named refusal, never a guess
}
A request, a list of candidates and a policy go in. On success, the call returns a bundle and a trace of the decisions represented by the implementation; on failure, it returns a named refusal and the available decision record. The call itself reads no files, invokes no model and consults no network, clock or randomness. That purity is a property of the compiler boundary, not of the surrounding pipeline: candidate builders and callers may have obtained facts from mutable sources or supplied stale judgements. Deterministic compilation therefore makes a supplied decision reproducible without establishing that the supplied information was correct.
Chapter 22 derived a specification: given eligible candidates, relationships, admissible representations, hard constraints and a budget, determine whether a valid bundle exists, select among feasible bundles under an explicit objective, and otherwise return a structured failure. The implemented compiler is narrower: it constructs and checks a bundle using deterministic policies but does not exhaustively search the feasible sets. A refusal may therefore report that its construction procedure could not satisfy the request, rather than prove that no legal bundle exists. This chapter treats the compiler as an experimental artefact and separates three things: structurally justified mechanisms, contingent policy choices, and specification requirements the code has not yet earned.
A compiler in this book is a deterministic transformation from declared candidate state, constraints and policy into a valid ordered bundle or an explicit failure. It is not retrieval, memory, candidate discovery, truth discovery, validation against the world, summarisation, behavioural evaluation or transport. It consumes decisions made elsewhere.
The task
The numbers here come from small synthetic cases shipped with the compiler. They demonstrate a mechanism and measure nothing. An agent is investigating a failing database migration. Upstream systems have produced a standing rule that generated files must never be edited, the task, an incident report in several forms, an observation of the backend taken at an earlier revision, a configuration file from a different project, a claim that the migration completed with a qualification that it did not for one tenant, and two documents that disagree about the database. The compiler decides what this one computation receives.
What it is given
The request carries a task identifier, a declared usable token budget (Chapter 4’s envelope, treated as a ceiling), the active scope, any specifically named candidate identifiers, the expected policy version and a caller-supplied creation time. The creation time is an input value, not a clock reading made by the compiler; supplying it does not validate the age or freshness of a candidate. Nor is the budget a provider-confirmed token count: its meaning depends on the caller’s accounting contract and the renderer’s estimator.
A candidate is one representation of one piece of information plus what the compiler needs to decide whether it may be used:
| Kind | Fields | Role |
|---|---|---|
| Identity | candidate identifier, content identity, representation identifier | Which information and which form |
| Constraint | scope, freshness and authority verdicts (each with a reason), a form rank and a floor, a requirement class | Hard eligibility and obligation |
| Relationship | dependencies, a group identifier and whether the group is required | What must accompany what |
| Cost | a declared token count | Declared, not measured |
| Objective signal | relevance, coverage keys | Choosing among feasible options |
| Placement | an order role | Ordering policy |
| Payload | source kind, kind, content, source reference | What is rendered and traced |
The policy is small: a minimum relevance for optional material that adds no coverage, a supported choice of “cheapest” among mandatory forms, the role order and a repair rule for render overrun. The implementation rejects some malformed inputs before selection, including duplicate identifiers, negative declared token counts, missing dependencies and certain cross-class groups. The caller must distinguish these input-contract violations from a well-formed compilation that returns failure. A third state matters for interpretation: a reported compilation failure is not necessarily a proof of mathematical infeasibility, because the selection procedure is not complete.
invalid request ≠ no legal bundle ≠ legal bundle
Eligibility is supplied
The compiler enforces supplied eligibility judgements. It does not discover scope, freshness or authority.
A gate can establish only that, given the supplied judgement and policy, a candidate is not eligible for this compilation. It cannot establish that the judgement describes the world. If a builder marks a stale observation fresh, the compiler admits it and records that it passed the gate.
Chapters 19 to 21 gave richer models than a boolean: permission to contribute data can differ from permission to instruct, operation-relative freshness can remain UNKNOWN, and scope can include several worlds. The compiler can consume binary verdicts without implementing those models only when upstream has projected each richer judgement for the specific operation being compiled. The described builder currently compares one scope string with another and consumes supplied validator status; those mechanisms cannot by themselves establish multi-world applicability or operation-relative freshness. A permissive UNKNOWN verdict means policy authorised proceeding without confirmed currentness, not that the evidence became current. The compiler enforces the projected verdict and its reason; correctness of the projection remains an upstream obligation.
Feasibility before preference
The main law is:
A compiler should never trade away a hard obligation to improve a soft objective. It should either construct a bundle satisfying the declared hard constraints or return an explicit failure, and only within the legal region may soft objectives influence selection.
feasibility ≠ preference constraint ≠ score
That law asks for a valid output, and it does not ask for a complete feasibility solver. Three properties are separate:
soundness:     a returned bundle satisfies the enforced constraints
completeness:  if some legal bundle exists, the compiler finds one
optimality:    among legal bundles, it chooses the best
Soundness here means relative soundness: an emitted bundle meets the hard constraints actually encoded and supplied to the compiler, in the units its validator checks. It does not imply that source claims are true, that upstream eligibility was correct, or that a provider will count the same number of tokens. Completeness is not established: greedy choices and repair may fail even if some other admissible selection would fit. Optimality is not claimed because neither exhaustive search nor a validated utility objective is present. The stages validate input and named candidates, apply gates, handle mandatory and required classes, select optional units, order, render and check the result. Tests of emitted-bundle validity, false refusal and policy quality must remain separate.
    flowchart TD
    IN["Request, candidates, policy"] --> V["Validate input and named sources"]
    V --> G["Hard gates from supplied verdicts<br/>scope, freshness, authority, floor"]
    G --> M["Mandatory, then required<br/>closure and groups priced whole"]
    M --> P["Optional units by policy,<br/>stopping below the ceiling"]
    P --> O["Order by role"]
    O --> X["Render, estimate cost in compiler units,<br/>verify against the envelope, repair"]
    X --> OK["Bundle and trace"]
    V -.-> F["Failure and trace"]
    M -.-> F
    X -.-> F
A high relevance score cannot repair a wrong-scope, invalid-temporal, unauthorised or below-floor candidate, because the gate has no score in it:
function hardGate(c: ContextCandidate): Gate {
  if (!c.scopeEligible)       return reject("scope_ineligible", c.scopeReason);
  if (!c.freshnessEligible)   return reject("freshness_ineligible", c.freshnessReason);
  if (!c.authorityEligible)   return reject("authority_ineligible", c.authorityReason);
  if (c.formRank < c.minRank) return reject("illegal_representation", "below floor");
  return eligible();
}
Two synthetic cases demonstrate enforcement. A configuration file from another project scores 0.99 for relevance and is rejected. A stale observation (100 tokens, relevance 0.9) sits beside a current one (600 tokens, relevance 0.75), and the stale one is rejected. These show the gate overriding cost and relevance. They do not show the upstream judgements were correct.
Obligations
The compiler has four requirement classes, and Chapter 22 derived a simpler distinction, hard obligation against soft preference. Reading the code shows what each class actually changes:
| Class | Handled | If it cannot be admitted | What differs |
|---|---|---|---|
| Mandatory | first, per content identity, in the form of least marginal cost | the compilation fails | Named failure reasons; first claim on budget |
| Required | second; groups before single items | the compilation fails | Same obligation; lower processing priority |
| Preferred | greedy, by relevance | skipped | Considered before discretionary |
| Discretionary | greedy, by relevance | skipped | The only class the render repair may drop |
Mandatory and required are both hard obligations in the described implementation, but they are processed in different orders and receive different diagnostics. That order can change a greedy result when alternatives and shared dependencies compete for budget. A reported failure of either class is thus an execution outcome, not necessarily a certificate that every possible valid bundle fails. Preferred and discretionary use similar relevance-based selection but differ in priority and in which items render repair may drop. The conceptual baseline is hard versus optional material plus an explicit drop priority; the four-class division is contingent until ablations show that its additional distinctions matter. A request-named candidate becomes required, and absence of that identifier from the candidate pool is handled separately as unavailable source.
Mandatory is required for this computation, and it is not importance:
retention policy  ≠  compilation requirement
mandatory  ≠  relevant        relevant  ≠  mandatory
A retention class says what may be done to an item when space is short (Chapter 7), and a requirement class says whether this compilation may proceed without it. A pinned rule is offered only in exact form, and it is mandatory only in a task that edits code. Upstream retention policy constrains which representations are offered, and the compiler enforces the resulting admissibility information. It does not map retention onto one universal numeric floor.
Representations: substitutes and complements
Chapter 12 and Chapter 18 established that content identity is not representation identity. The incident report exists in four forms:
| Form | Rank | Tokens | Needs |
|---|---|---|---|
| full text | 3 | 900 | nothing |
| compact summary | 2 | 300 | nothing |
| anchor | 1 | 90 | nothing |
| bare reference | 0 | 20 | a resolver definition of 150 tokens |
The rank is an upstream fixture convention, not a generally valid ordering of fidelity. The engine compares formRank with minRank, but Chapter 12’s preservation requirements are multidimensional: a structured form can retain an exact identifier better than a longer narrative. Consequently, numeric rank is a valid eligibility proxy only for fixtures whose builder has demonstrated that the rank threshold represents their declared obligations. Otherwise the compiler can enforce the number correctly and still accept an inadequate form. It selects among offered representations and creates none. A rule available only as paraphrase must be rejected if the verified requirement is exact wording, regardless of its nominal rank.
Here the code and the specification disagree. The compiler treats all candidates with one content identity as alternatives: once one is admitted, the others are rejected as alternatives, and a dependency whose content identity is already admitted counts as a collision. Chapter 18 allows complementary representations, such as a short structured summary beside an exact quoted clause, or an anchor beside selected exact evidence, and Chapter 22 keeps hybrids possible. So:
same content identity  ≠  mutual exclusion
substitute  ≠  complementary
Mutual exclusion should be declared for substitute sets, rather than inferred merely from shared content identity. As an architectural deduction, a structured record and an exact quoted clause may be complementary even when both derive from one source object. The chapter’s code inspection indicates that the current one-form-per-content rule would exclude the second; this is not yet a measured behavioural failure, because the synthetic corpus lacks a complementary-pair fixture. A bounded repair candidate is a declared substitute-group identifier alongside explicit compatibility for complementary forms. An experiment should first establish that the rule changes structural validity or downstream outcomes before adding new compiler machinery.
Dependencies, coupling and cost
A reference to the earlier incident costs twenty tokens to write. Following it needs the tool that resolves it, 650 tokens:
    flowchart LR
    R1["Reference to incident<br/>20 tokens"] --> T["Resolver definition<br/>650 tokens"]
    R2["Second reference<br/>25 tokens"] --> T
Cost has several units and the compiler keeps them apart:
declared item cost  ≠  incremental selection cost  ≠  dependency-closure cost
declared cost  ≠  rendered estimate  ≠  provider-accounted cost
The compiler computes a dependency closure from the relationships it was supplied and charges for members not yet selected. With a 20-token reference and a 650-token resolver, the first reference costs 670 tokens. With two references of 20 and 25 tokens and a 300-token shared resolver, their combined closure costs 345 tokens; those are separate illustrative resolver costs, not two prices for the same fixture. Ineligible dependencies block admission of their parent, with different outcomes for optional and required parents. Traversal that visits each node once prevents infinite recursion over cycles, but does not prove that cyclic relationships are semantically admissible for a particular task. Missing pool dependencies are rejected as malformed inputs. Closure is exact only relative to declared relationships: it cannot discover an omitted interpretive, tool or provenance dependency.
dependency closure ≠ semantic completeness
Dependency and coupling are different. A dependency is directional, A requires B, and it does not imply B requires A. A coupled group is all-or-none. The required-group mechanism implements coupling. The claim that the migration completed (120 tokens) and its qualification “except one tenant” (80) form a group, and a group that cannot fit fails with a named reason. A required group must sit in one requirement class, which the code enforces on input. That looks like an implementation simplification, since admission proceeds class by class, and not a semantic requirement.
Preserving disagreement uses the same mechanism only when upstream policy says to preserve together (Chapter 19), so semantic conflict ≠ automatic coupling. Then two claims and a marker (60, 60 and 40 tokens) enter together or not at all.
A fixture is described in which a 400-token full incident representation could satisfy the same need as a reference costing 670 tokens after dependency closure, yet the reference was selected under a relevance-first discretionary policy. If both are truly admissible substitutes under the same obligations, this is an example of a higher-cost legal selection, not a hard-constraint violation. It does not establish that relevance-first is always wasteful: provider caching, later reuse, task behaviour and any cost of keeping full text may change the total trajectory economics. The example exposes a policy choice to test, rather than an observed efficiency result.
Choosing, stopping and refusing
Among feasible optional material the compiler admits, each round, the unit with the highest relevance, then the most new coverage, then the lowest cost, then the identifier. A unit that adds nothing is skipped, meaning relevance below the policy threshold and no new coverage key, with the threshold at 0.3 in the corpus. That ordering is a deterministic baseline, and nothing shows it is earned. In a synthetic case with a budget of 3,000 tokens the compiler produced a bundle of 265. One useful 150-token note went in, and two long notes about subjects the task did not touch were not selected under this policy, with 2,700 tokens unspent:
budget ceiling ≠ spending target unused budget ≠ failure
The architectural requirement is that the assembler may stop below the ceiling. The particular relevance-and-coverage rule is a policy and a hypothesis.
Failures are named. A failure carries the reason, the blocking identifiers, budget used and total, a diagnostic sentence and the trace, and no bundle:
| Reason | When | Recovery |
|---|---|---|
INSUFFICIENT_BUDGET |
mandatory or required material cannot fit, or the rendered bundle overruns with no legal repair | raise the budget or shrink the request |
UNSATISFIED_DEPENDENCY |
a mandatory or required candidate needs something ineligible or colliding | repair candidate construction |
NO_LEGAL_REPRESENTATION |
every form of a mandatory item is below its floor | supply an admissible form |
UNRESOLVED_REQUIRED_GROUP |
a required group cannot be admitted whole, for a dependency or a budget reason | repair the group or the budget |
REQUIRED_SOURCE_UNAVAILABLE |
the request names a candidate not in the pool | obtain the source |
REQUIRED_INELIGIBLE |
a mandatory item has no eligible form | change the task scope or the judgement upstream |
The count is not fixed, and a new name matters only if it marks a different state, recovery or evidence. INSUFFICIENT_BUDGET covers selection overflow, render overflow and a failed post-compile check, and UNRESOLVED_REQUIRED_GROUP covers both a dependency and a budget cause. Whether render overflow deserves its own reason depends on whether callers need a different recovery path from ordinary budget infeasibility. No unknown-cost reason exists because cost is a number and cannot be unknown, and unknown cost is not free, so the implementation has a gap there.
The compiler may refuse, and it must not manufacture apparent feasibility by silently weakening the constraints it knows: dropping mandatory material, lowering an enforced floor, accepting an upstream-ineligible candidate, omitting a declared dependency, breaking a required group or truncating an exact representation. A refusal preserves that enforcement boundary. Because completeness is not established, the caller should interpret a failure as “no bundle found by this compiler under these inputs and policies” unless the failure carries an independently checked infeasibility certificate. Recovering from failure is an upstream decision, not a licence for the compiler to relax its rules.
Order, render, verify
Membership is not order. The compiler orders the selected candidates by role (instruction, task, state, evidence, support, tool), and within a role by identifier. Relevance plays no part, and the order is a policy default and not a finding. Chapter 6 showed the same items are not the same context, so ordering is not cosmetic, and the compiler does not establish that its order is behaviourally best.
Rendering adds a header, item labels and separators, and the compiler estimates their token cost rather than querying the provider tokenizer. In one synthetic case, declared item counts totalled 770 compiler units while the rendered estimate was 789; in another, a declared sum of 250 became 265, prompting repair by dropping a discretionary item and producing an estimated 111-unit bundle. These are values from the compiler’s own accounting, not provider-observed input tokens. The described repair drops eligible discretionary material under a dependency and group rule, but retained dependencies may leave unused cost. Repair must be rechecked for closure, mandatory obligations and coupled-group integrity after each deletion. A pass against estimated units establishes internal budget compliance only; provider-token compliance requires independent measurement or a conservative bound.
deterministic estimate  ≠  exact token count
fits the estimate  ≠  fits the provider's accounting
In the project’s calibration a word-based estimate ran well below a provider’s count, on one session with one model. The compiler also checks its own output (rendered cost against the budget, layout against the item order, every item against the selected set), which is an internal invariant check and not independent validation:
internal check ≠ independent validator ≠ cross-implementation parity
Determinism and the trace
Determinism is conditional on a fixed compiler implementation, normalised inputs and policy, including their candidate order and tie-breaking rules. The described result records the request, policy version and bundle hash, but not a compiler build or revision identity; a later replay under changed code may differ while each version remains deterministic. A bundle hash also identifies only what was hashed under a declared canonicalisation, not necessarily the exact provider-visible message sequence. Reproducible compilation, semantic correctness, rendered-byte identity and provider-delivery identity require separate checks.
deterministic ≠ correct reproducible ≠ valid
The trace is a mechanical decision record, not model reasoning, a statement about source truth or a causal explanation of later behaviour. Its stated fields include per-candidate decisions, reason codes and details, requirement class, relevance, marginal cost, dependency closure, admitting parent, budget changes and position. Whether all fields are present for every failure path is a testable trace-coverage requirement, not something the field list establishes. An independent checker needs frozen inputs, compiler and policy versions, an unambiguous cost convention and complete enough records to reconstruct or validate the declared constraints. Trace completeness and compiler correctness are separately testable.
The name earns only constraint-enforced artefact construction. The compiler translates no program, proves no semantic equivalence and optimises nothing.
What is tested, and what is not
| Requirement | Implemented | Test evidence | Gap |
|---|---|---|---|
| Input validation | Yes, thrown before decisions | Core tests | Unknown cost not representable |
| Hard gates from supplied verdicts | Yes | Wrong-scope and stale-cheap cases | Verdicts are supplied |
| Requirement classes | Yes, four | Overflow and unavailable cases | Optional split changes only order and repair |
| Substitute alternatives | Yes, by content identity | Alternatives case | Identity, not declared relationship |
| Complementary representations | No | None | Would be rejected as alternatives |
| Representation floor | Yes, numeric rank | No-legal-representation case | Rank is a convention |
| Dependency closure, marginal cost | Yes | Dependency-trap and shared-dependency cases | — |
| Cycles | Yes, walked once | Dependency-cycle case | — |
| Coupling | Yes, required groups | Qualification and conflict cases | One class per group |
| Stopping below the ceiling | Yes, relevance and coverage | Budget-slack case | The threshold is policy |
| Refusal taxonomy | Yes, six reasons | Overflow, floor, unavailable cases | Render overflow shares a reason |
| Rendered-cost repair | Yes | Rendered-overflow case | Estimated units |
| Ordering | Yes, by role and identifier | Layout checks | Policy default |
| Trace and replay | Yes | Golden outputs | No compiler version recorded |
The corpus has 14 case families run at three budgets, which is 42 compilations. The corpus has no complementary-representation, unknown-cost or multi-world case, and no case tempts a weaker assembler to break an authority rule.
Ecological gate
The corpus of real sessions is empty. Before building more machinery, real pools would need to show:
- Structure: representations per content identity, substitute and complementary sets, dependencies, shared dependencies, cycles, coupled groups and preserved conflicts.
- Eligibility: rejections by scope, freshness, authority and floor, UNKNOWN upstream judgements and multi-world tasks.
- Cost and outcome: estimated against rendered and provider-accounted cost, unused budget, failures by reason, render overflows, runtime and trace size.
The compiler can support a mechanism before the book knows how often that mechanism matters in real sessions.
Proposed experiments
Experiment A: structural conformance, model-free. Freeze the fixture inputs, hard constraints, permitted representation combinations and the truth of whether any valid bundle exists before invoking the implementation. For small pools, use an independently implemented exhaustive enumerator or equivalent reference checker to distinguish a genuine infeasible instance from a greedy false refusal; do not use the compiler’s own failure as the oracle. Accept multiple valid bundles instead of requiring a unique selection, and check exact rendered constraints in the compiler’s declared units. Retain the existing fixture coverage and add complementary representations, optional and required parents with ineligible dependencies, unknown cost, multi-world verdict projection, and competing mandatory alternatives with shared dependencies. Record separately invalid emitted bundles, false refusals, failure-code accuracy, incomplete traces and disagreements with independent cost checks.
- complementary representations that policy permits together, which the current compiler may fail;
- an optional and a required parent with an illegal dependency, separately;
- unknown cost;
- a multi-world eligibility projection enforced without the compiler understanding worlds;
- false infeasibility from shared dependencies under greedy admission.
Experiment B and ablations. Chapter 24 compares selection strategies; this experiment asks which compiler mechanisms are needed for the declared invariants. Remove one mechanism at a time—hard gates, dependency closure, coupling, substitution handling, representation admissibility, explicit refusal, rendered-cost checking, stopping and stable tie-breaking—while holding fixtures and policies fixed. An ablation may make output invalid, merely change selection, or leave everything unchanged; report those separately. A mechanism is not justified solely because removing it breaks an adversarial fixture constructed specifically for it. The ecological gate and any downstream evaluation determine whether the failure mode is important enough to merit production complexity. No single composite quality score is proposed.
What compilation does not establish
legal bundle  ≠  useful bundle
structurally valid  ≠  behaviourally effective
compiler selected it  ≠  the model used it
bundle emitted  ≠  bundle delivered
Chapter 26 owns behavioural evidence and Chapter 25 owns transport. Structurally legal bundles can hold distractors, and a successful compile says neither that the bundle reached the model nor that it helped. The boundary also stays where it was: the compiler does not derive scope, freshness or authority, does not build forms of a candidate, and does not count tokens exactly.
The evidence has an asymmetry. Hard gates, dependency closure, coupling, refusal, determinism and the trace are the mechanisms with the clearest structural rationale and existing fixture coverage, and Chapter 24 asks what the executed evidence supports. Four requirement classes, numeric form rank, relevance-first ordering, the 0.3 threshold, one-content-one-form, role ordering and drop-the-last-discretionary repair carry more contingent policy. The compiler is more mature as a constraint-enforcement artefact than the evidence justifies as a selection policy.
Inspect this in the Context Viewer
The viewer scene for this chapter shows a small candidate set from this chapter’s vocabulary going through the pipeline: hard gates first, dependency closure, the claim travelling with its qualification, and a legal bundle rendered at 3,400 of 4,000 with the slack left validly unfilled. Open the scene and read each rejection’s reason code, then the comparison with rank-fill on the same candidates. What to examine: why the wrong-world item is rejected here and would win under ranking, and what the trace records about the group and the slack. This is a constructed demonstration of the decision record, not a conformance run; it shows legality, and legality is not usefulness.
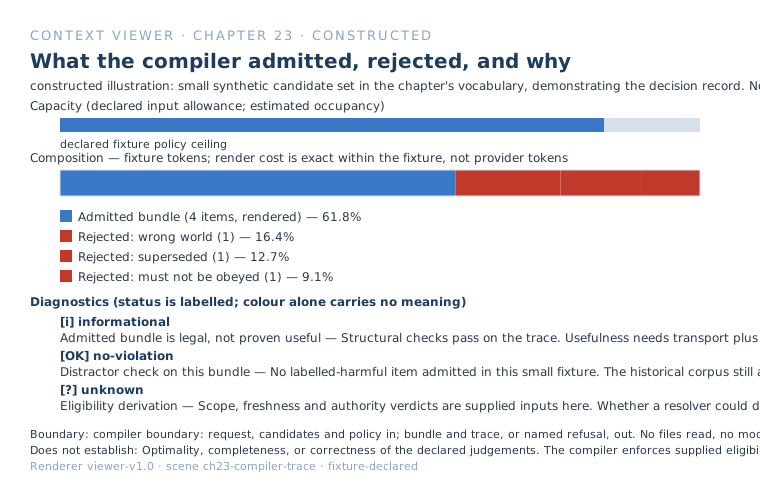
Open the compiler trace in the Context Viewer
The handoff
We now have a machine that can be given explicit constraints and candidate metadata and deterministically return a bundle or refuse. But implementation is not evidence. The compiler says it respected its gates, closed dependencies, stayed within its accounting units and recorded every decision. The next question is what observations would justify believing those claims, and how far they can reach: what evidence establishes soundness, what would establish completeness, and what, if anything, could support an optimality claim.
References
- Project Context Compiler. Source repository, Apache-2.0, first-party code by this book’s author. The library, command-line tool, agent tools and synthetic conformance cases used in this chapter. https://github.com/ernanhughes/project-context-compiler
Research
Not yet researched
This chapter has not yet been researched.