Make the Window Bigger
Ask whether a more capable long-context model eliminates, reduces or merely moves the context-management problem, by separating what model-side mechanisms change from what only the runtime can decide.
Seven chapters have treated the model as fixed ground and asked how the surrounding system should manage information against it. The natural objection has been waiting since Chapter 4: if context is scarce and hard to manage, why not make the window much larger?
Imagine a team that moves its agent onto a million-token model. The scenario is illustrative. Histories that once needed pruning now fit. Files that once needed triage could all be included. The compaction schedule gets quieter. For a while, context engineering looks like a stopgap awaiting cheaper capacity.
Take that response seriously, because it is partly right. A larger provider window can accommodate inputs that previously violated a hard limit, and a runtime may choose to raise its own admission ceiling in response. Those are separate changes: moving to a larger model does not automatically change the harness policy that decides how much to admit. Cheaper processing can also relax the cost constraint. But fitting is not helping, and Chapters 4 and 5 already separated the two. The objection also runs together four different things:
configured or advertised capacity
        ≠
computational efficiency
        ≠
trained competence
        ≠
effective behavioural use
Each takes real engineering to achieve, and achieving one does not achieve the others. This chapter looks at what the model side can change, and it returns with a boundary the rest of the book depends on: larger window ≠ solved context problem.
A model-side axis
Chapter 1 described a context bundle along four dimensions, all describing the bundle and the runtime that assembles it. Chapter 8 adds something of a different kind: not a fifth dimension of the bundle but the other side of the interface.
RUNTIME                    MODEL SIDE
decides what               determines how that representation
representation to present  is processed

  selection                 examples of model-side mechanisms:
  ordering                  attention variants
  retention                 recurrent or bounded state
  externalisation           state compression
  retrieval                 positional machinery

                 BEHAVIOUR
        depends on both sides
The right-hand column lists possible mechanisms, not a universal pipeline. Recurrence exists in some architectures and not others, attention may be dense, sparse, linear or hybrid, and the representation of history differs across designs. Behaviour depends on both sides, which is why neither can declare victory over the other. A cheaper model side relaxes the runtime’s constraints without removing its decisions.
Why long context is costly
Start from the cost structure that makes a bigger window hard. In conventional dense causal self-attention, processing a full sequence involves interactions between query positions and preceding key positions, giving roughly quadratic attention-interaction work as sequence length grows. This describes the attention component of prefill, not an empirical scaling law for the whole service. Feed-forward computation, mixture-of-experts routing, attention kernels, memory bandwidth, batching and hardware can make total compute, latency and price scale differently. Grouped-query attention primarily reduces key-value head count and cache cost; tiling primarily changes memory traffic, so neither should be presented as removing the quadratic count of dense attention interactions. Long-context architectures target different parts of this cost structure.
Memory is a second currency. In conventional cached autoregressive attention, generating each new token without recomputing the past means keeping the key and value states of the tokens already seen, the KV cache. At very long sequences that state can become a major inference-memory constraint, though how much depends on the architecture, model, hardware and batch. Not every architecture keeps a conventional per-token cache, as later sections show.
Long context can therefore impose different costs when processing the prompt and when generating tokens, so a mechanism that improves one does not necessarily improve the other equally. That is all this chapter needs of inference engineering.
Four ways of moving the cost
Long-context capability can be enabled or made more economical by several mechanisms. The following four are useful distinctions, but they are not sufficient individually to establish a particular advertised window or its effective behavioural reach:
- Extending positional range lets the model represent positions beyond those it was trained on.
- Reducing state cost stores the history of a long sequence in less memory.
- Reducing interaction cost spends expensive computation on a fraction of what full attention would touch.
- Changing how history is represented replaces an ever-growing token history with a bounded or recurrent state.
They overlap. A mechanism can reduce state and interaction cost together, and recurrent state is best seen as a different architecture family that changes both, not as a strictly separate fourth lever. The decomposition outlives any vendor, so providers appear only as worked examples, dated to September 2026.
| Mechanism | Directly changes | Example | Constraint it introduces | Behavioural question |
|---|---|---|---|---|
| Positional extension | Representable position range | Qwen3 with YaRN | An altered positional mapping | Does quality hold at extended positions? |
| State compression | State footprint and representation | DeepSeek V4 | A compressed representation of history | Which distinctions survive? |
| Sparse interaction | Number of expensive interactions | DeepSeek V4 | Not all positions receive equal computation | What relevant information is missed? |
| Bounded or recurrent state | How history is represented and how state scales | Kimi Linear, Kimi K3 | A bounded state summarising history | Which historical detail remains usable? |
The columns separate a mechanism fact from its behavioural consequence, and that separation is an invariant of the chapter: what a mechanism computes does not tell us what a model does with it.
Positions are not capacity
Many contemporary open-weight transformer families use rotary position embeddings, the construction of Su et al., which encodes absolute position with a rotation matrix while incorporating relative position dependency in attention. A model trained at one length and used far beyond it meets positions it did not learn, and quality can suffer for reasons unrelated to attention cost. YaRN (Peng et al.) is one influential extension method built on rotary embeddings. Its authors report needing about ten times fewer tokens and 2.5 times fewer training steps than previous methods, and report extrapolation beyond the fine-tuning length.
Qwen’s documentation separates figures that many pages blur. For Qwen3-8B, the model card states a native context of 32,768 tokens and describes extension to 131,072 with YaRN, using a scaling factor of four. It warns that some inference frameworks implement static YaRN, applying the same factor at every length, which can affect shorter inputs. For the 2507 generation, Qwen’s serving documentation shows a context-length flag set to 262,144 and advises choosing the value in light of available GPU memory. That flag describes a serving configuration for the model being deployed; it does not by itself establish a trained range, validated accuracy at the limit, or a universal property of Qwen weights.
So four things are different:
training regime
    ≠
configured maximum
    ≠
extrapolated context
    ≠
effective usable context
The training regime is what the model was exposed to in training, which may be a distribution of lengths and not one number. The configured maximum is what the serving setting permits. Extrapolated context is what positional scaling reaches. Effective usable context is what Chapter 5’s evidence ladder demands, and it depends on task, position, distractors and evaluation. Extending positional range does not by itself reduce state or interaction cost, and does not establish effective use.
Compress and select
State compression asks what it costs to represent prior tokens, and sparse attention asks how much expensive interaction each query needs. DeepSeek’s V4 technical report (submitted April 2026) describes both in an interleaved hybrid, alongside released model artefacts and inference code. Its Compressed Sparse Attention compresses blocks into representations used by a learned indexer to select candidates for more expensive attention. Heavily Compressed Attention uses a higher compression rate. Both include an uncompressed local sliding-window branch, which the authors associate with modelling local dependencies. For the larger V4 variant, the authors report single-token inference FLOPs at 27 per cent and KV-cache usage at 10 per cent of their V3.2 comparison at a million tokens. These are vendor-reported measurements under that comparison, not independent measurements or evidence that any particular distant fact remains usable.
Two observations follow. Compression changes the representation through which later computation can access history, creating a fidelity question that has to be evaluated rather than assumed away. A representation smaller than the original necessarily loses the ability to distinguish some possible inputs unless other information is retained elsewhere; that does not mean it loses the distinctions a particular task needs. The appropriate behavioural question is whether required information remains recoverable and usable under specified tasks, lengths and positions.
And sparse selection creates a second selection problem inside the model, distinct from the runtime’s admission problem. The runtime chooses what material to present; sparse attention chooses, or helps determine, which internal representations receive particular computation. A runtime that omits a critical instruction and a model that receives it but fails to use it may produce the same visible failure, yet the former can be established by inspecting the assembled bundle and the latter cannot be attributed to sparse routing without model-side evidence. Internal routing is not an observed step in Chapter 5’s ladder. A distant decisive block receiving too little effective interaction is a testable hypothesis, not a demonstrated failure of DeepSeek V4 or sparse attention generally.
The sliding-window branch also creates a structural asymmetry: recent tokens have a direct local path that does not depend on the sparse selection, and distant tokens do not. The report does not say this is a defence against the risk above, and nothing here infers the designers’ motive.
Remembering through bounded state
Kimi’s architecture changes how some layers represent history. In conventional token-cached attention, the KV cache grows with the sequence; Kimi Delta Attention, described in the Kimi Linear report and code, uses a recurrent or linear-attention-style state, extending Gated DeltaNet with finer-grained gating. The architecture combines these layers with Multi-Head Latent Attention. The Kimi Linear authors report up to 75 per cent less KV-cache usage and up to six times decoding throughput at a million tokens against their full-attention baseline, under the reported setup. Separately, the Kimi K3 repository describes a 93-layer hybrid with 69 Kimi Delta Attention layers and 24 gated latent-attention layers, 2.8 trillion total and 104 billion activated parameters, and a 1,048,576-token context limit. These are descriptions of distinct published artefacts; the Kimi Linear efficiency results must not be silently treated as measurements of the whole Kimi K3 deployment.
Two cautions apply. The state of an individual recurrent component need not grow linearly with the number of earlier tokens, but the Kimi K3 hybrid also has global-attention layers and serving overhead. A fixed-size component is not a fixed-memory full model. More fundamentally, a bounded state cannot retain arbitrarily fine-grained, independently recoverable detail about an unbounded input history. Whether it preserves the particular facts a task needs is empirical, and cannot be read from state size alone. The published architecture describes where computation and storage occur; it does not prove reliable recall of arbitrary distant detail.
Model-side compression is not retention policy
Chapter 7’s retention policy is explicit about requirements: fidelity floors, declared policy standing, task state and recovery obligations. Model-side compression is a learned transformation of internal representations. Both can change how much detail remains readily available, but only the runtime policy can expressly require that a named source, exact value or governing constraint be retained or made recoverable. Even an explicit runtime preservation decision cannot guarantee that a model will use the admitted item correctly; Chapter 5’s distinction between presence and use still applies. The two operate under different information and control:
runtime reduction
    explicit policy, observable item semantics

model-side compression
    learned representation, opaque to runtime policy
The chapter does not claim that a model implements a retention policy. A runtime’s keep-list cannot reach inside a model’s learned compression, and fine-grained distinctions must be preserved through the compressed representation if later computation is to recover them.
The same separation applies to locality. Some long-context architectures explicitly distinguish local or recent processing from distant-history processing, and the V4 sliding-window branch is one example. A locality mechanism allocates computation by position or learned representation, while runtime retention policy can use explicit semantic metadata the model-side mechanism does not have:
locality ≠ importance
A mechanism whose routing depended mainly on position could favour a recent trivial observation over an older governing constraint. That is a hypothetical, and different architectures handle instructions differently. It shows why positional locality policy is not semantic retention policy, and why neither has to correspond to freshness, which Chapter 20 owns.
Training decides what is learned
Architecture constrains which computations are available and their cost. Training shapes how the parameters learn to use those capabilities. Three things follow one another and should not be conflated:
architecture permits
    ≠
training exposes
    ≠
evaluation demonstrates
Architectural support for longer sequences does not by itself demonstrate learned competence at those lengths, and reliable retrieval, reasoning and positional use at length are behavioural claims that need the evaluation Chapters 5 and 26 describe. Extension methods make the point in another currency: reaching a longer position is not learning to use it, and Qwen’s caution about static scaling shows a cost arriving elsewhere.
The closed-model boundary
OpenAI and Anthropic expose very large windows through production models, and their interfaces, limits, caching semantics and compaction features are legitimate evidence in this book. Their attention architectures are a different matter. The first-party materials reviewed for this chapter do not give enough detail to classify their production models under the mechanisms above, so nothing is asserted about them. The model-side comparisons rest on architectures with public reports and implementations. Public capability does not license inference about undocumented internals, and a chapter that inferred them would trade evidentiary discipline for apparent completeness.
Inspect this in the Context Viewer
The viewer scene for this chapter compares a small and a large configuration on the same fixture: more material fits under the large one, while four policy questions — authority, staleness, redundancy, scope — persist unchanged beside it. Open the scene and separate what the machinery moves from what still needs runtime policy. What to examine: capacity and cost on one side, undecided governance on the other. Fitting is not admitting, and neither is helping.
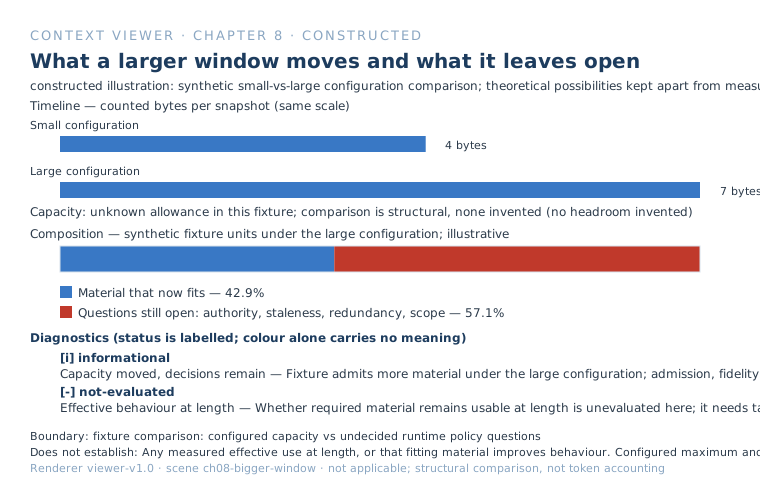
Open the capacity scene in the Context Viewer
What changes, and what does not
The chapter’s central question can now be answered in one matrix. Suppose architecture made a million tokens nearly free to process, with faithful retrieval and no degradation at any length. Which constraints would move, and which would not?
| Constraint or question | Can model change move it? | Does it remove the runtime decision? |
|---|---|---|
| Hard context capacity | Yes | No |
| Processing cost, latency | Yes | No |
| KV or state memory | Yes | No |
| Effective long-context behaviour | Depends, and has to be measured | No |
| Which information should be admitted | Changes the threshold | No |
| Which representation fidelity is required | Not by itself | No |
| Which duplicate is redundant | Not by itself | No |
| Which source is authoritative | Not the underlying fact | No |
| Which information is stale | Not the underlying fact | No |
| Which project or scope applies | Not the underlying fact | No |
| Which external information should return now | Not by itself | No |
Changing pressure is not the same as eliminating a decision. Architecture alone does not supply the external policy facts the last rows need: authority comes from deployment policy, freshness from timestamps and source state, scope from external membership, and the resolution of contradictions from provenance. A model can be trained to infer or predict some of these, and inference is not the same as the facts. The boundary in its strongest form is:
processing capability ≠ policy knowledge
The chapter refuses the opposite error with equal force. None of this makes long context or architecture irrelevant. The relationship is complementarity:
more efficient or capable long-context architecture
        ↓
changes the feasible region and the cost curve

better runtime context policy
        ↓
changes what information is presented

together
        ↓
a context system
One first-party case shows both levers in the same system. Kimi’s K3 repository reports a benchmark, BrowseComp, on which a context-compaction strategy triggered at 300K tokens scored 91.2, against 90.4 with the full million-token window and no management. That is one benchmark, two point estimates, vendor-reported, and the difference is small. It shows only that large model-side capacity and runtime context management can coexist in one evaluated system. The chapter’s thesis does not depend on it, and would survive if the practice changed tomorrow: architecture controls processing possibilities and cost, and runtime policy controls the information presented.
Two caches, not one
One confusion has to be cleared before the next chapter. Model inference state, the KV cache or an architecture’s recurrent state, persists across the decode steps of a request according to the serving implementation. The provider’s prefix cache is different: a serving-layer mechanism that may reuse computation across requests whose rendered prefixes match, with automatic or explicit controls, minimum lengths and lifetimes that vary by provider. The two share vocabulary and differ in ownership, granularity and control:
model inference state ≠ cross-request prefix cache
A runtime edit made to reduce admitted context can also shorten or invalidate reusable prefix matches under prefix-caching schemes, so optimising one ledger can damage the other. Chapter 9 owns the details.
What the book does not test
The chapter runs no new experiment, and the choice is deliberate. Its primary contribution is a conceptual decomposition and a boundary between external policy and internal processing. Its architecture descriptions draw on the cited technical reports, model cards and repositories; the reported efficiency figures remain claims under their authors’ evaluation conditions. The distinction between configured length and effective use is supported by Chapter 5’s external behavioural studies, not by an experiment on DeepSeek V4 or Kimi K3 conducted for this book. The assertion that model architecture cannot, by itself, determine external source authority and task-specific admission is an argument about missing policy inputs, not a measured prediction about model performance.
The waste that cheapness leaves behind
Suppose architecture succeeds completely. The runtime assembles Tuesday’s bundle: instructions, project rules, tool definitions, history, retrieved files, fresh observations and the current request. Wednesday’s invocation includes nearly all of it again, plus one new turn. If there is no cross-request reuse, processing may repeat work on a stable leading span. That does not mean every token is recomputed identically across all serving architectures, or that a particular provider bills the two calls the same way. Capacity determines what may fit; model efficiency changes the cost of processing it. Repeated cross-request work remains a separate systems question:
When can work already done on a reusable prefix be reused safely and economically?
References
- DeepSeek-AI. “DeepSeek-V4: Towards Highly Efficient Million-Token Context Intelligence.” Vendor technical report, arXiv:2606.19348, April 2026. CSA and HCA hybrid; lightning indexer with top-k selection; sliding-window branch; 27% of single-token inference FLOPs and 10% of KV cache versus V3.2 at 1M (vendor-reported). https://arxiv.org/abs/2606.19348
- Kimi Team. “Kimi Linear: An Expressive, Efficient Attention Architecture.” Vendor technical report, arXiv:2510.26692, October 2025. KDA extending Gated DeltaNet; hybrid with MLA; up to 75% less KV cache and up to 6× decoding throughput at 1M (vendor-reported). https://arxiv.org/abs/2510.26692
- MoonshotAI. “Kimi-K3.” Official repository, verified September 2026. 69 KDA and 24 gated MLA layers; 2.8T total and 104B active parameters; 1,048,576-token context; BrowseComp 91.2 with compaction at 300K versus 90.4 with the full 1M window (vendor-reported). https://github.com/MoonshotAI/Kimi-K3
- Qwen Team. “Qwen3-8B model card.” Hugging Face, verified September 2026. 32,768 native, 131,072 with YaRN; static-scaling caveat. https://huggingface.co/Qwen/Qwen3-8B
- Qwen Team. “Qwen3 documentation (Quickstart).” Verified September 2026. Context length as a serving flag (262,144 in the deployment examples). https://qwen.readthedocs.io/en/latest/getting_started/quickstart.html
- Peng, B., Quesnelle, J., Fan, H., Shippole, E. “YaRN: Efficient Context Window Extension of Large Language Models.” Preprint, arXiv:2309.00071. https://arxiv.org/abs/2309.00071
- Su, J., Lu, Y., Pan, S., Murtadha, A., Wen, B., Liu, Y. “RoFormer: Enhanced Transformer with Rotary Position Embedding.” Preprint, arXiv:2104.09864. https://arxiv.org/abs/2104.09864
Research
Not yet researched
This chapter has not yet been researched.