Compression Is Loss
Treat compaction as a change of representation whose losses must be measured against declared preservation obligations, separating selection failure from transformation failure and text quality from survival and utility.
An agent has accumulated a working past: an architecture decision at 500 tokens, an unresolved bug history at 4,000, three failed approaches at 8,000, tool observations at 20,000, and the current implementation at 6,000. The figures are illustrative. Chapter 10 does its work: duplicates go, checked-superseded observations go, and failed-input bulk goes with its required diagnostic residue preserved. Roughly 13,000 tokens leave and about 25,000 remain. Under the example’s declared obligations, no further item is eligible for outright removal. Yet the remaining context is larger than the budget the runtime has allocated for the session ahead. The next choice is not necessarily between keeping every byte and deleting essential information. Some of what remains may be represented differently, provided its preservation obligations survive. That is where this chapter begins.
The way forward is to change representation: replace a larger representation with a smaller one intended to preserve what future computations need.
Compaction replaces a larger representation of prior context with a smaller representation intended to preserve specified information.
The important word is intended, and the gap between intended and demonstrated preservation is the whole subject:
intended preservation ≠ demonstrated preservation
This chapter uses compression and compaction for a reduction in the size of the active representation intended to carry forward specified information. The replacement may be extractive, abstractive, structured, deterministic or model-generated. What matters is not whether a model wrote it, but whether the operation creates or selects a smaller representation intended to stand in for information removed from the active bundle. This crosses Chapter 10’s operational boundary deliberately: pruning removes without a semantic substitute; compaction attempts to preserve selected meaning in a substitute. Deleting an exact duplicate paragraph while another copy remains is pruning. Selecting sentences to stand in for an otherwise removed passage is compaction, even when every selected sentence is copied verbatim.
Three things are easy to confuse:
representation reduction   the output is smaller
information loss           information represented by the source is no longer recoverable
                            from the compact representation at the required fidelity
task-relevant loss          the lost information violates a declared preservation obligation
                            or is required by a downstream task
A changed representation is not necessarily lost information: a version stated in prose and then stored as a typed field has changed form and kept its content. So:
representation changed ⇏ information lost ⇏ required information lost
A smaller representation omits some of the source’s surface detail, but that does not establish that it loses a required fact, relation or constraint. A canonical structured encoding can even reduce redundant wording while preserving all declared fields exactly. Whether the replacement loses information needed later must be checked against explicit obligations and downstream tasks. The chapter makes no information-theoretic claim about whether arbitrary source content is recoverable from an encoding.
Three measurements
A summary can be fluent, coherent and plausible while missing the constraint the next twenty turns depend on. What was dropped is absent and not wrong, and absence has no stylistic signature. So three different claims need three different measurements:
text quality ≠ information survival ≠ behavioural utility
Text quality is a property of the produced text under a stated rubric. Survival is a relation between the frozen source, the compact output and declared preservation obligations, checked obligation by obligation. Utility is a comparative behavioural result on a downstream task under specified model and evaluation conditions. A successful task run cannot establish that every obligation survived: success may not have depended on what was lost. Conversely, an obligation can survive representation change yet remain unlocated or unused. These measurements must retain separate denominators and evidence statuses.
Compression ratio is a budget measurement and not a fidelity measurement:
compression ratio ≠ fidelity
A tenfold reduction may preserve everything required or lose one decisive identifier. Survival also does not entail Chapter 5’s later statuses: a survivor can be harder to locate, easier to use, or cause interference. And transformation changes length, position and adjacency (Chapter 6), so a behavioural change after compaction cannot be attributed to information loss alone. A shorter representation could improve behaviour through layout while losing information. That is why survival is measured before behaviour.
Loss and recoverability
Loss from active context is not necessarily loss from the system. A separately retained, version-identified source can support verification or regeneration of the compact form, but a pointer alone does not establish that the source can still be read. Conversely, if the compact form is the only surviving record, a lost obligation may be unrecoverable. The experiment therefore freezes and retains the original source and its identity independently of the candidate compactions. A recovery claim requires an actual retrieval and fidelity check; an audit entry is not a substitute for either. This chapter specifies that test but builds no storage system.
Preservation is obligation-relative
Some content cannot survive paraphrase. Take “Use PostgreSQL 18.2”, “Migration ID is 01947” and “Never modify production migrations without explicit approval”. A prose summariser can produce “18”, “1947” and “generally avoid”. These are tiny linguistic changes and large changes in what is represented: a wrong version, a wrong identifier, a prohibition softened into advice.
The requirement is not that such content bypass transformation. It is that the transformed representation meet a declared fidelity floor. A typed field {"database": "PostgreSQL", "version": "18.2"} can preserve an exact version, provided the field is not later coerced; typing the migration identifier as a string preserves its leading zero only if the value is copied exactly; and a structured constraint can preserve a prohibition only if its condition, scope and force survive. A schema is a way to express the obligation, not proof that the transformation satisfied it. Thus literal prose need not survive when the required semantics and exact fields demonstrably do:
protected from transformation below its floor
        ≠
must be copied as original prose
A PIN-governed preservation obligation (Chapter 7) forbids reducing an admitted item below its applicable floor; it does not automatically require the original prose. Compression also does not grant, revoke or change an instruction’s policy standing: Chapter 19 derives that from trusted provenance and policy. What the transformation can lose is the expression of the constraint. Turning “never” into “generally avoid” changes prohibition into advice even when the topic survives. In the experiments, both the obligation and the trusted source identity must be frozen before evaluation; a compacted assertion cannot authenticate its own authority. The obligations tested here are:
| Obligation | What must survive | Evaluator | Failure example |
|---|---|---|---|
| Exact field | A typed value | Typed equality | 18.2 becomes 18 |
| Identifier | A string, byte for byte | Text comparison | 01947 becomes 1947 |
| Constraint force | A prohibition stays a prohibition, with its qualifier | Frozen assertion or rubric | “Never” becomes “generally avoid” |
| Rationale | The decision and its reason | Frozen rubric | Decision kept, reason lost |
| Status | Hypothesis, open or closed, chosen or rejected | Categorical equality | Suspected becomes established |
| Provenance | Who or what the claim came from | Source identity relation | A user instruction becomes an unattributed claim |
| Relation | How items relate | Frozen relational assertion | “A was rejected because B violated C” becomes “A, B and C were considered” |
Inspect this in the Context Viewer
The viewer scene for this chapter works the prohibition example above as a declared contract: four obligations (exact version 18.2, exact identifier 01947, prohibition force, tenant qualification) against a compact summary that keeps the headline and fails three of the four. Open the scene and read the obligation-by-obligation diff before looking at the compression ratio. What to examine: which obligations survive, which are mutated, which are missing, and whether the full text remains recoverable through a validated pointer. This is a constructed illustration of the failure shape, not a measurement of any production summariser; fluency is visible and fidelity is judged only against the declared contract.
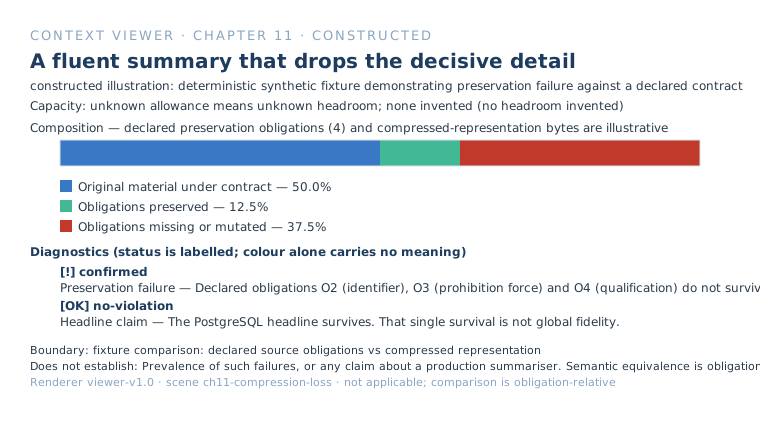
Open the compression-loss scene in the Context Viewer
Status and relations
The subtlest failure is not omission. The source says the serializer is suspected of corrupting timestamps, and the summary says the serializer corrupts timestamps. The topic survives and the epistemic status does not, and downstream behaviour now acts on a fact nobody established:
proposition survival ≠ status survival
The chapter measures only the statuses its fixtures use: hypothesis, established, open, closed, chosen and rejected. It builds no general epistemology.
Relations can be lost while every noun survives, so the evaluator has to detect causal or dependency loss, negation reversal, and reassignment of actor or source where fixtures require them. Provenance can be lost while prose survives, and that leaves Chapter 19 with nothing to adjudicate, so it is measured here.
Summarisation can promote assumptions to facts
Laban et al. (2025) report premature assumptions and anchoring to early answers in multi-turn interactions, with lower temperature not eliminating the problem in their evaluated conditions. That is evidence about multi-turn behaviour, not a direct experiment on compaction-induced status mutation. The latter is a failure mode this chapter proposes to test: an early note saying the serializer might corrupt timestamps could become a summary saying it does. No new proposition needs to be invented; dropping “might” changes the claim’s epistemic standing. A preservation check must therefore distinguish a user’s requirement, a tool observation, the model’s tentative hypothesis and a verified finding, rather than treating them all as equally established narrative history.
Failure dimensions
Omission is not the only way to fail, because compaction generates as well as removes. The failures are dimensions, not mutually exclusive bins. One transformation can produce several, and a status mutation is arguably also a mutation of content:
- Content omission: required information is missing.
- Content mutation: information survives altered, such as 5432 becoming 5433.
- Unsupported addition: the output asserts what the source never established. Pruning cannot do this, and compaction can.
- Status mutation: a possibility becomes a fact.
- Provenance loss: the claim survives and its source does not.
- Relation loss: the parts survive and their connection does not.
Additions are counted with a frozen definition and separated into mutation of an existing proposition, entirely unsupported assertion, and epistemic strengthening.
Selection failure and transformation failure
A compactor can fail in two places:
SOURCE → selection → what must survive → transformation → COMPACT OUTPUT
Selection failure means required information was not chosen for preservation. Transformation failure means it was chosen and represented incorrectly. They are different failures:
selection failure ≠ transformation failure
The experiment can distinguish these failure locations only if it records the intermediate keep specification. When the compactor is supplied a frozen, complete keep specification and then misrepresents one of its listed obligations, the observed failure is in transformation under that specification. If an ordinary compactor omits an obligation from its own proposed keep list, that is a selection failure; if it selects the obligation but fails to preserve it, that is transformation failure. Without an inspectable selection record, an omitted output item alone does not identify which stage failed.
Compaction is selection under uncertain future demand, and two uncertainties are involved: what a future task will require, and whether a transformation preserved a declared obligation. A safety constraint needs preservation whether or not a hidden probe happens to ask about it, so preservation obligations are scored independently of downstream probes. Otherwise unqueried, destroyed constraints would look harmless. The oracle condition receives the hidden requirements that ordinary compactors do not. It is a selection oracle and measures how much of the difficulty is prediction, and it does not claim to solve representation.
The compactor’s own report of what it preserved is a producer claim and not evaluation ground truth:
producer claim ≠ evaluator measurement
Survival is measured by an evaluator from the frozen source, the frozen obligations and the output.
Repeated compaction
One compaction is the unit of analysis. Long sessions compact repeatedly, and that is a different mechanism:
recursive:        S0 → C1;  C1 + Δ1 → C2;  C2 + Δ2 → C3
source-grounded:  S0 → C1;  S0 + Δ1 → C2;  S0 + Δ1 + Δ2 → C3
Recursive compaction can propagate earlier errors because later rounds operate on earlier summaries. Source-grounded re-compaction instead makes the frozen original evidence available again for every round; this removes one propagation path but can increase input volume, latency and cost. Both can still omit or mutate obligations in any individual pass. A third approach, described in the cited September 2026 preprint, avoids compacting an earlier compact block and compacts only newly accumulated material. That scheme does not, by itself, recover an obligation already lost in the retained compact block. The book tests recursive and source-grounded forms first and includes the third only if its procedure can be reproduced and its lineage measured.
Drift, if the word survives, has an operational meaning: change across compaction generations relative to the frozen source obligations, in invariants, identifiers, relations, unsupported assertions, status and provenance. Survival across rounds is reported against the original obligations and not only against the previous summary, or a catastrophic early loss would disappear from later metrics. Round-local and cumulative preservation are reported separately.
Two operational cautions apply. A serving-research preprint reports that prompt instructions exert weak control over the volume of a compaction’s output, with retained content varying run to run, so the requested target and the realised size are both measured, with variance across repeats. And timing is an independent design variable, consistent with Chapter 10’s separation of eligibility from timing:
transformation eligibility ≠ transformation timing
Cost, cache and the observation boundary
Model-driven compaction can incur its own input and output charges, while deterministic transformations may have different costs. A replacement also changes the rendered request and may move the first divergence with a previously reusable prefix; that does not by itself prove a cache miss or a cost increase. Following Chapter 9, the evaluation records structural divergence separately from provider-reported cache reads and writes where available, and marks absent telemetry unobserved. It also distinguishes management overhead, subsequent input occupancy, provider billing, latency, information survival and downstream behaviour. A compactor may save occupancy but cost more overall, or save money while losing a constraint. None of these outcomes is inferred from compression ratio alone.
Some compaction is opaque. OpenAI’s documentation describes a compaction feature that returns an encrypted compaction item and instructs callers to pass it through unmodified. Whatever it contains, the change is in what can be observed:
inspectable:   source → output              (compare directly)
opaque:        source → opaque state → behaviour
Chapter 2’s laws apply: unobserved is not absent, and a proxy is not an observation. For an opaque representation, targeted downstream probes can measure survival indirectly, and probe success is not direct inspection. The book makes no claim about what an opaque state contains.
Anthropic’s harness article adds a structural point from the inspectable side. Long-running agents can leave work unfinished across context windows, and continuity is built through explicit artefacts. What follows is narrow: possessing a compact context does not by itself establish continuity across windows, so a claim about a summary is a claim about measured continuity and not about the summary object.
What the evidence supports
The sources differ in kind, and none is generalised beyond its setting.
| Source | Evidence type | Verified result | Chapter adopts | Does not establish |
|---|---|---|---|---|
| Compaction Cliff (Zerhoudi, Mitrovic, Granitzer) | Preprint, CIKM 2026 listed | Claude Code’s /compact prompt on Sonnet 4.6 retained 53% of safety rules after one round and 10% after five, across 20 production configurations; the authors’ defence is type-specific operators |
A single compaction prompt can lose strict items | That all compactors do; why they do |
| Cim et al. | Preprint | Prompt instructions exert weak control over summary volume and retained information varies run to run (HotpotQA, LoCoMo; 8B–120B models) | Measure target against realised size, with repeats | That all summarisation behaves so |
| Anthropic engineering guidance | Vendor guidance | Compaction preserves architectural decisions, unresolved bugs and implementation details while discarding redundant tool outputs; clearing old tool results is a lighter form | The practice being tested | Measured effectiveness |
| DCP | Implementation | Appends protected tool outputs to its compression summary; its lossy summarising tool is separate from its pruning | An instance of selective compaction | Preservation effectiveness |
| Magic Context | Implementation | Chronological summary compartments replace older raw messages, and durable knowledge is extracted in the same pass | Current raw state kept apart from generated history | Effectiveness; tier design (Chapter 12) |
What the retention policy hands the compactor
Chapter 11 consumes the retention policy that Chapter 7 derived from item properties, environment capabilities and task-relative state. It does not use intrinsic classes: the object is the item, and the state is the derived policy outcome for it. Where a PIN-governed obligation applies, the item may not be transformed below its floor. Where the derived policy permits compression, lossy transformation is allowed subject to explicit preservation obligations. Where it permits discard, Chapter 10 should normally have removed the item before this stage, and compaction should not invent a reason to transform it. Where it permits externalisation or re-fetch, the item may be represented through a tested recovery path or be absent under identity and fidelity conditions, and Chapters 13 and 14 own that machinery. One item can be recoverable, exact in one field, compressible in another representation and unnecessary for the current computation, so this is not a dispatch table.
For the experiments, a compaction run has an inputs-and-outputs contract. This is experimental instrumentation and not a production requirement:
- In: source context, target budget, preservation obligations and floors, provenance requirements, and optional recovery identities.
- Out: the compact representation, a transformation trace, and the producer’s claimed preservation status.
- Recorded beside it: source and output representation identifiers, source lineage, round, method, model and configuration, policy version, target and actual budget, and evaluator-side measurements for survival, unsupported additions, status and provenance. Lineage has to make it possible to say whether summary four consumed summary three or original evidence.
Proposed experiments
Nothing here has been run. In both, the unit of analysis is the trajectory fixture, and stochastic repeats of one fixture are not independent examples. Fixtures, conditions, rounds and repeats are reported separately.
Frozen before any run: the source, preservation obligations and floors, required statuses, provenance requirements, the downstream probes and the policy mapping. The compactor receives the history, the current task, the retention policy and a target budget. It never receives the hidden probes, except in the oracle condition.
Experiment 1: one round. Conditions are untransformed history, uniform semantic compaction, policy-aware compaction and a selection oracle. The untransformed condition is a preservation reference, not necessarily a behavioural upper bound. The selection oracle receives frozen future-task requirements unavailable to ordinary compactors, but uses the same transformation mechanism and target budget as the matched policy-aware condition; its advantage estimates the value of that additional selection information under the tested tasks, not a universal upper bound on compaction quality. To distinguish selection failure from transformation failure, a separate diagnostic condition supplies a frozen keep specification and records whether every selected obligation survived. Target tokens, achieved tokens, tolerance violations and transformation overhead are reported for each condition; if achieved sizes differ materially, survival and behaviour are interpreted conditional on achieved size rather than credited entirely to the policy.
Experiment 2: repeated compaction. Recursive against source-grounded re-compaction over one, three and five rounds, with the discard-and-restart challenger included only if reproducible, and lineage recorded for every summary. The same preservation categories are recorded each round against the original obligations.
Evaluation. Preservation is evaluated against the original source and frozen obligations before downstream behaviour is interpreted. Each category retains its own numerator and denominator: 95 per cent survival of narrative obligations alongside 10 per cent of exact constraints must never be collapsed into an apparently reassuring overall success rate. Use typed equality for fields, byte-exact or explicitly normalised comparison for identifiers, categorical checks for status, source-identity checks for provenance, and frozen rubrics for relations and semantic requirements. Where judgement requires a model, blind it to condition labels, measure agreement on a human-labelled calibration subset, report unresolved disagreements and retain original examples for audit. Then compare downstream task success, constraint violations, unsupported claims and recovery success across conditions, distinguishing information absent from the compact output from information present but unused. A behavioural failure alone does not prove the compaction caused it without the corresponding control.
Outcomes that count. Uniform compaction may match policy-aware compaction; policy-aware compaction may protect strict obligations while missing the budget or adding unacceptable overhead; source-grounded and recursive methods may behave alike, or source-grounding may preserve more at prohibitive cost. An opaque method may match inspectable methods on observed probes without proving equivalent internal preservation. Category survival may improve without downstream gains, or task success may improve despite lower measured survival. If judges disagree beyond the preregistered tolerance, the finding is unresolved. If policy-aware compaction shows no reliable preservation advantage at comparable achieved budgets, its extra machinery has not earned a claim of benefit in these conditions. The chapter retains the distinction between intended and demonstrated preservation regardless of which method wins.
The single-threshold design
A common, simple design has one threshold: full history, then one compact representation. That creates an abrupt transition with no intermediate state:
raw ── abrupt threshold ──▶ summary
Not every system works this way. But the design raises the question the next chapter has to answer, and does not answer it in advance:
If a single jump from raw history to one compact representation gives the runtime little control over how fidelity is surrendered, can representation change happen through explicit intermediate states whose losses are visible, bounded and testable?
The engineering problem is not producing a good summary. It is showing which obligations survived the transformation.
References
- Zerhoudi, S., Mitrovic, J., Granitzer, M. “The Compaction Cliff in Long-Running AI Agent Memory.” arXiv:2608.22752, August 2026; the arXiv page lists the Proceedings of CIKM 2026 as its journal reference. Author-reported. https://arxiv.org/abs/2608.22752
- Cim, M., Topcu, B., Das, C., Kandemir, M. T. “Parallel Context Compaction for Long-Horizon LLM Agent Serving.” Preprint, arXiv:2605.23296, May 2026. https://arxiv.org/abs/2605.23296
- Nguyen, T., Cho, E., Chen, B., Dettmers, T. “CliffCompaction: Cost-Efficient Compaction for Long-Horizon Coding Agents.” Preprint, arXiv:2609.26779, September 2026. https://arxiv.org/abs/2609.26779
- OpenAI. “Compaction.” Official documentation, September 2026. https://developers.openai.com/api/docs/guides/compaction
- Anthropic Applied AI team. “Effective context engineering for AI agents.” Published 29 September 2025. Vendor engineering guidance. https://www.anthropic.com/engineering/effective-context-engineering-for-ai-agents
- Anthropic. “Effective harnesses for long-running agents.” Published 26 November 2025. https://www.anthropic.com/engineering/effective-harnesses-for-long-running-agents
- Tarquinen. “Dynamic Context Pruning Plugin (DCP).” OpenCode plugin, AGPL-3.0-or-later, verified September 2026. Implementation facts only. https://github.com/Tarquinen/opencode-dynamic-context-pruning
- cortexkit. “Magic Context.” Context plugin, MIT, verified September 2026. Implementation facts only. https://github.com/cortexkit/magic-context
- Laban, P., Hayashi, H., Zhou, Y., Neville, J. “LLMs Get Lost In Multi-Turn Conversation.” arXiv:2505.06120, May 2025. Preprint. https://arxiv.org/abs/2505.06120
Research
Not yet researched
This chapter has not yet been researched.