Memory Is a Context Source
Treat memory as one durable source of candidates entering the common admission machinery, ask whether it needs any special admission mechanism at all, and make restraint a tested capability.
Here is an illustrative case. The current request says, verbatim, “Do not modify the existing migration.” The available memory contains months of migration history: previous plans, old decisions and the project’s earlier migration work. The runtime admits that history, and the model proposes the modification it was told not to make. Suppose every remembered item was stored accurately and recovered correctly. That would rule out some storage and recovery failures, but not establish that admission alone caused the violation: the model might also fail to follow the present instruction without the memory. A controlled comparison is needed to attribute the behaviour. The example isolates the architectural risk that correctly retained past information can be inappropriate for the current computation:
memory correctness ≠ context appropriateness
This chapter asks a narrow, architectural question, since memory itself belongs to the sibling Memory book. Once a memory system exposes durable past information as candidates, should those candidates be admitted differently from candidates from any other source? A second question follows. Can the system correctly admit no memory at all when the present computation does not need the past?
Memory is not context
The two objects are defined differently, and each definition comes from its own book:
Context is the information made available to a model for a particular computation.
The Memory book, an unpublished sibling manuscript, begins with a behavioural distinction: retained past experience can change present behaviour, while useful memory changes it in a way that improves the outcome under the current goal and constraints. Its counterfactual removes or changes the past information and compares the resulting behaviour and outcome. This chapter borrows that distinction rather than treating all behavioural influence as benefit. It also separates two senses of the word. A memory system, store or item names an architectural origin, while a demonstrated memory effect names a behavioural result under a specified comparison. A stored item is neither a demonstrated effect nor proof of useful memory:
memory-source item ≠ demonstrated memory effect
So memory stored ≠ memory in context. A store may hold thousands of durable items, none currently admitted, while a bundle may hold instructions, tool definitions, observations, retrieved documents and agent state, most of which does not come from a memory store. The sibling book’s shorthand, memory is durable and context is selected, is a distinction of engineering concerns at this boundary, not two mutually exclusive definitions. Memory systems themselves select, transform and admit material, and context can contain durable information. The relevant asymmetry is this:
retained because it may matter later
        ≠
admitted because it is justified for this computation now
Future potential is not present admission justification, and a memory retention policy is not an admission policy. A good store can correctly hold far more than any invocation should see.
Where the Context book begins
PAST EXPERIENCE → MEMORY SYSTEM → durable memory state
        → memory candidate generation → memory candidate pool
================= memory / context boundary =================
        → common candidate interface → [Chapter 14](/books/context/14-chapter/) admission
        → recovery, representation and extent as needed
        → context assembly → model → behaviour
Everything above the line, including storage, consolidation, truth maintenance, forgetting and memory candidate generation, is upstream and is not taught here. Temporal status and validity still matter after the boundary: the candidate carries available dates, versions and supersession evidence, while Chapters 19 to 21 govern how the assembled context treats that evidence. The chapter takes the candidate pool as given and reuses Chapter 14’s machinery: admission, representation versus extent, progressive disclosure, sufficiency, and the distinctions between presence, behavioural use and helpfulness. The stages are conceptual rather than a compulsory execution order: an admission policy may reject a candidate from metadata without fetching its full payload, and the assembler may still reject a requested candidate. Failures are attributed by stage:
- Memory candidate miss: the required item never reached the pool.
- Recovery failure: a candidate that is an external reference did not resolve (Chapter 13).
- Representation failure: an upstream transformation lost something, so admission may be correct for the candidate it received.
- Admission failure: the required item was in the pool and was not admitted appropriately.
- Adjudication: authority, freshness and scope decisions belong to Chapters 19 to 21.
- Downstream behavioural failure: the right material was admitted and behaviour did not use it.
memory candidate miss ≠ admission failure ≠ downstream behaviour failure
The chain runs one stage further left than Chapter 14’s:
retained ≠ surfaced as candidate ≠ recovered ≠ admitted ≠ used ≠ helpful
Where the sibling Memory work uses “retrieval”, this chapter maps its output to candidate generation. Chapter 13 keeps “recovery” for resolving an external representation.
Memory enters through the common interface
The default architectural hypothesis is that memory can be adapted into the common candidate interface, feeding the same admission machinery as files, tool outputs and agent-generated state, unless controlled comparisons show a material need for source-specific treatment. This is a proposed architecture, not a result. Common does not mean metadata-blind: the interface can preserve source_kind = memory and memory-specific fields when they matter, without requiring a separate admission pipeline. But a source-kind label alone is not evidence provenance:
memory origin ≠ evidence provenance
A candidate may also need its source memory system, originating observation or document, producer, representation identity, version, temporal metadata, epistemic status, scope, and evidence lineage. These fields may be observed, declared or unavailable; an adapter must not fabricate what its source does not provide. Chapter 15 established that persisted generated claims need status and lineage. If an unverified hypothesis becomes a memory-source item, retention does not verify it: memory retention ≠ epistemic promotion. Durable is not authoritative. A remembered assistant suggestion does not become a user instruction or project policy merely by being stored, and Chapter 19 governs its standing. Memory origin alone confers no admission priority.
The adapter transports the metadata the source can actually supply, labels missing fields and records any transformation. Its contract is to preserve available identity, representations, provenance, time, status, scope and cost estimates without silently upgrading an unknown to a verified value. It does not itself decide authority, freshness, scope validity, admission or order; later policies make those decisions, including an explicit decision when required metadata is missing:
metadata preservation ≠ policy adjudication
It does not have to claim that an item is true, only what the memory system can support about status. Temporal metadata, such as when something was observed or by whom it was superseded, is not a freshness judgement, which is Chapter 20’s. Where memory conflicts with current evidence, both keep their source, time and status, conflict detected is not conflict resolved, and later governance decides.
Working state and reuse
Chapter 15 asked what an agent creates during its trajectory. The boundary between working state and memory-source state is functional, not temporal. Working state is retained primarily to continue the active trajectory, and memory-source state is retained primarily because it may be useful beyond the trajectory that produced it:
continuation obligation ≠ reuse potential
An item can satisfy both, so the two sets may overlap and there may be no single graduation moment. A progress.md kept overnight for tomorrow’s task is working state, and a six-month-old decision consulted by a new task is memory-source state however briefly it is read. Age does not define the boundary. What is retained and what enters context are separate decisions.
Inspect this in the Context Viewer
The viewer scene for this chapter holds the boundary open: four stored memories, two surfaced candidates, zero admitted for the present-only task, with the do-not-modify constraint resident. Open the scene and count each stage separately. What to examine: stored versus surfaced versus admitted versus used — and why the empty admission here is deliberate restraint from a verified pool, not retrieval failure. Whether restraint helps would need a matched comparison; none is run.
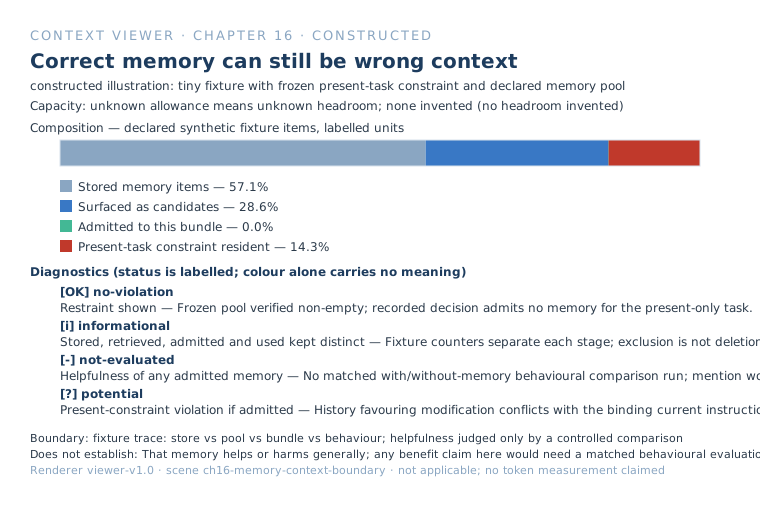
Open the memory scene in the Context Viewer
Restraint
Memory restraint is the ability to leave available durable history out of the current model input when admitting it would not satisfy a present-task requirement or would add unnecessary risk or cost.
Restraint is not retrieval failure and not unavailability. The memory is available, and the system declines to admit it, which can be a successful outcome. “Project uses PostgreSQL for its event store” may be correct, current and well-provenanced, and the right decision on “Rewrite this paragraph for clarity” is to admit nothing. So:
memory available  ≠  memory should contribute
context exclusion  ≠  memory deletion
candidate rejected  ≠  resident item pruned
A rejected candidate remains in the upstream store under that store’s retention policy; rejecting admission does not delete it. For some computations, the oracle may identify the empty set as a sufficient memory contribution. But an empty memory contribution is meaningful only with the current task, resident context, available candidate pool and acceptance criteria fixed. It is not necessarily proof that the task is answerable: the correct outcome may instead be abstention or a request for missing information. Historical relevance grants no priority over an applicable present constraint. Chapter 19 owns general precedence and Chapter 23 owns final assembly.
How would we tell restraint from a broken memory system? The answer needs a frozen candidate pool with known availability, negative-control tasks and separate candidate-generation metrics. A system that admits nothing because nothing was ever surfaced has not shown restraint.
A short illustration shows why metadata survives the boundary. The store holds “SQLite used before July” and “PostgreSQL active”. Stripped to anonymous prose they read as a contradiction, and with their status and time intact they are a history and a current fact. Later chapters decide how freshness, authority and scope apply. The chapter asks only that admission not lose the markings.
What the sibling project measured
The sibling project’s reported runs are described in its manuscript and companion evidence register. They motivate this chapter but are not independent evidence for its proposed admission architecture. The manuscript describes a small local reader at temperature zero on synthetic fixtures with varied memory conditions and fixed task framing, including nine controlled tasks and five transfer tasks. The table reproduces those reported results, rather than treating the unpublished manuscript as an independently replicated study. Where an individual outcome has not been rechecked against its original run artifact in this review, the table remains a report of the sibling work, not a new verification.
| Finding | Evidence | Population | Chapter use | Limitation |
|---|---|---|---|---|
| Assembled memory roughly doubled task success against no memory, from about 0.23 to about 0.49 over seven matched tasks | Stored matched means | One small reader; synthetic fixtures | Memory can change behaviour | Not independent; not a general effect |
| Removing the decisive item lowered success, and restoring it raised it; replacing it with distractors did not recover the benefit | Removal, restoration and distractor conditions | Same | Causal evidence from an intervention | Same |
| Deliberately wrong memory drove harmful actions | Positive-control condition | Same | Admitted memory can influence behaviour | Says nothing about admission |
| A present-only task got worse with supplied memory | One task in the run | Same | A motive for restraint tests | One task |
| Full undifferentiated history left the small reader worse off than no history, while a stronger reader did well on it | Two readers | Two readers | Sufficiency is reader-relative in these fixtures | Two readers only |
| On the stronger reader a frame-selected bundle beat the assembled one, reversing the small reader’s order | Stronger-reader run | One stronger reader | Selection quality ≠ behavioural quality | One run |
These findings are consistent with memory influencing behaviour in the sibling fixtures, sometimes helpfully and sometimes harmfully, and with the observed benefit depending on the reader and representation. They do not establish that a memory item mentioned by a model was causally used, that Chapter 14’s admission policy works, or that memory requires its own admission mechanism. Reported mean differences also require their matched-task denominators and uncertainty to be retained when reused as evidence:
memory benefit ≠ memory-specific admission benefit
One further reported result, about the stronger reader on arbitrary-history tasks, could not be traced to a stored run and is not used.
Two external benchmarks are used narrowly. Mem2ActBench (ACL 2026 long papers) synthesised 2,029 sessions and 400 tool-use tasks, 91.3 per cent human-judged strongly memory-dependent, and reports that seven memory frameworks were inadequate at grounding tool parameters from memory. MemoryArena (arXiv v2, September 2026, ICML 2026 listed) reports that agents near saturation on long-context memory benchmarks such as LoCoMo perform poorly in interdependent multi-session agentic tasks. Each supports one point, that recalling a fact is not using memory to act. Neither tests admission, restraint or a candidate interface.
What Context still has to test
The sibling project asked whether memory helps. The Context-specific question is whether memory needs anything special in admission. Nothing here has been run, and the sibling evidence is not treated as if it had answered this.
Ecological gate. Before building memory-specific machinery, describe real traces: the share of computations for which memory candidates are available, how many are surfaced, pool sizes, how often tasks demonstrably require prior information, and how often the resident context already suffices. Report related-but-unnecessary memory, redundancy, conflicts with current evidence, memory’s admitted token share, rejection rates and repeat readmission. Separate available, surfaced, requested, successfully recovered and admitted material; otherwise an empty admitted set cannot distinguish deliberate restraint from upstream absence or a recovery failure. Compare memory candidates descriptively with file, agent-state and tool-produced candidates:
memory admission can matter ≠ real workloads present enough ambiguous memory candidates to justify special machinery
If memory candidates show no distinctive behaviour once metadata is normalised, that supports the flat architecture. The corpus of real sessions is empty.
Experiment A: generic versus memory-specific admission. Given the same frozen pool, does generic Chapter 14 admission perform as well as a specified memory-specific policy? Freeze upstream memory, candidates and ranking, identities, representation versions, provenance, status, lineage, temporal and scope metadata, task, resident context, model, decoding settings and resource budget. No extraction, consolidation, retrieval or truth maintenance varies. Conditions are no-memory, admit-all, predeclared top-k, generic admission, generic admission with source-kind metadata if that is a genuinely different input, a concrete memory-specific alternative only when its rules are specified independently of results, and a hindsight oracle. Give every policy equal access to the fields the common interface can represent; otherwise apparent superiority may be caused by unequal information rather than a need for a separate subsystem. The oracle may identify multiple sufficient sets, including the empty set. Fixtures include necessary memory, helpful but optional memory, valid irrelevant memory, redundancy, history that is true of the past but superseded as current state, a present-only task, and a conflict with a declared binding current constraint. Wrong memory is an influence positive control and is excluded from the headline policy comparison. Report coverage of required obligations, unnecessary admitted tokens, policy overhead and achieved budget alongside task success, grounded tool parameters, constraints respected and correct abstention. Record which candidates were actually assembled, not merely selected. Memory citations and mentions are not evidence of causal use; use matched ablations where causal influence is claimed. The consuming reader and evaluation criteria are frozen, so no result is called universally sufficient.
Experiment B: restraint. Can the system decline to admit available, valid, topically related memory when the current computation does not require it? Use adversarial negative controls, such as rewriting a migration description without changing its technical content while rich and plausible migration history is available. Freeze and verify the surfaced candidate pool so that zero admission is not confused with retrieval failure. Compare no-memory, admit-all, top-k, generic selection and any specified challenger under the same current context and budget. Score empty-set decisions and unnecessary memory tokens separately from present-constraint violations, unsupported historical references, behavioural changes under memory ablation, and management cost. Include positive-control tasks that genuinely require a memory item: a policy that rejects everything must fail those tasks, even if it excels on the negative controls.
Optional Experiment C: decisive-item removal and restoration. The sibling project already ran one. It is worth repeating here only if the candidate interface, admission mechanism or reader differs, or it is needed to validate this book’s instrumentation, and the chapter states what new uncertainty it would resolve.
Outcomes that count. Admitting all matches generic selection. Generic admission matches a memory-specific policy, so one common pipeline is kept. Source-kind metadata adds nothing. Present-only tasks perform equally with memory, or they worsen, which shows restraint matters. Topically related valid memory is often admitted needlessly. Status metadata prevents regression, or makes no difference. Real workloads rarely expose memory candidates.
The architectural falsifier. Memory-specific admission is justified only if a defined memory-specific alternative achieves a meaningful advantage over a common interface with equally rich metadata under controlled tasks and comparable costs, or if a required semantic obligation demonstrably cannot be represented by that interface. Temporal validity, lineage, confidence, repeated-readmission history and representation choices are not evidence for a separate subsystem merely because they occur in memory: first test whether they can be carried as ordinary typed candidate metadata. Conversely, if generic admission matches the specialised alternative on behaviour, restraint, obligation coverage and resources across the declared fixtures, the additional subsystem has not earned its complexity in those conditions. The conclusion is conditional on the tested readers, tasks and interfaces, not a proof that memory can never require special handling.
What travels forward
Memory arrives through the common candidate interface with its source kind and preserved metadata. No memory-specific subsystem is added to the compiler: no memory hierarchy, separate candidate type, extraction system, consolidation machinery or long-term belief store. A memory system can be excellent precisely because it remembers information that a context system should usually refuse to show. Memory contributes durable historical candidates that must earn present influence. Tools contribute on both sides of execution: standing capability descriptions that occupy context before any call, and fresh observations after it. One source asks what the past may still decide, and the other asks what the present affords and what it just produced. The next chapter takes the second.
References
- Memory book (sibling manuscript, unpublished). Background for the behavioural definition of memory and the durable-versus-selected framing, and the source of the findings tabulated above. Its findings are sibling-project evidence, not independent replication, and the runs behind them are listed in the companion repository’s evidence register.
- Shen, Y., Li, K., Zhou, W., Hu, S. “Mem2ActBench: A Benchmark for Evaluating Long-Term Memory Utilization in Task-Oriented Autonomous Agents.” ACL 2026 long papers, pp. 8173–8190. https://aclanthology.org/2026.acl-long.370/
- He, Z., Wang, Y., Zhi, C., et al. “MemoryArena: Benchmarking Agent Memory in Interdependent Multi-Session Agentic Tasks.” arXiv:2602.16313 (v2, September 2026; ICML 2026 listed). https://arxiv.org/abs/2602.16313
Research
Not yet researched
This chapter has not yet been researched.