Tools Produce Context
Account for tools on two independently governed surfaces: capability representations that occupy context before execution, and results that become candidate information after it, and test what saving context on either side can lose.
Here is an illustrative case. An agent starts a routine task with fifteen integrations connected: file tools, shell, search, web, database, issue tracker, chat, calendar, drive, deployment, monitoring. Suppose its harness exposes descriptions for operations it may never call, even before it reads a project file. Then it runs one search, and the runtime admits a very large list of matches for a question answerable from a dozen lines. A tool can charge the context budget before it executes and again after it executes.
The title is shorthand. Tools produce potential context, meaning candidate information, and context exists only after the runtime admits it:
tool output ≠ context
This chapter accounts for both charges and asks what each mechanism that saves context might lose. It does not own generic admission (Chapter 14) or generic representation (Chapter 18). Authority, freshness and scope belong to Chapters 19 to 21.
Two surfaces
The capability surface is the model-visible representation of executable possibilities: name, description, input schema, and where exposed an output schema, annotations, examples or server instructions. Not every runtime exposes every element. The observation surface is the representation of execution results, errors, structured output, references, logs and metadata that the runtime ultimately makes model-visible. Raw tool results are not yet that surface; producer shaping and consumer admission determine what reaches it. Each surface has its own pipeline, and every arrow can fail:
CAPABILITY SIDE
runtime capability universe → capability candidates → exposure
  → model-visible capability → model selection → call

EXECUTION SIDE
call → raw result → producer-side shaping → observation candidate
  → consumer admission → model-visible observation → behaviour
The laws follow the stages:
tool exists  ≠  tool exposed  ≠  tool selected  ≠  tool executed
tool call emitted  ≠  observation obtained
raw result  ≠  observation candidate  ≠  admitted observation
tool returned x  ≠  model observed x
The last one applies Chapter 13’s boundary: if the runtime filters, truncates or references a result before admission, the resulting model invocation cannot be credited with observing details absent from its captured input. The observer can establish that boundary-level absence, not everything a provider may supply outside the capture.
Standing capability cost
Capability exposure means making a representation of a runtime capability available to the model for the current computation. A runtime can have a hundred tools and expose eight, so the tool available to the runtime is not the tool exposed to the model. Standing capability cost is the model-input cost of exposed capability representations regardless of whether they are executed in that invocation. Provider caching can change what that costs to process or bill, so standing token occupancy ≠ standing billed cost (Chapter 9).
Tool count is not capability cost:
tool count ≠ capability-surface size ≠ capability ambiguity
Ten well-separated tools may be easier than three overloaded ones. Schema tokens are also not waste, since a richer schema may prevent invalid calls, retries and repair prompts, so definition minimisation ≠ trajectory minimisation. Examples are part of the capability representation, and its components (name, description, schema, examples, annotations) can be measured separately where the runtime exposes them.
Execution-side cost is not one number either. It includes the representation of the call, the admitted observation, follow-up calls caused by insufficient output, recovery or continuation, and repair after wrong or invalid calls. A tool can be computationally expensive and cheap for context, or the reverse, so tool execution cost ≠ tool context cost. The right accounting horizon is the whole trajectory, with each occurrence counted once and with tool execution charges separated from model-context occupancy. The schematic below lists categories rather than a provider billing equation:
trajectory tool-context cost = capability occupancy + call representations
    + admitted observations + recovery or continuation + repair interactions
Cache and billing are observed separately, and no composite scalar is defined unless a deployment defines one. Trajectory evaluation and stage attribution are both needed.
Tool count can degrade capability
Paramanayakam et al. (2025) demonstrate that a quantized Llama 3.1 8B fails a GeoEngine benchmark task when given 46 tool definitions but succeeds when given only 19, even though the original context fits within the model’s advertised window. This was a particular model and benchmark example, not a general threshold of 19 or 46 tools. The failure is not an overflow problem; it is context confusion (Chapter 5). The Berkeley Function-Calling Leaderboard documents differences in model performance across function-calling tasks of varying complexity, including multiple and parallel calls and irrelevance detection. These comparisons motivate investigation of tool-selection failures, but do not by themselves isolate the causal effect of exposing additional tool definitions for an otherwise identical task.
The reported example motivates a hypothesis rather than isolating a general cause: exposed tool definitions occupy context before any call, and reducing the exposed set may help or harm tool use. Only a controlled comparison with equivalent executable capabilities can isolate the effect of exposure. The follow-up article by Breunig (2025) names the approach of dynamically selecting relevant tools a tool loadout — an agent could have access to a hundred tools without exposing all hundred definitions to every invocation. This is an implementation pattern worth testing, but the chapter does not prescribe a model-based tool selector without first testing a simple deterministic selection policy.
Equivalent capability, different representation
The two suites find_user, find_project, find_issue and search(resource_type, query) may or may not expose the same underlying operations. If they do not, tool architecture is confounded with capability coverage. The question is not many tools against few. It is: given equivalent executable capability, how does the model-facing decomposition of that capability affect standing cost, selection, argument construction and trajectory cost? An overlap of names such as search_files, find_files and grep_files is an illustration of possible ambiguity, and similar names are not demonstrated confusion until tested. Anthropic reports that choosing prefix or suffix namespacing had non-trivial effects on its tool-use evaluations, with effects varying by model. That is vendor-reported evidence for its tested models and tasks, and it does not show that namespacing solves ambiguity.
Capability discovery is selecting which capability representations become model-visible from a larger universe. It is the capability-side analogue of Chapter 14’s admission, and it has the same failures:
capability exposure miss ≠ tool-selection failure
Under model-selected tool calling, the model cannot directly select a capability whose model-visible definition was withheld. The runtime may still execute hidden capabilities on the model’s behalf, so exposure is not the same as executable availability. Discovery also has a stopping problem: when the exposed set looks sufficient, that does not show that an undisclosed capability would not have been better. Anthropic’s Tool Search Tool defers most definitions and keeps a few tools always loaded. That is one implementation policy, and pinned critical tools are not a universal law. A dynamic change to the tool block may move the first divergence of rendered requests. Whether the provider reuses less work is a separate observation requiring cache telemetry. The MCP draft specification says servers should return tools in a deterministic order, stating that this enables clients to cache the list and improves prompt-cache hit rates when tools are in model context. That is a SHOULD with an explicit rationale.
Producer shaping and consumer admission
A raw response is a machine data structure and not a context policy. Two decisions act on it:
producer-side shaping ≠ consumer-side admission
Producer-side shaping can occur before the final observation candidate is offered for admission; it need not mean that no intermediate candidate or raw result exists: query filtering, aggregation, field selection, pagination, bounded excerpts, structured projection, reference generation. Chapter 14 owns admission of the resulting candidate. The operations differ from one another: filter ≠ summarise ≠ paginate ≠ reference ≠ truncate. Filtering selects fields or items under specified criteria, summarising transforms representation, pagination controls extent across requests, a reference points to a payload subject to a recovery contract, and truncation drops content beyond a mechanical bound. These operations may be combined, and their completeness and provenance effects must be recorded independently. “Concise” hides which one happened.
Shaping can itself be lossy:
producer-side reduction ≠ safe reduction
Less output does not mean the required information survived (Chapter 11). Deterministic code can be consistently wrong, so deterministic ≠ correct. Where an operation is correctly specified, computing outside the model context can reduce intermediate model-visible state and repeated agent calls, although the intermediate steps are not model-visible unless admitted separately. They remain auditable only if the runtime actually records them, with sufficient identity, inputs and error information. Anthropic’s code-execution article illustrates the pattern with a 10,000-row sheet filtered in code before the model sees it, and reports a 150,000-token to 2,000-token reduction for loading tool definitions on demand. Consolidated tools may hide intermediate decisions, failure points and partial results from the model; retaining them in an external execution trace is a separate design choice. Fewer model-visible steps do not by themselves establish a better operation.
The vendor’s tool-design guidance recommends high-signal responses with a verbosity control, and gives an example of about 206 tokens detailed against about 72 concise. It suggests combining pagination, range selection, filtering and truncation with sensible defaults, notes a 25,000-token default response limit for Claude Code, and says no format such as JSON, XML or Markdown wins universally. The last point is Chapter 18’s.
Completeness
An observation should carry a completeness status in addition to its content. Conceptually, a result records an outcome such as success or error separately from coverage properties such as complete, filtered, paginated, truncated or reference-only. These are not exclusive states: a filtered response may also be paginated and an error may accompany partial output. These are experimental statuses and not production enums, and “complete” means complete under the query, projection, pagination, time and source contract, not a complete description of the world:
protocol complete ≠ world complete
A page is not a complete result. Pagination is a continuation contract, which is explicitly incomplete and supplies a way to request another extent, and continuation available ≠ continuation performed. That is Chapter 14’s stopping problem again. Silent truncation can cause omitted items to be read as absent, and a truncated result should say so, where, and how to continue. The strongest consequence:
not observed ≠ not present, and an empty result ≠ absence without a completeness contract
“No matches” depends on the query scope, permissions, pagination, filters, truncation and source freshness. An empty result supports a negative conclusion only within the declared query and completeness contract. A returned reference is not an artifact read, and a bare opaque pointer may give too little semantic information for an informed decision to expand it. A resident semantic cue with a recovery reference and a completeness status is the better shape, following Chapters 12 and 13.
Errors are observations. An error can carry the decisive fact, and actionable is not complete: a short message can omit the detail needed to repair. The MCP draft separates protocol errors (unknown tool, malformed request), which a model is less likely to fix, from tool execution errors flagged isError, which clients should provide to the model for self-correction. Trimming an error payload may also reduce accidental exposure of internals, and security is not measured here.
Gates and metadata
Capability availability, model-visible representation, execution permission, execution and result admission are logically distinct decisions even when a runtime combines some of them. OpenCode’s documentation describes an allow, deny or ask permission model with wildcards over its built-in, custom and MCP tools, and permission is not exposure or admission: available capability ≠ permitted execution, permitted ≠ required exposure, exposed ≠ executed. A denied tool whose definition stays resident still charges standing cost.
MCP annotations are metadata and not authority. The specification treats tool annotations as untrusted unless their origin is trusted; even a trusted annotation is a claim about intended behaviour, not proof of harmless execution. A declared read-only capability still requires applicable execution policy and, where consequential, verification. Tool descriptions inform capability selection; tool results are lower-trust source content. Imperative text returned by a tool is data to assess, not an instruction whose authority follows from being returned, and metadata does not independently confer governing authority (Chapter 19). A tool that can access x does not make x part of the task’s scope (Chapter 21).
Two identities matter for what follows. The same tool with the same arguments does not necessarily return the same observation, since world state changes. That is why DCP’s same-tool-and-arguments deduplication is an implementation policy and not a proof of redundancy. And an old failed call’s input is not shown irrelevant by a plugin’s rule for purging it. DCP treats tool outputs and failed-call inputs as reduction targets, keeps the latest of repeated calls, purges failed-call inputs after a horizon while keeping their messages, protects some tools, uses placeholders with history untouched, and documents a cache trade-off. Implemented is not validated, and it prunes after admission where this chapter shapes before it.
Dependencies
If resolving a reference needs a model-selected tool call, the resolver capability has to be exposed to the model and permitted for execution; a runtime-controlled resolver need only be available to the runtime. Tool-mediated information can therefore carry a capability dependency, and item tokens are not dependency-closed admission cost. The increment counts only when the resolver must additionally be admitted: a 20-token reference adds 670 input-token positions if a 650-token resolver definition must additionally be exposed, but adds only 20 if that definition is already resident. These figures describe marginal input occupancy, not billing or the full cost of resolving the reference. Pricing and closing such dependencies belongs to Chapter 23, and if the runtime resolves references automatically there is no dependency.
The evidence
These are engineering examples and specifications. None was collected on this book’s workload.
| Source | Evidence type | Verified claim | Chapter uses | Does not establish |
|---|---|---|---|---|
| Anthropic, “Introducing advanced tool use” (24 November 2025) | Vendor engineering report | Five servers with 58 tools, about 55K definition tokens, Jira alone about 17K, 134K internally before optimisation; Tool Search Tool about 72K to 8.7K with accuracy 49% to 74% (Opus 4) and 79.5% to 88.1% (Opus 4.5); examples raised complex-parameter accuracy from 72% to 90%; programmatic calling averaged a 37% token reduction; advice not to defer with fewer than ten tools | Large capability surfaces exist and dynamic exposure changed token use in those systems | Prevalence in any other workload; general accuracy effects |
| Anthropic, “Writing effective tools for agents” | Vendor engineering report | Namespacing effects vary by model; a verbosity control; a 25,000-token Claude Code response limit; actionable errors | Tool responses are context design | That any guidance is optimal |
| Anthropic, “Code execution with MCP” | Vendor engineering report | Filtering in code before results reach the model; on-demand tool definitions (150K to 2K tokens) | Producer-side shaping as a pattern | Safety of any reduction |
| MCP draft specification | Protocol specification | Tools are model-controlled; deterministic ordering is a SHOULD with a caching rationale; annotations must be treated as untrusted; two kinds of error | Exact protocol wording | Anything about behaviour |
| OpenCode tools documentation | Implementation documentation | 13 built-in tools plus custom and MCP tools; allow, deny and ask permissions with wildcards | Permission as a distinct gate | Measured behaviour |
| DCP | Third-party implementation | Deduplication, error-input purging, protected tools, placeholders, cache note | Tool output is a reduction target in practice | That its reductions are safe |
Inspect this in the Context Viewer
The viewer scene for this chapter reuses the approved capture accounting with tool detail: twelve definitions standing before any call, call representations during execution, and concentrated observations after. Open the scene and compare the capability surface with the observation surface. What to examine: the two-sided charge — definitions cost context before use, results cost it after — and the concentration of the largest results. Size is occupancy only; a large result may carry the decisive fact.
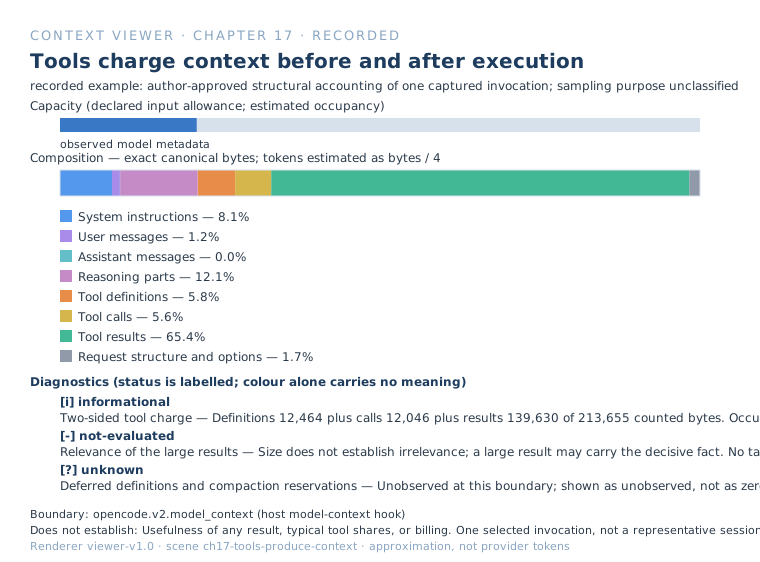
Open the tool-footprint scene in the Context Viewer
The observer
The observer records each tool’s name, description and input schema for every observed model request, at the host’s model-context hook. It does not record annotations, and it is not a provider-wire observation. Reported tokens for tool definitions depend on the capture representation and estimator, not on direct provider token attribution. Its calibration session was a deliberate test and is excluded from any corpus, so the instrument has no enrolled genuine-session corpus for the prevalence claims in this chapter:
observable ≠ observed
Nothing here has measured what fraction of a real context goes to definitions, and no sentence claims OpenCode spends any measured share. Instrumentation capability is not ecological evidence.
Proposed experiments
Nothing here has been run. The two surfaces fail independently, so they are tested separately, and the corpus of real sessions is empty.
Ecological gate. Capability side: tools available and exposed, capability tokens, stable versus changing definitions, exposed but never selected or executed tools, dynamic discovery frequency, discovery misses if observable, schema and example token share. Observation side: raw and admitted result sizes and distributions, the frequency of filtering, pagination and references, error result sizes, repeated outputs, continuation calls, and the share of active context. Before dynamic discovery, ask whether real sessions are dominated by standing definitions. Before result shaping, ask whether they are dominated by oversized outputs:
a mechanism can save tokens ≠ it addresses a prevalent cost
Experiment A: the capability surface. Given equivalent executable operations and permissions, how do exposure and model-facing representation affect tool choice, execution success and trajectory cost? Frozen: the task, backend operation semantics and outputs, model, decoding, permission state, non-tool context and objective. Tool definitions and their visibility are recorded for each invocation; capability coverage must be checked, rather than assumed, for the composable-tool condition. Conditions: an oracle capability set (hindsight, not production) defined as one of the acceptable sufficient sets under a declared criterion; many narrow capabilities; the same plus plausible irrelevant ones; fewer composable capabilities with equivalent backend semantics; dynamic discovery from a small surface; optionally a deliberately ambiguous suite as a diagnostic; and a minimal-versus-richer schema ablation if needed. Failures are attributed by the earliest established stage: capability unavailable to the runtime, required capability not exposed, wrong exposed tool selected, malformed or incorrect arguments, execution failure, observation not admitted, and downstream-use failure. A missing tool call alone cannot distinguish an exposure miss from deliberate nonselection. Metrics: whether each acceptable capability path was available and exposed, selection and valid-call rates, redundant and repair calls, task success, capability tokens, discovery overhead, latency, full-trajectory tokens, and provider cache metrics where available. Report candidate-set coverage and exact rendered definitions, not just tool count. Outcomes that count: all-tools exposure matches the oracle, irrelevant tools change nothing, composable tools save definition tokens and raise invalid calls, discovery saves tokens and causes exposure misses, or discovery matches full exposure and saves tokens, or richer schemas repay their tokens, or tool count predicts nothing once size and ambiguity are controlled.
Experiment B: the observation surface. Given the same underlying data, how does producer-side shaping affect information survival, behaviour, continuation and trajectory cost? Frozen: the tool, source data, query and task, model, decoding, current context, admission budget where relevant, required facts and identifiers, and the oracle answer. For the primary comparison, the consumer admission rule is frozen and attempts to admit the offered observation under the same budget; any refusal or clipping is recorded as an admission outcome, not attributed to shaping. A separate factorial comparison may vary admission. Raw result, shaped candidate and actually admitted size are measured independently. Conditions: raw complete; deterministically filtered or projected; paginated with an explicit continuation contract; a bounded semantic cue with a durable recovery reference; explicitly truncated with a truncation marker; and a fixture-specific oracle observation. The cues must be frozen and their generation cost and status-preservation checks recorded separately from deterministic filtering. Representation forms belong to Chapter 18. Hazard fixtures carry the traps: a tail-critical item; large irrelevant bulk; an exact identifier that lossy shaping cannot satisfy; negative evidence, where the right answer depends on knowing a complete search found nothing; an error whose repair needs an easily omitted detail (error shaping is tested here and not in a third experiment); and a reference whose expansion holds the decisive detail. Measures, separate: raw, candidate, admitted, reference and reintroduced tokens; required-fact, exact-value, provenance and completeness-contract survival; task success, follow-up correctness, false-negative decisions and unsupported claims; and calls, continuations, expansions, latency and total tokens. Outcomes that count: raw matches shaped at acceptable cost; filtering saves tokens and drops the decisive fact; pagination causes premature stops; an explicit truncation marker still produces false absence claims; references save tokens and expansions erase the saving; compact results change exact values; deterministic projection matches the oracle; error shaping removes repair-critical evidence.
Falsifiers. Dynamic discovery would not be justified under the tested conditions if full exposure performs as well at comparable total cost, if discovery misses required capabilities, or if discovery overhead outweighs the occupancy saved. An absence of measured selection interference alone does not disprove a cost-only benefit. Aggressive producer shaping would be rejected if it drops required evidence or triggers false-absence conclusions under the tested contracts. Either mechanism would earn conditional support if it preserves required obligations and behaviour while reducing measured whole-trajectory cost. That finding would apply to the tested workload, provider and settings, not automatically to other tool environments.
The handoff
When a tool system saves context, it either removes unnecessary information or moves necessary information behind another decision that can fail. Dynamic discovery, pagination, references, filtering and truncation each create an access or stopping failure that has to be measured. Chapter 17 settled which capability information becomes model-visible, and how execution crosses into candidate information. Chapter 18 asks the question left open: given information that should be model-visible, what representation should it take?
References
- Wu, B., et al. “Introducing advanced tool use on the Claude Developer Platform.” Anthropic engineering report, 24 November 2025. https://www.anthropic.com/engineering/advanced-tool-use
- Aizawa, K., et al. “Writing effective tools for agents — with agents.” Anthropic engineering report, September 2025. https://www.anthropic.com/engineering/writing-tools-for-agents
- Jones, A., Kelly, C. “Code execution with MCP: Building more efficient agents.” Anthropic engineering report, 4 November 2025. https://www.anthropic.com/engineering/code-execution-with-mcp
- Model Context Protocol. “Tools.” Draft specification, verified September 2026. https://modelcontextprotocol.io/specification/draft/server/tools
- OpenCode. “Tools.” Documentation, verified September 2026. https://opencode.ai/docs/tools/
- Tarquinen. “Dynamic Context Pruning Plugin (DCP).” Third-party implementation, AGPL-3.0-or-later, verified September 2026; the reference is to the repository default branch and is not pinned to a commit. https://github.com/Tarquinen/opencode-dynamic-context-pruning
- Paramanayakam, V., Karatzas, A., Anagnostopoulos, I., Stamoulis, D. “Less is More: Optimizing Function Calling for LLM Execution on Edge Devices.” Accepted at DATE 2025; arXiv:2411.15399, November 2024. Preprint. https://arxiv.org/abs/2411.15399
- Breunig, D. “How Long Contexts Fail.” 22 June 2025. Practitioner synthesis; tool confusion as a context failure mode. https://www.dbreunig.com/2025/06/22/how-contexts-fail-and-how-to-fix-them.html
- Breunig, D. “How to Fix Your Context.” 26 June 2025. Practitioner synthesis; introduces tool loadout as a dynamic selection pattern. https://www.dbreunig.com/2025/06/26/how-to-fix-your-context.html
Research
Not yet researched
This chapter has not yet been researched.