The Measurement Instrument
Observe the context a runtime assembles for a model before attempting to improve it: where the observer sits and what it cannot see, how tokens are counted, and why the instrument has to be qualified before it is trusted.
Imagine a developer debugging a slow, expensive coding agent. The visible transcript shows eight user messages and eight assistant replies. It looks modest. Then they enable request logging at the harness layer and discover that the eighth model invocation carried tens of thousands of tokens: the project instructions re-sent for the eighth time, tool definitions for tools never called in this session, two file reads that overlap almost entirely, and a history that includes four failed tool calls and their stack traces in full. The user typed a few hundred words in the whole session. The harness had assembled a novella.
The numbers in that story are invented, and the story is illustrative, not a finding about how often this happens. The argument does not need it to be common. It needs only this: the visible conversation can differ substantially from the context assembled for a model invocation, so that context has to be observed and not inferred from the transcript. A developer who reasons from the transcript may be reasoning about a document the model never received. The first engineering obligation is therefore not to prune, compress or retrieve anything. It is to look.
The imagined prompt
It is easy to describe what a system sends to the model as the latest user message plus some history and instructions. The context assembled for an agentic turn can contain much more:
system instructions
developer and product instructions
project instructions
tool definitions and schemas
conversation history
summaries of earlier history
files and excerpts
retrieved documents
tool results and observations
images and other media
working state (plans, task lists, notes)
current user input
Each item is placed there by a concrete piece of software making a concrete decision: a harness that prepends the project file, a framework default that appends every tool schema, a history manager that concatenates instead of selecting, a compaction step that replaced six turns with a paragraph nobody inspected. Provider documentation confirms the general shape for one provider: OpenAI describes the cached unit as the model’s full rendered context, including provider instructions, developer messages, tool definitions and conversation history, and describes its text generation requests as stateless unless state is re-supplied. The transcript is the visible part of a structure the harness may rebuild every turn.
Claims about what a particular runtime assembled need evidence from that assembly boundary, or from another instrument that observes the same question. “We added the style guide to context” is ambiguous until we know where it was placed, in what form, on which turns and at what cost. “History is getting too long” is unmeasurable until history is separated from instructions, tools and retrieved material. Observation comes before every later verb in this book. A missing capture does not invalidate every possible claim about a system; it limits which claims this instrument can test.
An observer that only looks
The instrument this book uses is a read-only observer attached to a real coding agent. It sits at the point where the agent’s host has assembled the context for a model call and is about to hand it on, and it writes one record per call.
That position is the measurement boundary, and every later claim has to name it:
available information and session state
                  ↓
          runtime assembly
                  ↓
   [ observation point: the host's model-context hook ]   ← what is recorded
                  ↓
          provider translation
                  ↓
            provider and model
Above the line, the observer sees what assembly produced. Below it, it sees nothing directly. So a result from this instrument says the context was observed at the host’s model-context hook, and does not say that the model saw it. The distinction between what the host hands on and what a provider finally renders is the subject of the section on blind spots, and it is why the book says observed at the boundary and not the model received.
Read-only is a deliberate constraint. An instrument that modifies the request while measuring it cannot establish a baseline, and baselines are the scarcest resource in context engineering. The stated invariant is that observation must not modify the context being delivered: the observer copies the event and a test pins that the original is structurally unchanged afterwards. That is a claim about the context, not about the process. Writing records costs disk and time, and the tests do not measure that overhead.
Each record carries the session and the agent, the requested and observed provider and model, the kind of request, the system material, the messages, the tool definitions, the request options, the model’s limits where the host reports them, a capture time, a sequence number and timings. Two details are worth having in mind.
The messages are not a flat list of strings. Each has a role and a list of parts, and the parts are of distinct kinds: text, reasoning, tool calls with their arguments, and tool results. In this host capture, tool results do not carry a reliable link back to the calls that produced them. Their bodies can therefore be compared to detect repeated content, but content equality alone cannot establish that two results came from the same call, describe the same underlying file version, or have the same significance.
And the sequence number survives restarts. It is reserved before the record is written, so a crash leaves a detectable gap and can never hand the same number out twice. If the state is damaged and the record store cannot vouch for a session, the session is marked incomplete by rule. The principle is that the observer may admit a gap but must never invent continuity. A gap means the observation is incomplete. It does not say what activity was lost.
The observer is one mechanism of a package that also contains an injector, which Chapter 25 describes. Both are off unless explicitly enabled. An instrument that is on by default changes ordinary behaviour, and one that is off by default fails silently, so the second failure needs its own defence.
What looking refuted
The first version of the plan was written before any real capture existed. It specified a record whose fields included authority, scope and cache span, and a set of synthetic sessions to test against. When the observer was finally run against a real session, in a throwaway repository, several assumptions failed.
The messages were not shaped the way every synthetic fixture had assumed. Every fixture had the wrong form, so a real session would have been silently misread, its repeated tool outputs never matching. The fixtures were rebuilt to the real shape, and a record in any other shape is now refused as incomplete rather than analysed as if it were understood.
Tool-call arguments turned out to be captured. They reveal which edits, test commands and repeated calls the agent requested rather than forcing the analysis to infer those requests from surrounding prose. The arguments do not by themselves prove that a file was changed or a test completed; those outcomes require the corresponding tool results or independent state evidence.
The call meant to read the model’s limits did not exist and failed silently, so every limit had been recorded as unknown. It was replaced with the host’s model registry, and a model configured without a limit is now recorded as having none, not as zero.
Provider-reported usage, cost, latency and cache reads turned out not to be invisible: the host keeps them in its own database. They can be read afterwards, read-only. The current join admits a session only when the count of assistant messages equals the count of captured requests, but matching counts are a necessary consistency check, not proof that each usage row belongs to the request it is paired with. Such values are labelled joined, not observed at the context boundary, and per-request conclusions remain conditional on the join being correct. A stronger join would use stable request identifiers or independently checked ordering.
And the record does not carry authority or scope at all. The observer can see where an item sits and what it says. It cannot see who placed it or what it claims to govern, because the host does not say. Those fields, which Chapters 3, 19 and 21 rely on, are not something capture can supply. They have to come from whatever builds the candidates later.
One question was left open and is kept open. The author’s ordinary configuration loads other plugins that can change the context, and it was not established whether the observer sees the context before or after they act. The calibration session was therefore not a plain baseline of the harness as shipped, and any later session records whether such plugins were active.
The lesson generalises: an instrument is a hypothesis about the system it measures. Specified without contact with that system, it will be wrong in ways nobody has thought of, and the way to find out is to run it once, early, on something small, and to record every place the specification was refuted. The instrument has to be qualified against reality before its output is used as evidence.
How tokens are counted
A token count is not one context-free property of a request. It depends on the representation, tokenizer or counting rule, and observation point. For this book, three distinct kinds of count matter.
A count can be declared: the builder of a candidate says how many tokens it has, before assembly, for the representation it declares. It can be estimated by a rule, such as words times a constant or bytes divided by a constant, over the text the observer captured. Or it can be reported by the provider after the call, for the request as the provider rendered it. The first two can be used to budget in advance. The third can only reconcile afterwards.
These are not the same number, and nothing here establishes that they agree. In the observer’s calibration, on one session with one model, a word-based estimate ran roughly a third below what the provider reported for the same requests, while bytes divided by four ran much closer. That is calibration evidence about the instrument on one session, mostly English text and structured data. It does not say how either rule behaves elsewhere, and it does not make bytes divided by four a recommended estimator. It does say that a word estimate should not be the number a budget rests on without knowing which count it is.
Two consequences carry forward. Every count recorded should say which of the three it is, and a compiler’s estimate, a host’s count and a provider’s input_tokens are never assumed to be equal. And when the compiler of Chapter 23 reports that a bundle fits its budget, it means in the units the candidates declared, which is a statement of a different kind from one about the provider’s tokenizer. The tokenizer also changes across models, so cross-model comparisons of token counts are approximate.
Where a measurement comes from
Counts are one case of a general rule: every measurement carries its origin. The instrument uses a small fixed vocabulary.
| Status | Meaning |
|---|---|
| Observed | read directly from the captured record |
| Derived | computed deterministically from observed material |
| Joined | read afterwards from the host’s own record and matched to the session; not seen at the boundary |
| Proxy | a stand-in for the thing wanted, named as such wherever it is used |
| Declared | supplied by a person or builder, never inferred from text |
| Unobserved | the capture cannot see it |
Unobserved must not be silently converted to zero or to a claim of absence. That is the invariant behind everything that follows: absence of observation is not evidence of absence. A quantity unobserved for a session stays marked as unobserved; it is excluded from calculations that require an observed value, and the report states how many sessions were excluded. A share is reported only when its numerator and denominator are supported by compatible measurements. A real observed zero is kept as zero.
Baselines before interventions
With the instrument defined, the chapter can say what it means to have measured a session. A baseline is a set of numbers computed over captured records before any intervention, and the book asks for eight. Most are derived, not stored, and the definitions are deliberately narrow.
- Total rendered input per invocation, across the session. The bytes are observed at the boundary; the token figure is estimated or joined, and says which.
- Tokens by category and source. Instructions versus history versus tools versus files is the minimum useful cut. Category assignments are derived from the recorded type and role of each part where those fields are sufficient; finer source attribution is unavailable when the host does not identify provenance. Token amounts within those categories remain estimated, declared or joined as labelled, not directly observed token counts.
- Repeated material. Two narrow meanings: a part re-sent unchanged from an earlier request, and the same tool-output body appearing more than once inside one request. Both are byte-level and derived, and neither detects material that repeats in meaning without repeating in bytes.
- Growth over turns. Total and per-category counts against turn number.
- Stable prefix size. The leading span identical to the previous request. This is a proxy: it assumes a render order, and the provider’s actual order is not observed.
- Tool-definition overhead. The names, descriptions and schemas present in a captured request, including definitions of tools not called in that session. Their presence is observed; their token cost at the boundary is estimated unless an appropriate tokenizer or count is available. Presence does not prove the provider rendered them unchanged. Vendor engineering guidance likewise treats tool descriptions and responses as context costs to be designed for efficiency.
- Tool-output growth. Tokens from tool results and their share of the bundle over time.
- File and retrieval contribution. Tokens from project files, excerpts and retrieved documents, separated from history, so that “the model knew the codebase” can be checked against what was shown. This is separable only as far as the record names where material came from.
Each later intervention in the book (deduplication, pruning, compaction, externalisation) must move at least one of these numbers and then show, by a controlled comparison, that behaviour survived or improved. A chapter that claims savings without a before and after on these baselines has made no claim.
A worked capture
Here is turn five of a debugging session, in the form a capture would take. The categories and token counts are invented for illustration and are not a measurement; a real table would carry measured counts, labelled with which kind of count they are.
project instructions (stable, turns 1-5)      1,900
tool definitions (stable, 14 tools)           6,200
conversation history (turns 1-4, growing)     9,800
prior summary (written at turn 4)               900
re-read source files (2 files, 80% overlap)   7,100
tool results (test output, search hits)       4,900
current user message                            120
environment state                               480
Three things become visible before any intervention is contemplated. In this invented table, the user’s message accounts for under half a per cent of the illustrated total. The two largest categories are history and files, and the example assumes substantial overlap in file reads and unchanged tool definitions re-sent across five turns. A real observer would need the underlying content comparisons to support those last two observations; the table of category totals alone cannot establish them. The example shows how a categorised capture makes hypotheses testable. It says nothing about the frequency of these patterns in real sessions.
Stable and dynamic
Of the derived properties, stability deserves emphasis because it connects observation to economics, and three different things need keeping apart.
The first is an observed property: a span is byte-identical across captured requests, like the project file nobody edited. A dynamic item is regenerated, appended or replaced: new tool results, fresh retrievals, the latest user message, a re-rendered timestamp.
The second is a provider mechanism. OpenAI’s documentation states that cache reuse requires the entire rendered prefix to match, and that summarisation, compaction or truncation can change the prefix and reset reuse. Under such a mechanism a stable leading span can enable reuse and volatile material near the front can prevent it.
The third is an economic consequence: that a particular arrangement actually reduced cost or latency. The first two do not establish it. Provider-reported cache metrics, joined afterwards, give the provider’s account of what received cache treatment, and not why. They are the provider’s report and not something the observer saw, so neither record alone is a complete end-to-end observation.
Stability also has to be kept apart from usefulness. A perfectly stable item can be useless or harmful, and a volatile one can be essential. Stable material is also background to every turn and rarely re-read, so a stale project rule can keep exerting influence, which is a reason to inspect it.
Repetition is stability’s companion, and growth without repeating (new observations) calls for a different response from repeating without growing (the same preamble re-sent). The instrument keeps them separate.
Measuring is not improving
measuring context ≠ improving context
Every technique the book will test is, at this stage, an unexamined proposal. Showing that history can be summarised is not showing that it should be. Counting duplicate tokens is not removing them. And removing them is not yet an improvement: a smaller total, a stabler prefix or a shrunken category is a measurement difference, and whether behaviour, cost or latency improved is a separate result that needs its own comparison. Chapter 1’s rule applies: a usefulness claim holds under the stated comparison conditions and only there.
Sometimes the waste and the fix both look obvious. The instrument still matters. Obvious waste is often load-bearing: the duplicated instructions may be the only reason the model obeys them, so removal must be tested, not assumed. And per-item records are what make the test possible.
The shape of growth is a useful place to start, as a diagnostic heuristic and not an established signature. Steady accumulation is the simplest case, though it can be useless accumulation. Accelerating growth, where tool outputs trigger further calls whose outputs trigger more, may be productive investigation or thrashing. A step change may point to a large file read, a paste or a compaction, and deserves to be named by category and not absorbed into an average. The shape tells us where to look. Whether behaviour would survive the absence of the categories that drive it is a question a baseline cannot answer. It tells us where to run the ablation.
What the baselines are expected to show
The book does not yet have a corpus of real sessions to answer that. What follows are predictions, stated as hypotheses to be confirmed or refuted by frozen measurements, and none of them has been tested.
Book hypothesis. In real multi-turn coding traces, repeated and stable-but-unexamined material will make up a large share of rendered tokens, and the user’s own words will be a small minority.
More specifically: tool definitions are a large fixed cost from the first turn; history and tool output dominate growth; project instructions are re-sent unchanged where re-sending buys nothing; and overlapping file reads recur because each retrieval is issued without consulting what the bundle already holds. If real bundles turn out lean, non-repeating and user-dominated, several later chapters lose their motivation, and the report will say so. A baseline that cannot surprise us is not a baseline.
Book hypothesis. Small amounts of volatile material placed early in the rendered order will account for a disproportionate share of cache-prefix invalidation.
This is a session-level prediction built on a documented mechanism, and it still needs measurement. The chain is documented prefix-matching, then the prediction, then a future measurement of how often timestamps, session identifiers or reordered blocks break an otherwise stable prefix. Even then, the observer’s stable prefix is a proxy under an assumed order.
The instrument has been run against a deliberate calibration session in a throwaway repository, to test the tool. That session is excluded from the corpus used to assess the two hypotheses and contributes no evidence about their prevalence. It does, however, provide the narrow calibration evidence described earlier: that the instrument encountered real host data and that two token-estimation rules differed in their agreement with provider reports on that session. The corpus of genuine sessions for evaluating real-work patterns is empty. This is where the book states the gap in full: it holds structural, transport and behavioural evidence on synthetic cases, plus limited real-session instrument calibration, but no evidence yet about how often these context problems occur in ordinary work. The book calls evidence of that last kind ecological. Chapter 26 sets it beside the three other kinds this book collects, and Chapter 27 says how much of each exists.
Inspect this in the Context Viewer
The viewer scene for this chapter replays the instrument as a labelled fixture: five fields by measurement status, a live observer that records an actual zero, an inactive observer that records nothing, and a flagged sequence gap. Open the scene and read each value’s status before trusting it. What to examine: which numbers are observed, which are derived or joined, and what the gap admits it does not know. This is a constructed illustration of the status vocabulary; it establishes no provider fact and no prevalence claim.
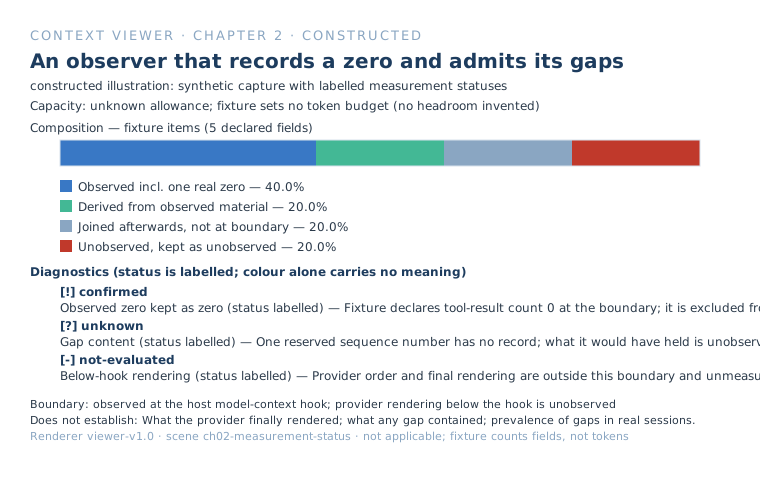
Open the instrument scene in the Context Viewer
What the instrument cannot see
The observer sees the assembled context at one place: the host’s model-context hook, before the runtime translates what it has into whatever a provider expects. Everything after that point is invisible to it.
model-context observation ≠ provider-wire capture
The blind spots differ in kind, and the difference matters. Some unobserved material is known to exist: server-side state such as provider-stored conversation items or compacted representations is not invented, and encrypted or redacted spans such as reasoning items replayed opaquely are recorded as present but unreadable. Some is recoverable with other instruments: provider-reported usage, joined afterwards, shows how far one can go. The rest is closed: the provider’s cache decisions, anything the provider adds after the observation point, the order in which it renders the request, whether reasoning material reaches it, how the system block is split among harness, project and user, and the relations between a parent agent and its subagents. The state of the repository is not part of the capture at all, and whether the observer sees context before or after other context-modifying plugins is, as above, not established.
The set of things the instrument does not see has to be a first-class part of every result that uses it. A capture that silently drops what it cannot parse is worse than none, because its totals reconcile and its blindness is invisible. Captured context can contain sensitive material, so it stays local and is never committed, and the corpus needs the same handling as any production log.
An item that is not present at the observation boundary cannot be counted by the observer, and that is a fact about the boundary and not about the item.
Capture also changes incentives: once a team watches token counts, categories can shrink cosmetically and material can move to unlogged channels while outcomes do not improve. The defence is the book’s standing rule that no optimisation counts without a controlled behavioural comparison. The instrument reports. The experiment decides.
The instrument has to be qualified
A logger records. A measurement instrument has a defined boundary, a record schema, a stated origin for every number, known blind spots, rules for when a session counts as complete, calibration against reality, and evidence that it was running. The last property is the one most often missing, and the book returns to it at length. An observer that is not running looks exactly like an observer that saw nothing.
A record store that is empty proves nothing about model activity. The observer may have been disabled, attached to a different process, unable to write, or simply presented with no eligible model calls. So the observer is not trusted because it is installed, or because its version is right, or because its files match. A trustworthy measurement establishes that the observer was enabled, that it captured a known event, that the event belongs to the run being analysed, that its record was persisted intact, and that the sequence rules reveal no detected gaps. A contiguous sequence is not proof that every model invocation was intercepted: calls made before attachment, outside the hook, or without a reserved sequence number remain outside that guarantee. Complete therefore means complete under the observer’s defined capture and sequence rules, not a complete view of the provider’s final prompt or a representative sample of real work.
This chapter states the requirement. Chapter 25 tells what happens to an experiment that skipped it.
The question this creates
Once the assembled context is visible and counted, the question changes from what the system sent to where each part of it came from. Instructions written by the vendor and the product team, tool schemas generated from code, project files injected by the harness, histories and summaries accumulated without any explicit act: each has an origin the user did not type. Whether they dominate real requests is an empirical matter, and this chapter has not measured it. The next one opens the object and asks.
If we inspect a real request, how much of what the model receives did the user never explicitly type?
References
- OpenAI. “Prompt caching.” Official documentation, verified September 2026. Full rendered context as cache unit; requirement that the entire rendered prefix match; compaction and truncation can reset reuse; cached tokens reported in usage. Provider-specific. https://developers.openai.com/api/docs/guides/prompt-caching
- OpenAI. “Conversation state.” Official documentation, verified September 2026. Text generation requests are independent and stateless unless state is supplied. Provider-specific. https://developers.openai.com/api/docs/guides/conversation-state
- Anthropic. “Writing effective tools for agents — with agents.” Published 11 September 2025. Vendor engineering guidance; tool responses consume context and should be designed for token efficiency. https://www.anthropic.com/engineering/writing-tools-for-agents
- Project Context OpenCode. Source repository, Apache-2.0 licence, first-party code by this book’s author. The read-only observer, its record format and its calibration notes. https://github.com/ernanhughes/project-context-opencode
Research
Not yet researched
This chapter has not yet been researched.